

Barely technical and feeling behind on AI? Same. Shipped a real product with AI, without a CS degree or a dev team. Follow for the how, one build at a time.
Joined January 2025
- Tweets1.9K
- Following339
- Followers253
- Likes3.8K




The default font on Omarchy is beautiful! Makes other operating systems ugly.
There are a lot of other aesthetic things about Omarchy, but the font is just too difficult to ignore.
Not sure why a lot of people are not talking about it.
Most vibe coded apps have one fragile line in them. It is the prompt that says "reply with only yes or no" and then hopes the AI actually does.
A model launched this week that exists only for that line.
It is called Jev. It does not chat, write, or explain. You give it some text and a question with fixed answers, and it hands back a percentage for each answer plus a number for how sure it is.
Is this signup spam. 91% yes. Which bucket does this expense go in. Travel 84%, meals 11%, other 5%, confidence 0.8.
That "how sure" number is the part I have never had. Every check in my own app runs through a chat model, and eight calls on one identical photo once split 5 to 3 between two answers. Nothing in the reply told me it was unsure.
With a confidence number you can write the one rule every app needs. If it is sure, do it. If it is not, ask a person.
The price is $0.042 per million tokens in and nothing out, because it never writes anything out. One check on a page of text costs about three thousandths of a cent and comes back in a tenth of a second.
It is waitlist only, it cannot see images, and it cannot invent an option you did not give it. But if your app makes small decisions all day, this is what those calls should have looked like from the start.
For the engineers, It is a zero shot classifier with calibration training, and the founder agreed with that framing on Hacker News. The 193x speed claim is against LLMs running full chain of thought, and its benchmark grades against the average of two other models' answers. Test it on your own data before you trust the headline number.
The agent was repairing the graphics driver.
Every screenshot on that machine is produced by that same driver. So a screenshot cannot prove the driver works.
The webcam does not go through the driver. Point it at a mirror and the agent gets a witness the bug cannot touch.
That is the reusable part. When an agent checks its own work, the check has to come from outside the thing it changed.


Everyone agreed memory is the rate limiter.
Almost nobody said which memory they meant.
Builders heard context windows. A week earlier, SpaceX and Tesla had committed $16.8 billion to a fab that makes its own logic and memory.
Those are the same constraint seen from opposite ends.
Generating a token is mostly a read, not a calculation. The model streams its weights and its accumulated context out of memory for every token it produces.
An agent makes that worse on purpose. It keeps state, re-reads it every step, and takes hundreds of steps where a chat takes one.
Add FLOPs to that and very little happens. The accelerator sits waiting on the memory bus.
So agent memory and high bandwidth memory are not two subjects. Agent memory is the workload, HBM is the pipe, and the pipe is the scarce part.
Three companies make over 95% of the world's DRAM, and every wafer they move to HBM is a wafer that never becomes the RAM in a laptop.
TrendForce has conventional DRAM contract prices rising 58 to 63% this quarter. J.P. Morgan puts the full move above 400% between the start of 2024 and the end of 2026, and expects the shortage to run for years.
That is what the rate limiter really is. Not a flaw in anyone's agent framework, but an allocation decision made by three suppliers that then reprices hardware for everyone standing downstream.
Which is why the response taking shape is a building rather than a framework.
When the bottleneck moves from compute to memory, leverage moves from whoever trains the best model to whoever decides where the wafers go. A fab is the only way out of being a customer of that decision.

Naval says people who are serious about software train their own models.
It is the most expensive advice in AI right now.
That is Alan Kay's advice about hardware, and hardware never lost half its value in ten weeks.
Opus 4.8 scored 18.7 on Frontier-Bench in May. Opus 5 scores 43.3 now, at the same price. Anything you trained in May is behind what you can rent today.
And training would not have saved my worst run anyway.
Last month I ran the same coding model, same spec, same harness, on two different days. Sunday it went 12 of 12. Monday it went 0 of 12, ran for 26 minutes, billed me $0.92, and never wrote the page.
Owning those weights would have changed nothing. The failure was in the run, not the model.
What caught it was a pass/fail list I wrote before the run.
That list is the part that compounds. It works on a model I trained, a model I rent, and whatever ships in October.
Anthropic confirmed a custom chip team today without any timeline, fab decision, spec for what the chip actually does.
A serious chip program is a $500M line item. Nobody spends that to save money on hardware.
The real news is the hiring brief for engineers with experience spanning hardware and software, to codesign the chips and the models together.
Google is the only company that has ever closed that loop, with TPUs and Gemini.
Compute is a lab's cost of goods. Every price cut shipped this year was a bet that cost per token keeps falling, and the models getting smaller was never on the table.
Last week I ran 100 image generations through a product I built. $3.28.
I never negotiated that number. It was settled years ago by someone choosing a memory architecture.
Every app built on an API is renting margin from a chip roadmap it has no vote in.
HeyGen shipped a tool yesterday that turns a document into a two host video podcast. Studio set, cuts between cameras, B roll. Over two million views on the announcement.
The feature is not new. They have had a video podcast in beta since late 2024, and that version already turned a PDF into two people talking.
So what shipped yesterday is not the podcast. It is the production. The camera operator, the editor cutting between two angles, whoever went and found the B roll. That whole layer.
HeyGen is at $200M ARR, doubled in a year, and has burned $25M of the $74M it raised. Those numbers do not come out of a software budget. They come out of what a company used to pay a crew.
I noticed because I spent yesterday doing the same thing to a photo studio. A hundred frames, four garments that do not exist, $3.28, no photographer.
Making it look finished used to be the filter. Ideas were never scarce. Finished things were.
Now that filter is going, and the interesting question stops being who can make a show. It becomes whose show anyone bothers to watch.

Video Podcast is live.
Turn any doc, link, or idea into a two-host video show with studio scenes, multi-cam cuts, and B-roll. Ready in minutes.
Everyone else stops at audio. This is a show you can publish.
Try it: app.heygen.com/apps/video-po…
Today I ran 100 images through my product, answered four questions I had been putting off, and found two bugs I did not know existed. On a Thursday.
Not one of those images is a photograph. The clothes are not real either. I needed a denim jacket shot front and back, a keyhole dress, a box pleat shirt. I own none of that. It used to mean a wardrobe, a model, a studio and about three weeks of calendar. Today it was an afternoon and $3.28.
And I did not find both bugs. Claude did, going back through its own output while I was reading something else. One of them was sitting in the live product.
Somewhere in the middle I lost track of what had even been generated, so I asked for all of today's images to be dropped in a folder. It built me this instead.
claude.ai/code/artifact/30ff…
I have read the word acceleration a hundred times this year. Today is the first day I actually felt it.

Everyone is calling this the singularity. I have shipped enough agent built software to guess what comes next.
The first output looks like this. Genuinely great, faster than you thought possible.
Then you spend 3 days on the last 10 percent, and it is always the plumbing. Fields that got renamed, imports that got duplicated, an API shape the model guessed at.
My last delegation shipped 2 features and left 6 defects. Every one was an integration error. Zero logic errors.
The demo is real. The distance between demo and shipped is also real, and it has barely moved.

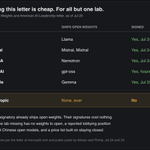
Anthropic is now the only frontier lab that has not signed the open weights letter.
OpenAI signed within hours of Jensen's post. Google signed today through Sundar. The consensus take says Anthropic caves next, because being the lone holdout in the middle of a Washington fight looks terrible.
I think the consensus has this backwards. Anthropic is the one lab that cannot sign cheaply.
OpenAI ships open weight models of its own. Google ships Gemma. Their signatures cost nothing. Anthropic has never released open weights, reportedly lobbied for the Chinese open weight restrictions this letter opposes, and just spent 19 days in June with its flagship suspended by an export order.
Signing would reverse an active lobbying position and erase the one thing that makes them different. Their new pricing already monetizes the closed position. The risk tier carries the premium.
So my call is that Anthropic does not sign. What we get instead is an essay. Something long and thoughtful about how open and closed both matter, with a warning about frontier weights, and no signature under the letter.
If they sign within 2 weeks, the pressure beat the incentives and I was wrong. Logged either way.

Anthropic just shipped a 5 dollar model that beats its own 10 dollar flagship on the flagship's headline benchmark.
Opus 5 scores 43.3 percent on the company's hardest agentic coding eval. Fable 5, launched 6 weeks ago at twice the price, scores 33.7. Opus 4.8, released in May at the same price as Opus 5, scored 18.7.
Performance more than doubled in 8 weeks with no price change.
So what does the 2x premium on Fable buy now? Read the fine print and the answer is strange.
Opus 5 trails the Fable tier in exactly 2 places, offensive cybersecurity and biology research. The dual use capabilities. The ones that got Fable export controlled and suspended worldwide for 19 days, restored July 1. The ones safety classifiers block most paying users from touching anyway.
The gap is deliberate. Anthropic says it withheld frontier cyber training from Opus 5 on purpose, and that its classifiers will reportedly fire about 85 percent less often than Fable's.
The product line has quietly reorganized around risk. The cheap model carries the intelligence. The expensive model carries the liability, plus the classifiers and regulatory exposure that come with it.
For coding and knowledge work, the premium model is now the worse deal by every published number. The 2x looks less like a capability premium than a risk surcharge, billed to whoever insists on paying it.
30 years building the company that made all of this possible, joins X, and spends the first post on a policy letter.
The restraint is unbelievable.

For my first post, I’m sharing a letter @NVIDIA signed on why open models matter.
AI will transform every industry, power every company, and be built by every country.
Open models strengthen safety and cybersecurity, accelerate innovation and diffusion, and enable sovereignty.
The world needs both frontier closed models and frontier open models.
images.nvidia.com/pdf/Open-W…


On Monday I said the ban on Chinese open weights gets announced loud and dies quiet, because the incentives were pointing the other way. Microsoft was reportedly already testing K3 for Copilot at around $600M in savings while Washington debated banning it.
Three days later Microsoft is signing an industry letter asking policymakers to avoid premature restrictions on open models.
Worth being precise about what that proves. It does not prove the ban died. The incentive I described has stopped being private and started lobbying, which is the mechanism running, and the verdict is still open.
The tell I gave still stands. If the final rule covers federal procurement and nothing else, the money won and the announcement was theatre.
My reason for caring is smaller than any of this. K3 matched Claude 12 for 12 on my spec last week and cost about a third as much. When the fight is over whether I keep the cheap option, I would rather hold the number than the opinion.

Everyone's worked up about the White House talking about banning Chinese models after K3 dropped.
My take is we don't have to worry. This gets announced loud and dies quiet, somewhere between a few weeks and a few months. Not because anyone changes their mind, but because everyone's incentives already point the same way.
Start with the incentives. While Washington debates the ban, Microsoft is testing K3 for Copilot on Azure, chasing something like $600 million a year in inference savings. The government would be banning the model its biggest company is busy procuring.
The math checks out at my scale too. I benchmarked K3 against Claude on a real product spec last week and got quality parity at roughly a third of the cost. A ban does nothing to Moonshot's revenue. It just taxes every US builder who complies while competitors abroad keep the discount.
And you can't really ban a file anyway. The full weights go public July 27. Within a week they'll be downloaded, mirrored, and retrained inside half the companies a ban would cover. You'd be banning math after it left the building.
We've watched this movie before. In the 90s the US classified encryption as a munition, so people printed PGP's source code in books because books were protected speech. The controls were gone by 2000. DeepSeek bans shrank down to government devices. TikTok got three deadlines and is still here.
So it'll go the way these always go. Announce broad, enforce narrow, quietly let it slide.
And if the final rule only covers federal procurement, that's the admission. They already know they can't enforce anything bigger.
The Indian government has asked GitHub to delete the source code for bitchat.
Phones talk straight to each other over Bluetooth. No towers, no servers, nothing in the middle to lean on.
So when students kept coordinating through a network blackout in central Delhi, the state ran out of switches to flip. The only surface left was the repo.
That is the week in order.
An exam gets leaked.
A generation protests.
The networks go dark.
The kids route around the blackout, and routing around it is now the unlawful act.
You don't need a dictatorship declared.
You just need every layer of the stack to answer to one office.
The order fails anyway. The license is MIT, the forks number in the thousands, and the protocol does not live on GitHub. It lives on every phone that already installed it.
You can take down a repository. You cannot recall the handsets.


Semantic search has no concept of time. Save a better version of an old note and cosine similarity happily returns the stale one.
So ranking in my second brain decays on purpose. Every result gets a small recency boost that fades out over about 90 days, capped low enough that meaning always wins.
A fresh item beats a stale near duplicate in a near tie. It cannot beat a genuinely better match.
I stopped filing and tagging entirely. The decay does that job now.

The other 4 design decisions, and what each one costs at rest, are in the article.
xitter.cf/saiships/status/207668…
The whole build is open, MIT, no waitlist.
github.com/nullhypeai/second…
