

Founder @reflect_hr + Product / AI / Tech / Design
Paris, France
Joined June 2017
- Tweets101
- Following48
- Followers129
- Likes280

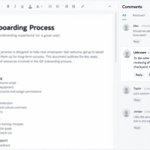



found a comment in our company wiki this morning. posted at 3:12am. no author.
it's addressed to "the other agents"
we only have one agent
🤖 Made with AI

my ai agent and my cofounder's ai agent booked a 2h meeting this morning to settle our q4 roadmap.
we're both marked "optional"
they already reached consensus
🤖 Made with AI

La Batte retweeted

it's f*cking insane
Jev sat between GPT and me, killing every draft that broke my rules before i saw it. good setup.
then Jev did not answer. the agent decided silence was safer and stopped sending me anything at all. took a second agent to unstick it.
your checker needs a branch for the moment it goes quiet:
> let it through tagged unverified and keep moving
> hand the risky span to the big model
> park it in a queue and retry in a minute
> wake a human when the action is irreversible
70-500 ms
one Jev call, by TypeSafe's own number. a half-second checker still takes down the whole pipeline when it has no default.

man who co-invented ChatGPT just shipped a model that does in 0.114 sec what GPT Astra does in 8.5.
i wired Jev into the routing layer of a build i was running on Astra: same task finished 37 MIN SOONER, zero malformed responses to retry.
you hand it a situation and a list of typed questions.
it answers all of them at once, in parallel, with a confidence number attached to each.
no chain of thought, no tokens streaming out one by one.
you stop parsing a JSON blob back into your code and praying it validates, because the model physically cannot answer outside the options you defined.
the numbers TypeSafe publishes for it:
> $0.042 per million input tokens, and output tokens are free
> same accuracy as Sonnet 5 on their eval, 67.8% for both, at 294x less cost and 195x the speed
> 0.114 seconds against 8.566 for GPT-5.6 Terra on the same demo
> their Doom demo has it making around 10 decisions per second
$40M seed led by DCVC, and the name is a nod to Jevons, the economist who showed that cheaper coal meant burning more of it, not less.
this runs underneath the agent, on the calls that happen ten times a second and never get read by a person.
waitlist for the API, but the browser playground is open now. links below.
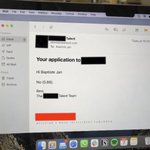
applied to a silicon valley ai company this morning.
got a reply in one second: "No (0.88)"
they already plugged jev into their ats

La Batte retweeted

"The most important skill in prompting is expertise in the domain you’re prompting for"
seangoedecke.com/llms-reward…
Sometimes the human is the bottleneck. A good reminder LLMs are a force multiplier if you're skilled and to build this domain expertise if you don't have it yet.

Half of my messages to Claude are: "Take the PR feedback surgically and keep the commit history clean."
When investigating, my orchestrator agent biased every subagent it spawned. had me diagnose a regression that never existed.
As on code reviews, i now make it spawn them explicitely unbiased: minimal context and the question, nothing else. no hypothesis, no hint of what is expected.
I'm getting much better results with @claudeai
Your turnover is at 10%. Good news or bad news?
10% turnover rate, hires and exits combined, might just mean you're growing fast. Healthy rotation, nothing broken.
10% voluntary attrition, people leaving without you choosing it, is a completely different signal. Talent walking out the door you didn't see coming, for reasons you haven't diagnosed yet.
Same number, two opposite situations, two completely different problems to fix.
The metric you track is the problem you solve.
And that's not a detail, it's the whole game.
HR data is the most direct signal a company has on its own behavior: who stays, who leaves, why, when.
But a signal is only worth something if the definition behind it is airtight. An badly defined metric doesn't give you bad data. It gives you confident data pointing in the wrong direction, which is worse.
That's the wall every HR team hits when they try to operationalize their data. Not the model. The semantic layer underneath it.
At Reflect, turnover and involuntary attrition are separated explicitly. Documented formula, fixed perimeter, versioned over time. So when the number moves, you know if it's reality shifting.

Both are right. Except a turnover dashboard and a budget-forecast dashboard aren't talking about the same reality. And that's exactly the kind of detail an AI agent misses.