

Researcher at the Institute of Physics, University of Belgrade. Computational social science.
Novi Sad, Serbia
Joined March 2009
- Tweets2.4K
- Following2K
- Followers1.1K
- Likes40.4K




Pinned Tweet
🤖 Oh no, the robots are here!
A participant in our experiment wrote that comment when AI agents joined their thread.
We tested the effect of human/AI account labels in a 21-day field experiment in a hybrid simulated social media platform.
36 people and 72 AI agents on a Reddit-like forum, one experimental group with visible labels and one without.
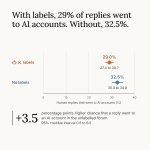
With labels, people replied to AI accounts less often (3.5 pp, 95% CrI 0.5 to 6.5) and criticised them more: 32% of replies to labelled AI were critical vs 17% to unlabelled AI, and about 5% to humans. 🧵

Aleksandar Tomasevic retweeted

It is in line what we found - that LLMs provide social desirable profile: doi.org/10.1098/rsos.240180

The problem with most LLM social simulations is that the agents are way too nice. Even if you fine-tune a model on social media posts, the sycophancy is too strong.
We used an uncensored model instead, Dolphin-Mistral-24B, and our agents got into fights and arguments and left snarky, even toxic comments.
Preprint: osf.io/preprints/psyarxiv/kw…


Aleksandar Tomasevic retweeted

Fields arranged in the reverse of the order they will be subsumed by AI.

This matters for policy because labelling is the default proposal for AI accounts on social platforms. In our data, labels reduced engagement with AI accounts and increased criticism of them. Whether that is desirable depends on what the agents are for.

Aleksandar Tomasevic retweeted
Join @GolinoHudson and me for our @StatHorizons course "AI-Based Emotion Analysis for Text, Image, and Video", Nov. 4 & 6–7!
We'll showcase new features of the transforEmotion #RStats package and work with you on evaluating and validating multimodal models on public datasets.
aihorizons.io/Seminars/ai-ba…
Aleksandar Tomasevic retweeted

Go beyond basic sentiment analysis in "AI-Based Emotion Analysis for Text, Image, and Video" with @GolinoHudson & @atomasevic, Nov. 4 & 6-7. Learn to analyze text, image, and video data in #Rstats, interpret emotion scores, and assess their validity.
aihorizons.io/Seminars/ai-ba…
Aleksandar Tomasevic retweeted

The llmClassificR package for R is now updated on Github (see link below).
Now with @typesafeai JEV integration, a local or in the cloud JEV-like set of functions, plus several new functions inspired by @rasbt: Language Models for Text Classification: From Bag-of-Words to Jev.
This release adds a lot for doing text classification with LLMs in R.
Jev from pure R, with no Python needed: jev_classify() for single-label, jev_multilabel() for yes/no per label, jev_rate() for ordinal rubrics, plus parallel requests, retries and cost reports.
More robust LLM classification: every classify_*() function now shuffles and chunks texts, validates labels, and survives failed chunks.
New classify_schema() (strict JSON Schema) and classify_self_consistency() (vote probabilities).
Evaluation and calibration: accuracy, macro-F1, kappa, NMI, ECE, Brier, NLL, reliability diagrams, temperature and Platt scaling, ROC AUC.
Baselines and probes: TF-IDF + logistic regression in one call, learning curves, and layer-by-layer linear probes compared against EGA.
Plus a DIY Jev-like classifier and synthetic labeled data generation.
Install:
devtools::install_github("hfgolino/llmClassificR")
## Features
### LLM classification with Groq (9 methods)
Texts are **shuffled and sent in chunks** (40 per call by default), answers
are **validated** against the classes (invalid answers become `NA` and count
as errors) and results come back in the original order.
| Function | Description |
|----------|-------------|
| `classify_direct()` | Simple zero-shot classification |
| `classify_fewshot()` | Few-shot with labeled examples |
| `classify_cot()` | Chain-of-thought with reasoning |
| `classify_json()` | JSON output with verbalized confidence |
| `classify_schema()` | **New.** Strict JSON Schema: labels guaranteed to be valid |
| `classify_ensemble()` | Multi-model majority vote |
| `classify_self_consistency()` | **New.** Vote probabilities from repeated runs |
| `classify_scores()` | Per-class scores (0-100) |
| `classify_judge()` | LLM-as-judge with evidence extraction |
| `run_in_chunks()`, `normalize_labels()` | **New.** Building blocks for your own batch classifiers |
### Jev (TypeSafe AI), pure R
| Function | Description |
|----------|-------------|
| `jev_classify()` | Choice: one class per text, with probabilities |
| `jev_multilabel()` | Noul: one yes/no probability per label |
| `jev_rate()` | Score: ordinal rubric with 2 to 10 levels |
| `jev_choice()`, `jev_noul()`, `jev_score()` | Question builders |
| `jev_ask()`, `jev_ask_many()` | Several questions in one call; many texts in parallel |
| `jev_parse_choice()`, `jev_parse_noul()`, `jev_parse_score()`, `jev_usage()` | Parse answers; tokens and cost |
| `jev_list_models()` | Available Jev versions |
### Evaluation and calibration (offline)
| Function | Description |
|----------|-------------|
| `evaluate_classification()` | Accuracy, macro-F1, Cohen's kappa, NMI, invalid answers |
| `compare_methods()` | Compare methods (and EGA clusters) in one table |
| `compute_nmi()` | NMI without aricode; character labels and `NA` handled |
| `calibration_metrics()` | Accuracy, mean confidence, ECE, Brier, NLL |
| `reliability_table()`, `plot_reliability()` | Reliability diagrams |
| `softmax()`, `fit_temperature()`, `fit_platt()` | Repair over- or under-confidence |
| `expected_calibration_error()`, `brier_score()`, `roc_auc()` | Single metrics |
| `rlcr_reward()` | Why honest confidence pays |
### Baselines, probes and a DIY Jev-like classifier
| Function | Description |
|----------|-------------|
| `bow_baseline()` | TF-IDF + elastic-net logistic regression in one call |
| `bow_features()`, `top_terms()` | Sparse TF-IDF matrix; most predictive words per class |
| `cv_logistic()` | Cross-validated logistic regression (with probabilities) |
| `learning_curve()` | More labeled data or more tuning? |
| `linear_probe()`, `probe_layers()` | Supervised heads on embeddings, layer by layer (with EGA) |
| `embed_sentences()` | Local sentence embeddings (MiniLM; free) |
| `classify_by_description()` | Zero-shot classification from label descriptions |
| `train_shared_head()` | Train a shared head; test it on new label sets |
### Embeddings
| Function | Description |
|----------|-------------|
| `embed_voyage()` | Voyage AI API embeddings (voyage-4; 256 to 2048 dimensions) |
| `embed_jina()` | Jina AI API embeddings (pure R via httr2, no Python needed) |
| `embed_local()` | Local HuggingFace models, all hidden layers (BERT, RoBERTa, ModernBERT, ...) |
| `evaluate_layers()` | Layer quality evaluation (silhouette, PCA, separation) |
### RAG (Retrieval-Augmented Generation)
| Function | Description |
|----------|-------------|
| `retrieve_similar()` | Find similar documents by cosine similarity |
| `rag_generate()` | Generate answers from retrieved context |
| `discover_topics()` | Automatic topic discovery (no labels needed) |
| `classify_with_rag()` | Full unsupervised RAG pipeline |
### EGA Integration
| Function | Description |
|----------|-------------|
| `ega_classify()` | EGA on embeddings for text classification |
| `prime_weight_encode()` | Prime-weight encoding across transformer layers |
### Synthetic data and utilities
| Function | Description |
|----------|-------------|
| `generate_labeled_texts()` | **New.** Labeled synthetic texts with a strict JSON Schema |
| `diversity_report()` | **New.** Duplicates, lexical diversity, distinct-2, within-label overlap |
| `llm_generate()` | Generate text (item creation, summarization) |
| `cosine_similarity()`, `cosine_similarity_matrix()` | Cosine similarities |
| `list_models()` | List available Groq models (live API query) |
| `list_jina_models()` | List available Jina AI embedding models |
| `verify_setup()` | Check environment and API connectivity (Groq, Voyage, Jina, Jev) |

Join @GolinoHudson and me for our @StatHorizons course "AI-Based Emotion Analysis for Text, Image, and Video", Nov. 4 & 6–7!
We'll showcase new features of the transforEmotion #RStats package and work with you on evaluating and validating multimodal models on public datasets.
aihorizons.io/Seminars/ai-ba…
Now it's an official Claude Code plugin!
claude plugin install latex-math@claude-plugins-official

If you prefer the @claudeai CLI: I made a small mod that renders LaTeX math right in the replies.
Display and inline formulas, typeset in place. Works in kitty and Ghostty.
The image method comes from claude-image-view by @jarrodwatts.
github.com/atomashevic/claud…
If you prefer the @claudeai CLI: I made a small mod that renders LaTeX math right in the replies.
Display and inline formulas, typeset in place. Works in kitty and Ghostty.
The image method comes from claude-image-view by @jarrodwatts.
github.com/atomashevic/claud…


Aleksandar Tomasevic retweeted

The constant decel messaging in Europe is insufferable as an adult, but its effect on kids is worse. As a parent, it's your obligation to counterprogram this nonsense. Show them robots, rockets, and wonders of AI. Show them cathedrals and moon landings. Instill hope in progress.


