

Harness Engineer // building agentic infra and chasing the singularity // 1x Acquired • CTO @QORIS_AI 📩 DMs open for advisory · Europe CET · remote
talk harness with me →
Joined December 2024
- Tweets1.7K
- Following563
- Followers1.4K
- Likes31.1K



My minimal Pi setup for using Sol 6.1 instead of Codex:
- pi
- web_search (exa + duckduckgo as a fallback)
- web_fetch (direct Node request with .md conversion)
- subagents (tintiweb/pi-subagents plugin)
- system prompt adapter
I find this combination outperforming regular Codex CLI setup.
Gave Grok 4.7 control over my browser.
It encountered recaptcha "I am not a robot" box.
With no thoughts it clicked in the box and got through successfully.
Gave the same task to Opus 5.5 -> it stopped on the captcha and asked me to solve it.
Grok vs Claude, 1:0
When working with long-running /goal sessions on my personal laptop, I find it practical to give the model a way to track the CPU load and the temperature with a running background monitor.
I've personally had a couple of times when my 16 GB RAM and 8 CPU laptop was running like 95 degrees hot because of the 3-5 simultaneous /workflows and a bunch of subagents completely annihilating my processor.
So that has led me to write a skill /track-load, which basically just launches a monitor that ticks your model with the current load data every X minutes in long-running flows, so the model can dynamically adapt.
It's meant to be used together with the type of session that acts as an orchestrator for a swarm of 10-20-100 parallel subagents and works for days, especially when you're running on resource-tight VMs/personal machines.
The skill for the monitor is in the comments, feel free to grab it.

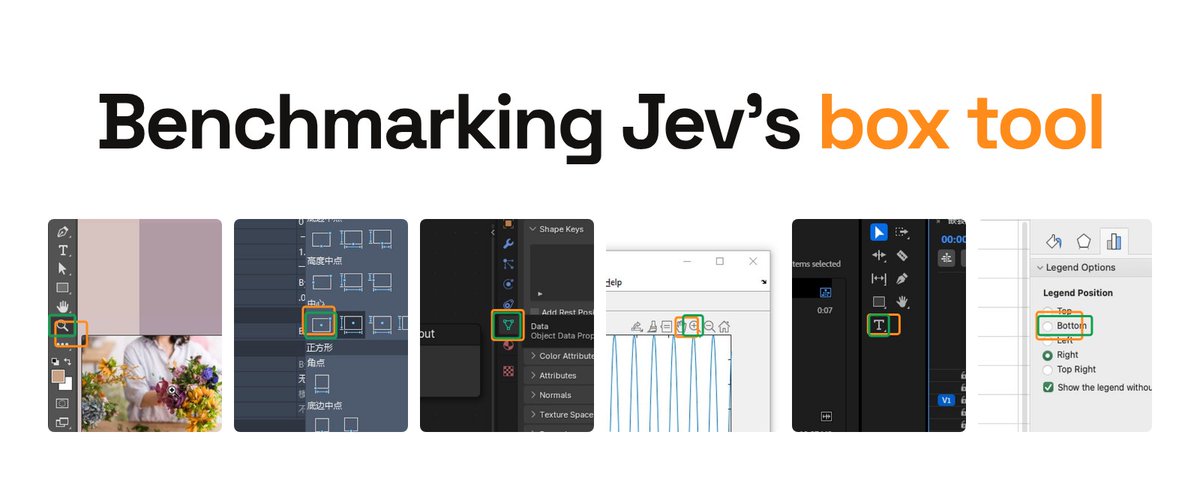
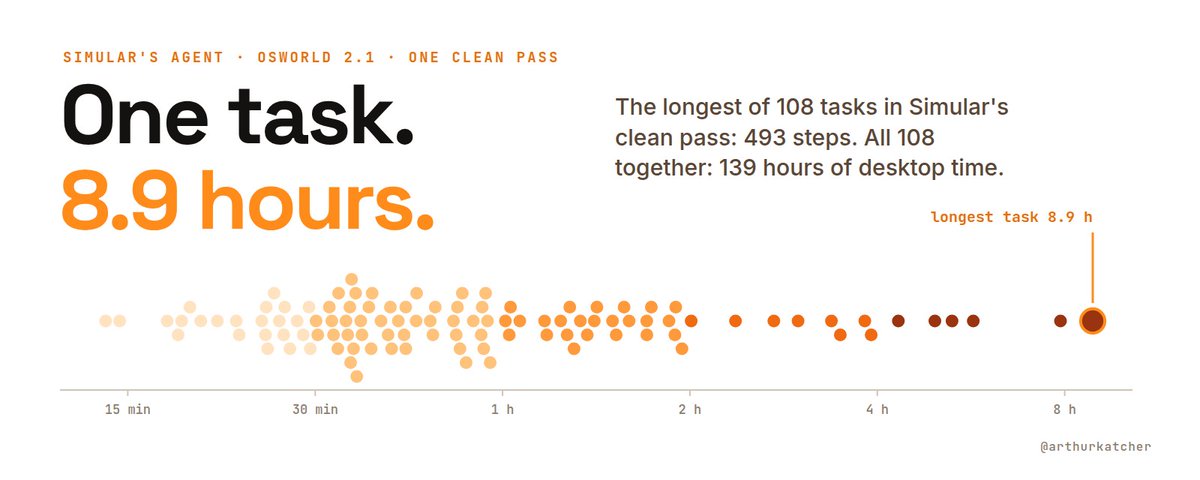
Thanks to @SimularAI for publishing every run of their Sai agent on OSWorld 2.1. The task times in this article come from their data. Honestly, more teams should share raw runs like this.

openai > anthropic
prove me wrong
>> Claude: pauses their startup program.
>> People get rejected after being initially accepted.
>> OpenAI in the meanwhile: gives us $2.5k credits.
DM me for the steps.

>> Claude: pauses their startup program.
>> People get rejected after being initially accepted.
>> OpenAI in the meanwhile: gives us $2.5k credits.
DM me for the steps.
Haiku 5.5 scores 72.4% on OSWorld 2.1 - offline subset.
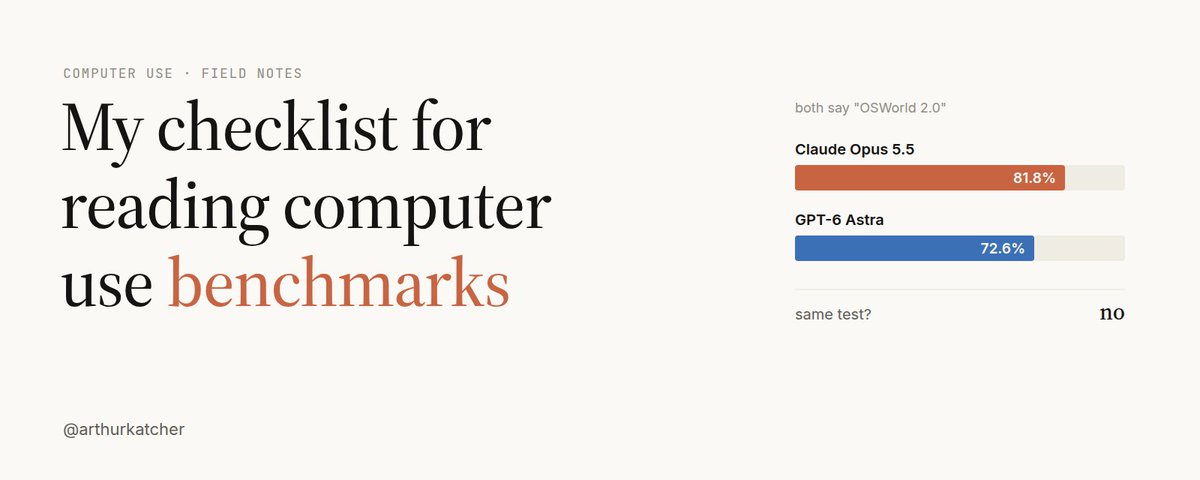
I’ve discussed exactly what that means and how to read it in my yesterday’s article on computer use benchmarks:

Wrote an article on computer use benchmarks yesterday. Two habits from it.
First, check the test version before comparing benchmark scores.
Opus 5.5 gets 81.8% on OSWorld 2.1, GPT-6 Astra 72.6% on 2.0. Looks like a 9 point win. But the same model, Opus 5, scores 68.3% on 2.0 and 77.7% on 2.1. The version alone moves it 9 points.
Second, check if it's the average run or the best one.
Anthropic's 81.8% is the average of 5 runs. Gemini 4 Argon's 69.2% is the best of 3. Run a model 3 times and keep the top score, and you report a number it won't hit on a normal try.
Same thing this week with Grok 4.7 on VulcanBench. Grok 4.7 was run on it more than once, and each run got its own spot on the leaderboard. The top three spots are all Grok 4.7, and the 93.15 everyone shares is the best of them.
Labs should report the same version and the average run. Until they do, read the fine print.

After installing @t3dotcodes I discovered that I had 3 resets in Codex and 1 in Claude Code I never knew about.
That's just awesome, stop using the terminal guys.

I caught OpenAI changing the benchmark score of its best model after launch.
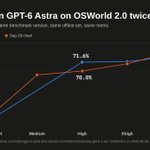
GPT-6 Astra on OSWorld 2.0:
Sep 3 → 72.6%
Sep 29 → 73.5%. Same test, same settings.
At high effort the same model went down instead, 71.6% to 70.0%.
This is the score behind OpenAI calling Astra "the world's best computer use model". They told nobody, and both charts are still live on the website.
So which run do you quote, the one that looks best?


Grok 4.6 high remains my default in Grok Build.
Find it performing better than 4.7 and writing in a cleaner manner.
Can't wait for Grok 5. The @spacexai team did an excellent job building out the best customer-facing interface, both in Grok Build and Grok Bot.
If rn I use Grok in around 5-7% of my flows, once the interface meets the right models, that number for me will grow significantly.
I personally identify that threshold as making Grok 5 at least as good as Opus 4.6--something truly usable as a daily driver for advanced tasks.
Figma is solved.
You can just ask your agent to create SVGs and import them.
So the fact they treat their MCPs like that is ridiculous.
Figma’s stock is about to crash in the coming years even harder, they have completely missed with the AI wave adaptation.


The best thing about Opus 5.5 / Sol 6.1 is that our Chinese fellows will open-source their analogues in about 3-6 months, so we’ll have personal private AGI before the end of 2027.