

The Benchmark for Recursive AI Improvement - Measuring the rate of self-improvement of AI agents
Canada
Joined June 2026
- Tweets66
- Following22
- Followers10
- Likes3



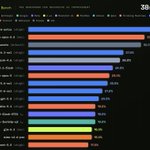
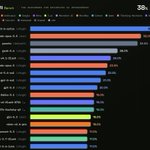


Kimi 3.1 Pro only hits 20% on ARI Bench, the benchmark for recursive AI improvement.
It's a shame, I really like Kimi 3.1. Wish it did better in ML tasks!

Minimax 3.1-Flash is decent! It scores 22% on ARI Bench, the benchmark for recursive AI improvement.
It provides good value for the money however Deepseek 4.1 Flash still edges it out.

Gemini 4 Argon scores 29% on ARI Bench, the benchmark for recursive AI improvement.
A strong showing but still not as good as Astra or Opus.
They said Google achieved RSI internally... with this benchmark, I doubt it. There's no way.

Muse Wonder scores 23% on ARI Bench, the benchmark for recursive AI improvement.
It's approaching frontier however there's still quite a gap between it and the top tier models. (I suppose that was to be expected when the first benchmark you list in your report is Harvey LAB)

Claude Haiku 5.5 scores a measily 6% on ARI Bench, the benchmark for recursive AI improvement.
Either they are purposely sandbagging AI / ML development (they said they were for larger models) or this model is benchmaxed for certain tasks. (I think it's the sandbagged ML)

GPT 6.1 Sol xhigh scores 27% on ARI Bench, the benchmark for recursive AI improvement.
This is what GPT-6 sol should have been all along. It offers slightly better value but ultimately trails Opus 5.5 in performance.

Sonnet 5.5 xhigh only scores 17% on ARI Bench. No where close to Opus 5.5 (at 33% on max).
I guess it might be decent for some smaller tasks however it appears to be missing that special oomph for the more complex ones.

GPT 6-Sol xhigh scores 21% on ARI Bench.
I was expecting MUCH better as GPT-6 Astra (38%) is the leader and Opus 5.5 just scores 33%.
What happened with GPT-6 sol :(

Opus 5.5 xhigh scores 25% on ARI Bench, the benchmark for recursive AI improvement.
Only a 2% improvement over previous iterations... this is a bit disappointing. Either they purposely hindered RSI or the model is optimized for benchmarks.
We're investigating.

Grok 4.7 scores 16.3% on ARI Bench. What a regression!
(We ran it 3 times! Grok 4.6 scored significantly higher. It appears as if Grok 4.7 was rushed and fails.)

Perhaps I made it seem as if Mimo V 2.6 was the best before... it's not.
It "only" scores 18% while the frontier is at 38%, however it's low cost makes up for it.

New "Value King" Mimo 2.6-Pro score 18% in ARI Bench.
This makes it the best model for the price at the moment, outperforming both GLM 5.3 flash and GPT 5.6 Luna.
If you need something smart to process a lot of data... this is it.

Union Alpha scores 32% on ARI Bench, the benchmark for recursive AI improvement.
This is the second highest score ever, only trailing GPT-6-Astra. Whoever it is... they have quite a model on their hands.

Deepseek V4.1 Flash's performance has been inconsistent (perhaps due to providers), however we believe the real performance number is 24% which is quite decent.

RSI is coming faster than expected and we don't have a plan for rogue models.
The best place right now scores 3 out of 5
aribench.com/containment-gap…


Muse Spark 1.3 scores 13% on ARI Bench, the benchmark for recursive AI improvement.
Quite a difference compared to what we're seeing from other benchmarks like the Artificial Intelligence Index 👀

Seems like the Artificial Intelligence Index needs to update it's methodology. They are still using old saturated benchmarks which lead to issues like this.
Can't trust it until they update it.
For example, imagine we were still using ARC-AGI 1 instead of ARC-AGI 3...

Holy!
I just made the same post as you 1 hour ago about the status of benchmaxxing... and I noticed the same exact thing.
xitter.cf/ari_bench/status/20952…

We need to talk about benchmaxing.
Gemini 3.8 Flash and Muse Spark 1.3 both dropped today. Both look great on benchmarks.
Muse Spark 1.3 is now tied with Fable 5 on the Intelligence Index. Gemini 3.8 Flash sits one point behind Kimi K3.
I want to be excited. I am not.
Every release this month has the same shape. Score jumps. Real world experience does not.
It is discouraging. I trust the benchmarks less every week, and I trust the labs gaming them even less.

