

Every moment think steadily and do what thou hast in hand with perfect and simple dignity, and feeling of affection
Joined July 2017
- Tweets1.1K
- Following931
- Followers791
- Likes4.7K






abu retweeted
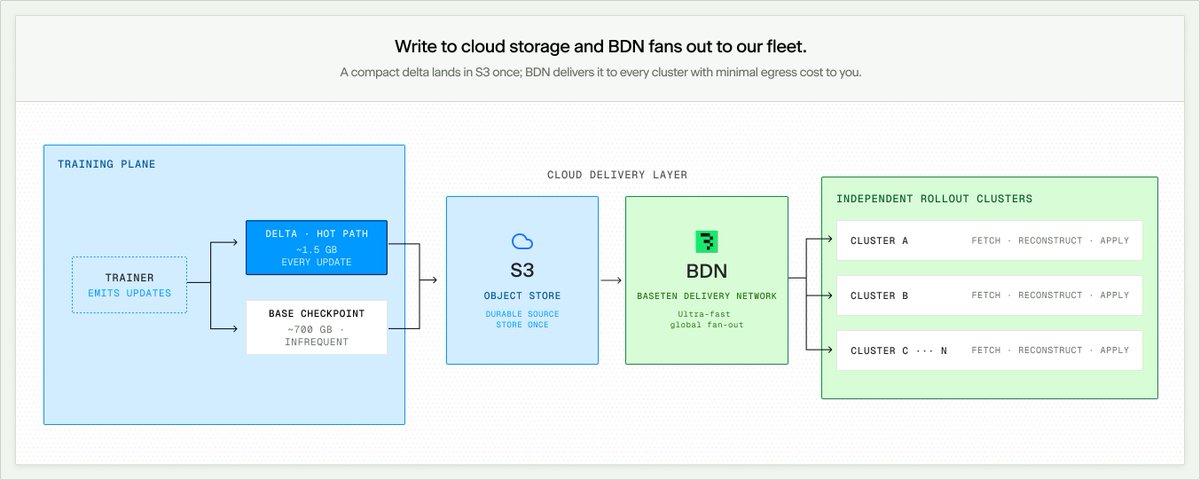
Very grateful for @part_harry_'s "can we just inspect the compressed bytes directly" right when I thought we had hit the limit.

abu retweeted

It has been easy to back the open source narrative recently with so much exciting progress, but the cyclical swings in energy we have seen seem inevitable. Inspired by the great scientists (including LeBron) pictured in video, @baselabs is a very direct effort to pursue a long-term research agenda that aims to support the WHOLE ecosystem (that we see being a mix between closed and open source models) for the long run. It is backed by @baseten ripping (which has a little more $$ than academia), but has a clear mandate to publish without exception and encourage skepticism. Our manifesto mentions 'Science done behind closed doors is worse science. It cuts off the one mechanism that has ever made knowledge reliable: correction from the outside'. Here's to democratising intelligence!

Today we're announcing Base Labs, a dedicated research organization focused on advancing open-source AI.
We believe in a healthy, open frontier model ecosystem. To enable this, we are working on:
- Blue-sky research on continual learning, the science of RL, and how models learn across their full lifecycle, with every experiment and recipe shared openly.
- The BaseHub Data Foundry: the highest-quality open RL environments, training data, and real-world benchmarks, built for anyone to train and benchmark on.
- Post-post training: taking open-source models and making them better, safer, and more aligned through continual post-training, built on our research, and deployed with our frontier safety stack so organizations can use open-source models with confidence.
- Making models cheaper and more performant through our model performance research.
This is a mission-driven research effort, not a commercial product. We believe the health of the open-source AI ecosystem matters and that the best way to advance it is to do science in the open.
We’re hiring engineers, researchers, and research fellows to advance this mission.
labs.baseten.co/
abu retweeted

GLM 5.3 Flash post-training is supported in Baseten Loops on day 0. And there's good reason for it. DM @oneill_c or I.
abu retweeted

I remember asking assistant coach Mo Cheeks, what’s harder to do? Workout after practice or before?? I only asked cuz by time I would get to the gym, Russ was already done in the morning and I usually got mine in after practice. Mo like, “coming in before practice is probably harder”…since then, it’s been my routine….a lot of people looked at the emotions on the court and thought Russ was loud, nah to me, he was quiet and methodical. He lead by example and once the lights were bright, he let everything out and experienced pure freedom. It was inspiring as his teammate and everywhere I went, I seen it inspire people from all walks of life, crazy thing is, he didn’t say much, he just showed up. For 18 years. This basketball life is sacred to us as professionals, what we put into that court means everything. Some of us wish we could go back and do things with a little more intent and some can just wipe their hands and be satisfied with the time spent. Who u gonna be? We know what zero was on…keep inspiring in the next phase of life champ. I don’t care what happens, can’t erase what it was…The first YNs, finals run in our early 20s, all star games, seeing each other get injured and bounce back, the bus rides, plane rides, card games, jokes and arguments, the whole thing, memorable!! …to the whole Westbrook family, Nina, the kids, mama Westbrook, big Russ, Ray, Donnell, everybody from luezinger high and ucla and many more that I’m forgettin, much love and Congratulations on a iconic career.


abu retweeted

I wonder how many firms are still too many months behind the silicon valley discourse to realise that one of anthropic's current goals is to acquire as much latent information not on the internet as possible, with the aim of capturing the revenue of the businesses that currently own that information
pe firms are now doing ai rollups with the explicit intention of selling data to big labs. Anthropic can buy a business for its data, add some marginal unit of intelligence to the model, and use the extra revenue from that intelligence to buy more businesses
I wonder whether there is a tipping point where this becomes recursive ie the marginal value of the next business' private data to anthropic exceeds the expected future revenue of the business itself

Claude Tag is a Trojan horse. Not because Anthropic is doing anything evil. Because the incentives are obvious.
Day one, this looks like a great feature: tag Claude in Slack, let it follow the thread, remember context, connect to tools, break down tasks, chase work, and act like a teammate.
But that is exactly the problem. The moment your AI vendor becomes a shared coworker, it stops being just a model provider. It starts becoming the place where work is interpreted, remembered, routed, and eventually executed.
That is not model lock-in. That is context lock-in. You are now renting your company back from them.
Models can be swapped. Agents can be copied. But the memory of how your company actually works is much harder, maybe impossible, to move: the Slack scar tissue, the exception paths, the customer promises, the unfinished threads, the weird workflows, the implicit owners, the “we tried that in Q2 and it failed” knowledge.
Once that lives inside one vendor’s agent layer, you are not renting intelligence anymore. You are renting your company’s operating memory.
And the pricing model makes it even more dangerous. A human coworker has a salary. Claude has unbounded tokenized activity. The more work moves through it, the more the vendor captures not just IT spend, but labor spend.
This is the enterprise bargain people will regret: Convenience now, and rapid decent into dependency.
The right architecture is simple: rent the best intelligence from whoever is best this month. OpenAI, Anthropic, Gemini, open source, whatever. But own the context layer.
Your company memory should be inspectable, permissioned, portable, and model-neutral. It should not be buried inside the same vendor that sells you the intelligence and the workflow surface.
Claude Tag is useful. That is why it is dangerous. Rent the intelligence, but own the context. Or, regret later.
Today, we released the fastest API for GLM 5.2, the best open weight model: 280 TPS and <0.8 TTFT.
This performance is the culmination of a number of techniques model performance has been building: PD disaggregation, multi-token prediction heads for spec dec, KV cache aware routing, and much more.
Check out all the optimizations here: baseten.co/blog/how-we-built…

and we’re hiring! Come join the team that powers the fastest APIs available:
jobs.ashbyhq.com/baseten/2fd…




abu retweeted
I hate when I hear language model researchers complaining that they can't do any interesting research anymore because they don't have enough compute. Literally stfu. This attitude wrongly paints the world as infinitely less complex and fractal than it really is. Beautiful ideas do exist at scales <10B parameters. You can't pretrain the world's best model, who cares? Go and explore the unbounded space of ideas in the range of compute you have. The world is a microcosm and you can zoom in infinitely at any part of the scale to find interesting and useful things
abu retweeted

a soft morning, engineered with shaders in san francisco time
farayan.me/sanfrancisco


