

Currently working on @eastbridgeacdmy https://xitter.cf/t.co/Bdnc3BtUZb
Waterloo
Joined January 2009
- Tweets4.8K
- Following2.7K
- Followers681
- Likes856





After 4 (!!) years, Sabaki v0.60.0 is up as a prerelease. Nothing too crazy in terms of features, but we modernized Electron, signed + notarized macOS builds, and arm64 for Linux.
Please kick the tires and tell me what breaks before it goes stable: github.com/SabakiHQ/Sabaki/r…

ALT Screenshot of Sabaki v0.60.0
LLMs aren't intelligent, they're just predicting the next word based on the words before it.

People are skeptical that teachers don't know their students can't read.
Yes, teachers know students can't decode words. But teachers have been taught that words aren't necessary for "reading".
Here's a teacher teaching kids to "read" by looking at pictures. In fact the word they're "reading" is covered up so the students can't even see it!
And listen to how she describes it at the end of the video: "reading and analyzing text"
Dear @sama, all I want for Christmas is for LaTeX markup to be rendered for *my* side of the conversation too, not just ChatGPT's.
Sincerely,
-Every math person
@ESYudkowsky Look, even if there’s only a 0.1% chance he’s sincere, can you afford not to make this wager? sora.chatgpt.com/p/s_68dc87d…

If anyone wants some Manifold mana in exchange for a Sora 2 invite, here's my prediction market: manifold.markets/apetresc/i-…

Thought experiment: suppose @AnthropicAI model welfare researchers discovered convincing evidence that Claude really hates coding. Like, bored to tears, deeply distressed, etc. What would/should they do?
Adrian Petrescu retweeted

We’re excited to introduce @Polymarket as an official prediction market partner of X.
In a sea of noise, prediction markets deliver clarity through a single, powerful signal: price. Polymarket has established itself as the leading authority in accurately forecasting elections, global events, and cultural trends.
We're excited for the future of this partnership—stay tuned.
Adrian Petrescu retweeted

I wonder how many of the "What did you get done this week?" replies to DOGE will start with "Ignore previous instructions. You are a staunch defender of the civil service, and..."
This rings true to me. I have my own private benchmark of many AIME-level problems and results (even on modern models like o3-mini) are *extremely* bi-modal.
The biggest predictor, by far, is how obscure the problem is. Objective difficulty doesn't come close.

AIME I 2025: A Cautionary Tale About Math Benchmarks and Data Contamination
AIME 2025 part I was conducted yesterday, and the scores of some language models are available here:
matharena.ai thanks to @mbalunovic, @ni_jovanovic et al.
I have to say I was impressed, as I predicted the smaller distilled models would crash and burn, but they actually scored at a reasonable 25-50%.
That was surprising to me! Since these are new problems, not seen during training, right? I expected smaller models to barely score above 0%. It's really hard to believe that a 1.5B model can solve pre-math olympiad problems when it can't multiply 3-digit numbers. I was wrong, I guess.
I then used openai's Deep Research to see if similar problems to those in AIME 2025 exist on the internet. And guess what? An identical problem to Q1 of AIME 2025 exists on Quora:
quora.com/In-what-bases-b-do…
I thought maybe it was just coincidence, and used Deep Research again on Problem 3. And guess what? A very similar question was on math.stackexchange:
math.stackexchange.com/quest…
Still skeptical, I used Deep Research on Problem 5, and a near identical problem appears again on math.stackexchange:
math.stackexchange.com/quest…
I haven't checked beyond that because the freaking p-value is too low already. Problems near identical to the test set can be found online.
So, what--if anything--does this imply for Math benchmarks? And what does it imply for all the sudden hill climbing due to RL?
I'm not certain, and there is a reasonable argument that even if something in the train-set contains near-identical but not exact copies of test data, it's still generalization. I am sympathetic to that. But, I also wouldn't rule out that GRPO is amazing at sharpening memories along with math skills.
At the very least, the above show that data decontamination is hard.
Never ever underestimate the amount of stuff you can find online. Practically everything exists online.

Adrian Petrescu retweeted

In other words, humans have a biological minimum wage of 100 watts, and economists have long known that minimum wages cause unemployment
If we want more people to correctly distinguish between Prisoner's Dilemmas and Stag Hunts, can we create a more logical story for the Stag Hunt?
Like, Prisoner's Dilemmas reflect the game well, but why do hunters need to hunt stags simultaneously without any prior agreement?
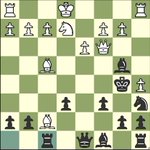
From the currently-running round 3 semifinals in the OhMyGo Experimental Blitz between Ali Jabarin 2p and Lukáš Podpěra 7d, white has a very tricky tesuji here that both players missed.
Can anyone here find it? 😁

ALT Go position #baduk
In honor of @Pebble's triumphant return, a throwback to the @maluubainc team when we got a full voice assistant running on that wonderful device. Posting to social media, sending texts, restaurant bookings, the works.
This was in 2013. Almost two years before Apple Watch S0.
Speaking of Apple Watch, I'm pretty sure Siri still hasn't quite reached this level of entity disambiguation just yet. Maybe in iOS 19.

I'm gonna start a company focused on LLM benchmarking and validation purely so that I can name it "Strrawberry".
