
compute! stanford cs
SF
Joined October 2026
- Tweets20
- Following39
- Followers140
- Likes407




Pinned Tweet
if you have a .edu, .gov or .mil email you can now get a full 8x B300 node for $4/GPU-hour. nebius charges $9.50 on demand and a lot of clouds are sold out
AMD MI355X nodes are $3 and the wait right now is under a minute
you just ask marshall, their AI agent, and it finds you a node
this is a major public good for researchers who've been priced out of frontier compute
thank you @AnjneyMidha


hundreds of MI355x and B300 nodes
now live on nationalcompute.com
subsidized for all .edu and .govs
it’s time to scale the frontier ecosystem
for the public benefit

anthropic and openai have completely opposite compute strategies
anthropic buys from everyone. $111b with google for TPUs, $110b with amazon for trainium, $31b with microsoft, and ~$135b with neoclouds like spacex, nscale, lambda, and volta
openai bet on doing compute itself. $300b with oracle for stargate, $250b with microsoft, and its own stargate campuses in texas, ohio, and georgia
anthropic signed roughly 3x more neocloud capacity than openai, and around two thirds of its commitments are on non-nvidia chips


anthropic is locked into $450 billion of compute. it has to pay whether it uses it or not
anthropic's revenue is about $70 billion a year. roughly (though contracts change price every year), it's $45 billion a year for a decade. that's most of what they make a year today
the contracts they've signed is a long-term bet that demand for claude keeps growing
in $600B in compute contracts, $450B can't be canceled. the only deal that can be left is @SpaceX (up to $84.5B, with 90 days' notice)
if things don't work out, anthropic's only way out of these deals is renting the gpus to someone else

microsoft just pulled out of nscale’s uk data center deal. which neocloud is next?
here’s every major one by contracts, revenue, debt, borrowing rate, and how much of their capacity is actually live


Microsoft has pulled out of a UK data center deal with British neocloud Nscale at a critical time for the startup’s initial public offering hopes, the Telegraph reported. bloomberg.com/news/articles/…

most of what you pay for a guaranteed h100 is the guarantee
-> hyperscaler on demand ~$7.15/hr
-> neocloud average ~$2.83/hr
-> interruptible on vast from $0.53/hr
an idle gpu costs its owner like $0.10/hr in power so basically any price beats leaving it unused. electricity markets already work this way, fixed rates for stuff that can’t wait, real time prices for everything else, and big users paid to shut off when the grid is tight. @sfcompute letting you resell reserved compute you’re not using is the same logic
inference is the workload that can buy compute like this since batch jobs, evals, and background agents can wait. you already see it in tokens, batch is half off at openai and anthropic and on auction markets like liquid inference from @Architect_Fi, open models clear way below the model maker’s price


a v100 from 2017 still rents for about twice its resale value every year
-> a used 32gb card sells for ~$600-700
-> it rents for about $0.15/hr on vast, ~$1,300 for a full year
worth remembering when people say gpus are worthless after 3 years. that's a big part of the neocloud/compute bear case right now

The market is suddenly flooded with V100 32GB cards—plenty of stock, no need to scramble, with both SXM2 and PCIe versions available. The bad news? Prices are up at least $200. The good news? $2,000 can still build you a solid personal local LLM rig, and performance is genuinely decent—thanks to Strata’s high-performance algorithms.


open model tokens are getting close to free on liquid inference
-> deepseek v4.1 flash is $0.001 in / $0.008 out per million tokens. deepseek charges $0.15 / $0.60
-> kimi k3 is $0.02 / $0.70 vs $3 / $15 from moonshot
-> glm 5.3 is $0.015 / $0.21 vs $1.40 / $4.40 from zhipu
once enough sellers compete on the same model, tokens behave like any other commodity. it's much easier to list here than on openrouter, so people with idle gpus just jump in and undercut to fill them
the market design is doing the work. live quotes and an auction on every request let spare capacity clear near cost, which a fixed rate card can't do
video just launched with one seller per model at fal's list price. looking forward to watching that market too


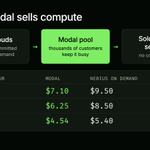
modal is a good example of where compute markets are heading. they sell gpus by the second with no commitment for less than the big neoclouds charge on demand
-> b200 is $6.25/hr on modal vs $8.50 at nebius
-> b300 is $7.10 vs $9.50
-> h200 is $4.54 vs $5.40
they rent from 20+ clouds and commit to capacity ahead of demand. pooling demand across all their customers keeps utilization high, which is what lets them price lower
the more compute trades like a commodity, the more value goes to whoever aggregates supply and matches it to demand


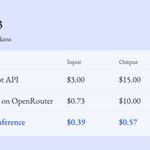
you can get kimi k3 on liquid inference for $0.39 per million input tokens and $0.57 output right now
moonshot's own api is $3 and $15. the cheapest provider on openrouter is $0.73 and $10
it's still cheaper after their cache discounts too
the difference is market design. on openrouter each provider lists a fixed price and openrouter spreads traffic across them. on liquid every request is an auction, providers can reprice any minute, and the cheapest offer that meets your speed and quality rules wins
markets will exist for compute and tokens just like for other commodities

the token index drop is mostly an explosion in cheap model usage, not less frontier spend
on openrouter models under $0.25 per million tokens are now 3/4 of all tokens, and that shift alone cut the average price per token ~31% over the last month
frontier usage keeps growing. tokens on the top closed models grew 55% over the last month and they're still about half of all spend
and there will always be demand for frontier tokens. for r&d and anything adversarial like negotiation or trading, you want the best model
meanwhile b200 rental prices are up 67% since mid june

In a normal functioning ecosystem, when the price of tokens drops below the cost of production, the quantity of tokens declines to normalize with pricing. In this case, nothing in AI has any unit economics and you don’t see normalization because everyone is still going full-speed ahead with external funding. (Sort of like shale oil in 2016-2019). Meanwhile, compute prices are based on LT contracts that were signed at above market prices, and are now capital destructive. They’ll eventually catch down to token prices in free-fall.
What we’re seeing here is spot price negatively diverging from term pricing. Usually, when this happens in a cyclical industry, it’s INCREDIBLY BEARISH. Especially when there are take-or-pay contracts that make it difficult to ration supply at prices below cost. What we’re witnessing is a world where losses will accelerate, just as more supply comes online….
google knew the risk of cutting noam shazeer's compute (the stock fell by $100 billion the day his departure was announced) but did it anyway because they didn't have enough
dario personally calls ppl to beg for compute
imo ppl are still underestimating the importance and scarcity of compute
it's even harder for startups who can't fund long multiyear contracts or put 30% down
compute is the oxygen of ai

WSJ is reporting that Anthropic CEO Dario Amodei personally called Meta's Alexandr Wang seeking more compute. Meta considered providing chips, then declined.
Inside GOOGLE, Demis Hassabis has expressed frustration about Google not allocating enough compute to long-term research. Sergey Brin sometimes overrides the company's formal compute allocation process, redirecting resources toward projects he personally considers important.
Google also cut compute allocated to Noam Shazeer's team in favor of another project. Shortly afterward, he left for OpenAI.

agree, open tokens burn about as much compute as closed tokens. inference providers (like @baseten and @FireworksAI_HQ) have positive margins on top of their compute costs, even with dozens of companies competing to serve the same models on openrouter
there’s a question of why. in a world where AI can spin up an efficient inference stack for anyone, a large software edge shouldn’t last long
a lot of it is that inference providers signed long-term compute contracts making them effectively long compute. those contracts have gotten more valuable since they signed. a 1-year H100 contract went from ~$1.70 last october to ~$2.75 today, and B200 rentals are up ~85% since june
so part of that margin is effectively a compute trade rather than purely a software moat


a GPU cluster can pass every benchmark and still go down for days
IREN’s response was NVIDIA exemplar status, which shows its cluster hits NVIDIA’s reference performance on their benchmark recipes. whether a site stays up month after month is a separate question
here’s what I’d ask before signing a GPU contract
- which site am I on, and is power, cooling and network N+1 or N+0
- does the provider run that datacenter or rent colo space and rely on the landlord’s techs
- what was uptime at that site over the last 90 days, and how does the SLA define downtime
- how fast do health checks catch a bad GPU and pull it out of your jobs, and are there hot spares
- on NVL72, what happens when a tray dies. it takes 4 GPUs out of the NVLink domain, so ask if they run the rack degraded or swap it and how fast
- which XIDs they act on. the ones that mean bad hardware are 79 (GPU fell off the bus), 48, 94 and 95 (memory errors) and NVLink errors (74 on hopper, 144 to 150 on blackwell). 13, 31 and 43 are usually your own code
- was the cluster burned in with the GPUs and network stressed at the same time
- link flaps and error counters on the infiniband or RoCE network
the providers with good answers usually love being asked

IREN continues to come up in our conversations with neocloud customers, and usually for the wrong reasons. In Prince George and Mackenzie in Northern BC, Canada, we’ve heard the stories: multi-day power outages, network upgrades, storage failures, air quality controls leading to link flaps, XIDs everywhere. The #1 worst site in the industry, according to users.
And we are some of their users, as we’ve gotten to test IREN GPUs from multiple providers that resell their capacity. A lot of our users we are hearing from who aren’t having a good time aren’t renting from IREN resellers, but from IREN themselves. (1/3)🧵

some inference providers on openrouter are playing a funny game
openrouter's routing seems to reward whoever lists the cheapest input price so a few providers price input near zero and make it back on output
on deepseek v4 flash today, relace has the lowest input price ($0.01 per million tokens) and gets 33% of all traffic. but it charges $1.28 per million output tokens while streamlake charges $0.08
even though 94% of tokens on this model are input, relace still ends up almost 4x more expensive than streamlake. for reasoning-heavy work it's about 15x
in theory openrouter should be a really good marketplace where competition drives prices down fast. but that only works if the incentives reward the cheapest real price, not gaming the listings. it's a really important market design problem

the big AI clouds are building in really different ways right now
Google is unique in that it owns basically every layer. it designs its own TPU chips, builds and runs its own data center campuses, and owns the application layer with Gemini, Search, YouTube, etc. its cloud business runs a very healthy operating margin.
SpaceXAI is similarly very integrated. they've put their own gas turbines and Tesla Megapacks next to their data centers and run Grok on a lot of their compute, though they still buy every GPU from Nvidia.
Crusoe develops the sites and the power, although for its biggest sites like Abilene, Blue Owl owns most of the campus. Nebius owns its Finland site, designs its own servers, and fun fact, pipes the server heat into the local town!
CoreWeave takes a different approach and leases every data center, only owning the GPUs and software. Fireworks goes further and mostly rents GPUs from a bunch of providers to sell inference, though we're seeing more inference providers start buying their own compute to expand margins and bring on more capacity
the more of the stack you own, the more capital it takes upfront, but also the better you can work around bottlenecks, which are getting more pervasive as the compute shortage worsens
