

Creator of Sparrow: open-source AI doc extraction 🚀 | Local LLM consultant | Building PyADF: Oracle ADF → Python | @katana_ml | https://xitter.cf/t.co/V0h9FMJzKb
Katana ML 👉
Joined March 2010
- Tweets5.5K
- Following157
- Followers6.7K
- Likes13.5K




Pinned Tweet
We launched Katana ML katanaml.io in 2018 and now it is time to update the website, to explain where we are now and what we do with #MachineLearning, #MLOps, and #opensource
🚀🚀🚀

We have a new website - katanaml.io
It explains what we do with ML in a simple and straightforward way. It is featuring our open source product Skipper, we are using it to run #MLOps.
#MachineLearning #MLOps

Many organizations won't send patient reports to a cloud API, yet the results still get retyped by hand.
Sparrow turns an MRI report into structured data: disc levels, measurements, the impression. Runs on infrastructure you control.
youtube.com/watch?v=E89dQu9o…

Want this on your own documents? We set up Sparrow on your infrastructure and run a pilot: katanaml.io/consulting.html
Andrej Baranovskij retweeted

Not sure who needs to hear this but....
An LLM doesn't "understand" anything. It is a statistical model that spews out tokens based on probabilities calculated through massive matrix operations and context, not an understanding of the subject matter.
Andrej Baranovskij retweeted

So proud of the MLX team!
Muse Spark Open, on your desk: 816B params at 36+ tokens/sec on 4 Mac Studio computers.
We've been hard at work on better M5 GPU Neural Accelerator support, a smoother Thunderbolt experience (including multi-cable meshes), and kernel optimizations for MoE architectures.
Oh — and MLX LM (mlx_lm.generate, mlx_lm.server) now supports the vision modality for Muse Spark Open!
More on using MLX for distributed inference of frontier-scale models on Mac Studio:
machinelearning.apple.com/re…


Andrej Baranovskij retweeted

Muse Spark Open -- weights releasing today -- runs great on new Mac Studios thanks to work with @johnternus and Apple.

Andrej Baranovskij retweeted

Le Chonk cooked on visual grounding.
Pinpoints exactly where things are in an image.
42% on Dense 200, ahead of even frontier closed models..
Andrej Baranovskij retweeted

We serve those as well! Sorry if using nuclear energy is a real blocker

Berlin-based search engine Ecosia, used by government services, is dropping its French AI partner, Mistral, its CEO told POLITICO.
The company will now bet on open-source models, including those from China.
vist.ly/5mh5y

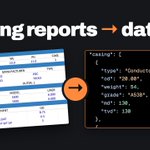
Drilling reports arrive as PDFs. Someone retypes them by hand.
Sparrow turns a daily drilling report into structured data: header, casing, directional survey, full time log. Open source, runs on your own hardware.
Watch it work: youtube.com/watch?v=YgOb2V0t…

Want this on your own documents? We set up Sparrow on your infrastructure and run a pilot: katanaml.io/consulting.html

Andrej Baranovskij retweeted
Meet Mistral Large 4, aka Le Chonk.
• 1T parameters, natively multimodal. 49B active.
It is the best open weights model from US or Europe on aggregated benchmarks.
• State-of-the-art on critical workloads, including cyber defense, manufacturing and finance and it surpasses closed frontier models on visual grounding.
• Forged in Europe end-to-end and is deployable from Europe via our own Mistral Cloud infrastructure.
• Available to all via API today. Working with cybersecurity partners privately.
Open weights release end of October.
🤖 Made with AI
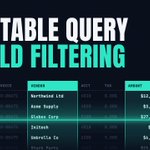
🔥 New Sparrow feature: table query with field filtering
Extract only the columns you need from a table. Sparrow uses dots.ocr to detect the table structure, then maps and type checks just the fields your schema asks for.
Watch example:
youtube.com/watch?v=63ZlFkkY…
Code:
github.com/katanaml/sparrow
Try:
sparrow.katanaml.io

Andrej Baranovskij retweeted

Vibing a custom inference engine is easy 🤣
Step 1: Spend $2,000 on tokens
Step 2: Qwen3.8 goes 3% faster
Step 3: New model drops, engine is obsolete
Step 4: Repeat until bankrupt or acquired

Andrej Baranovskij retweeted
MLX-VLM is powering or is the reference for all the top 3 picks…

MLX Poll is showing interesting data!
Keep voting: poll.devocracy.it/mlxengines…
We need models optimized for 64GB machines.


Andrej Baranovskij retweeted

Which MLX engines do you actually use?
I can't test and eval them all 🤷🏻♂️
Community poll: pick up to 5 of 19 (oMLX, LM Studio, Nativ, MLX-Serve, …). Add your chip (M1 to M6) and RAM if you like, to see what each setup prefers.
No login, live results, open for 7 days: poll.devocracy.it/mlxengines
Please repost to spread the word and don't cheat out there! 🧐

Andrej Baranovskij retweeted
All these posts by AI labs about slowing down to improve security is nonsense and must stop. Do it and stop writing about this.
You (labs) are responsible for the product released, if they are not secure enough, you should slow down and don’t release.
If you make mistakes and cause damage during your tests, you are responsible, no one else.
You are the only one seeing the damage your products can do, we have no clues about this. So again, you are responsible, no one else.
To make it more direct: if Boeing or Airbus deliver some new airplanes without being sure of their security, they are responsible, no one else? 🤷🏻♂️
Plain and simple, no? So please slow down internally, do your own homework, ensure the security of your models and ensure a smooth and secure ride for us, the users.
Andrej Baranovskij retweeted
One of the great pluses of Apple MLX is that the team has access to hardware earlier than anyone else.
M5 Ultra tunings are already backed in for day-0 support! (yo'll have to build it from sources)

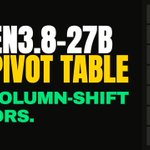
🔥 3 models, same insurance pivot table, same "*" query, no schema.
✅ Ministral 14B (Standard mode) - nailed it
❌ Gemma 4 31B (Advanced mode) - hallucinated, nulled real values, shifted columns
✅ Qwen3.8-27B (swapped into Advanced mode) - nailed it too
📺 Video: youtube.com/watch?v=j7b26D6b…
⭐ GitHub: github.com/katanaml/sparrow
🌐 Live: sparrow.katanaml.io

Andrej Baranovskij retweeted
Posts with an arrogant tone like this one does not help to solve anything, if there really is something to solve here. Compute is secondary, but still relevant IMO.
And moreover I don’t think that there is a single person in the world, that knows in detail how these Gen AI models really work overall, even less on specific hardware with obscure specifications.
Less arrogance and more collaboration help communities much more.

