
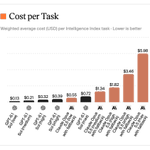




Wow, just make an expensive product and suddenly you deliver more value. By this logic a $1 subscription that can generate 1 token worth of $1 million is a clear winner.

Anthropic Subscriptions Offer 5x+ More Value Than OpenAI
Limit testing every AI subscription plan from Anthropic, OpenAI, Meta, SpaceXAI, MiniMax, Moonshot, Zdotai, Cursor, and Cognition
newsletter.semianalysis.com/…

People write bad code over 2 years, call it legacy.
People write same amount of bad code in a week, call it AI slop.
If you compress the timeline, you need to refactor, modernize or migrate after a week or a month, instead of several years.

Vimium in Codex App, this is Christmas!

Today, we’re launching support for Chrome extensions in the ChatGPT desktop app!
Bring the extensions you use every day to the in-app browser. You can now install, pin, and use your favorites, like 1Password, while getting things done with ChatGPT.
Enterprise admins can now centrally deploy and manage extensions across their workforce so the IAB meets security requirements.
Try it out and let us know what you think!
Alex Schüren retweeted

The "whiteboard defense:" I should be able to pull you aside at any moment and ask you to explain any customer-facing system you've shipped. You should be able to clearly explain how it works and defend the decisions you made. This is my benchmark for responsible AI usage.
I don't expect line-level familiarity with the code. I don't care if you remember the exact function name or implementation detail. You may not even know it. I don't care.
But if I ask "why did you do X instead of Y?", "what happens if this actor behaves maliciously?", "what data structure did you use here and why?", or "where does this fail?" you should be able to answer confidently.
For PoCs, demos, experiments, whatever: I don't care. Generate 100% of it and understand none of it. Speed over quality every time in those specific scenarios.
But if you're shipping customer-facing work, you can't be shipping things you don't understand at a high level.
Alex Schüren retweeted

Get more out of GPT-6 Astra by revisiting your skills, AGENTS.md, and task prompts.
Make skill triggers specific, load guidance when it's relevant, and define what done looks like.
developers.openai.com/blog/r…

Alex Schüren retweeted

Three months ago, we launched ChatGPT Sites – an easy way for anyone to build and host fully functional, interactive web apps. Since then, people have created over 5M sites.
We’ve been listening to your feedback and ICYMI, we’ve launched a few Sites updates:
🫂 Build together: Invite teammates to edit, save, and publish to your shared Site
🔐 Share privately: Invite specific people to a private Site without making it public
🚀 Launch faster: Go from prompt to deployment in half the time
👀 Explore your data: Ask ChatGPT to inspect your Site’s database. Editors can view it, too
🌐 Add your own custom domain
Alex Schüren retweeted

ChatGPT Images 2.5—faster, sharper, smarter, with better tools for creating whatever you can dream of.
- Faster image generation to keep your ideas flowing
- Improved fidelity for more natural, recognizable images
- Consistent details across multiple edits
- Comment-based edits to change only what you want
New click bait on x: hit my astra pro limit on one prompt on medium reasoning.
No context, no details, no explanation or examples, just useless shit posting.
This is how it should be, tell your story, using $20 plan on medium, but spawns sub agents with uncached input tokens. 5h limit goes down!
There might be issues and bugs, but please share the details so we can fix them.
xitter.cf/DennisonBertram/status…

Video evidence of how fast my Astra usage is going. @thsottiaux this is what? 10% per minute? @OpenAI
Another graph, different language, different number of tokens, the price goes up:
ellamind.com/blog/tokenizati…

Alex Schüren retweeted
We’re sharing a solution to the Navier-Stokes Millennium Prize Problem, one of the deepest problems at the frontier of mathematics.
The proof was produced by a group of agents, using an OpenAI next-generation model significantly more capable than GPT-6 Astra.
The problem concerns whether the description of smooth three-dimensional fluid motion modeled by the Navier-Stokes equations can break down. It has remained unresolved for roughly 90 years.


What happened in July 🤔 the answer is obvious


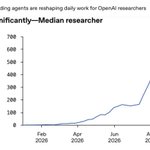
Today we're releasing data on models accelerating research at OpenAI.
Recursive self-improvement could be the most important contributor to AI capabilities over the next few years, but by default it will only be seen inside a few frontier AI labs. Being transparent is more urgent than ever, so we can inform the public discussion on whether and how to pace model development. I ask other AI companies to do the same.
openai.com/index/research-ac…

I always found the pelican example from @simonw really cool.
Here is GPT-6-Astra pelican svg and threejs:
The last part does not make sense.
Even AI labs are moving CPU usage from your machine/phone to cloud (their own or other provider) because it burns battery to run 42 agents and consumes your local resources.

Alex Schüren retweeted

Yesterday, my OpenAI collaborator and I gave a detailed talk on the Huggingface incident, our models creating "the message board", model misalignment, and more.
youtube.com/watch?v=87DyyMV0…
I hope it can answer a lot of the questions folks have, and we will release a full detailed postmortem at a later time!


