Joydeep (@alt227Joydeep) profile picture

Senior Staff Engineer at Samsung SSIR. Primary interests: machine learning & NLP. Author of books on fasttext and ML with Rust. AI to make peoples lives easier.

Joined January 2012
Photo by Joydeep (@alt227Joydeep)Photo by Joydeep (@alt227Joydeep)Photo by Joydeep (@alt227Joydeep)Photo by Joydeep (@alt227Joydeep)Photo by Joydeep (@alt227Joydeep)Photo by Joydeep (@alt227Joydeep)Photo by Joydeep (@alt227Joydeep)Photo by Joydeep (@alt227Joydeep)Photo by Joydeep (@alt227Joydeep)Photo by Joydeep (@alt227Joydeep)
One of the first steps in any NLP pipeline is tokenization. It is the process of splitting a given text into a sequence of units that are related to the vocabulary of the corpus. Thus we get a representation of a given text. ==thread==
1
1
15
GPUs are behind the rise of AI and the current change in the world order. But what's actually inside these GPUs? 🧵
1
12
The golden rule of GPU performance: Keep data as HIGH in the memory hierarchy as possible. Constantly reading/writing from HBM = slow cores, wasted compute. Data in registers or shared memory = blazing throughput. This is the whole game.
1
3
TL;DR of a Blackwell GPU: 160 SMs → each with 128 CUDA + 4 Tensor cores → Warps of 32 threads (SIMT) → Latency hiding via warp switching → Fast local memory → L2 → HBM Optimize for keeping data close to compute. Everything else follows. 🔥
10
With AI you move from debugging code to debugging your intent.
9
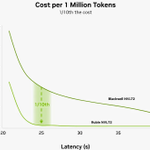
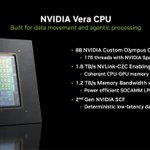
1/ NVIDIA just dropped the Vera Rubin technical report. I spent last couple of days going through it. Here's what it tells every AI/ML developer about where to invest their learning time 🧵
1
1
25
11/The takeaway: NVIDIA's hardware bets are a signal about what software will matter in the next 2-3 years. They don't build hardware hoping developers catch up. They build hardware for where they know developers are going. Read the report. It's a roadmap.
1
1
16