
深層学習に興味があります。
日本
Joined January 2019
- Tweets2.7K
- Following307
- Followers1.2K
- Likes63.4K





allowfirm retweeted

『基盤モデルのための強化学習』の著者見本が届きました!
LLM などの基盤モデルにおいて、強化学習がどのように用いられているかを体系的にまとめた書籍です。
強化学習は、昨今の AI の進歩の主要因の一つであり、かつ「報酬ハッキング」など安全性に関する議論とも関連があります。いま強化学習を勉強するのはタイミング的にかなり良いのではないかと思います。
この本が、国内の AI・強化学習の研究・開発レベルの底上げにつながると嬉しいです!
Amazon:amzn.asia/d/0bjnVH4N


allowfirm retweeted

窓反射に誤報しないのが何気に凄い

Make workplace monitoring more intelligent with Ultralytics YOLO26! 🔒
Detect people and faces in real time to support occupancy monitoring, access control, and security operations.
Discover more ➡️ ultralytics.com/blog/real-ti…
#Ultralytics #YOLO26 #Survillence
allowfirm retweeted

Make workplace monitoring more intelligent with Ultralytics YOLO26! 🔒
Detect people and faces in real time to support occupancy monitoring, access control, and security operations.
Discover more ➡️ ultralytics.com/blog/real-ti…
#Ultralytics #YOLO26 #Survillence
allowfirm retweeted

Kaggleで学んだBERTをfine-tuningする際のTipsが復活したようです!
①〜学習効率化編〜
ai-shift.co.jp/techblog/2138
②〜精度改善編〜
ai-shift.co.jp/techblog/2145
③〜過学習抑制編〜
ai-shift.co.jp/techblog/2170
④〜Adversarial Training編〜
ai-shift.co.jp/techblog/2985
⑤〜ラベルなしデータ活用編〜
ai-shift.co.jp/techblog/3161
⑥〜LLMでも使える学習効率化編〜
ai-shift.co.jp/techblog/3609


allowfirm retweeted

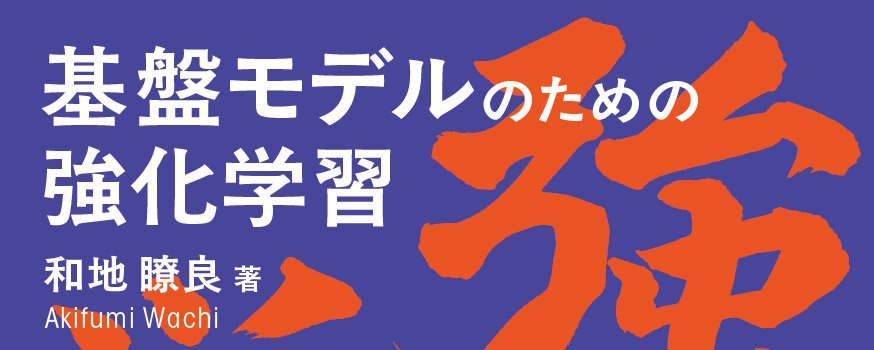
『基盤モデルのための強化学習 (KS情報科学専門書)』
和地 瞭良 (著)
久々に強化学習の本出る!!!
amzn.to/46C7VeC

allowfirm retweeted

本日15時から #ECCV2026 でEvent-LiDARの発表を行います!
イベントビジョンの考え方でLiDARを効率化する、Simple but Effectiveな研究です。ぜひお立ち寄りください!
🕒 15:00〜 CEST
📍 ExHall・Poster #12 Session 6

🚀 Can we make 3D perception more efficient by processing what changes across LiDAR scans?
We will present Event-LiDAR at #ECCV2026: converting conventional LiDAR scans into sparse 3D events.
Project: event-lidar-project.github.i…
Video: youtu.be/gPgxb6S1bfI
Details below. 🧵
allowfirm retweeted

Introducing Atlas:
The world's first multimodal world model that generates image and video frames with pixel-perfect camera control and reconstructs them in 3D.
Model the world, move the camera, and simulate space & time.


allowfirm retweeted
「LLMは最初の1ターン目以降、性能がガクッと落ちるよ」というICLR2026ベストペーパーの話を無限にしてる気がする。LLM活用の話として重要すぎるので……
blog.iclr.cc/2026/04/23/anno…

LLMs Get Lost In Multi-Turn Conversation
openreview.net/forum?id=VKGT…
LLMは2ターン目の会話からすでに性能が下がるらしい。(すでに100回以上引用されてる論文だけど)重要そうなのでメモ。


allowfirm retweeted

papers with codeのbrowse SOTA復活したのか!
paperswithcode.co/tasks
