
Machine Learning Researcher
Kissimmee, FL
Joined January 2008
- Tweets67
- Following1.5K
- Followers1.2K
- Likes90


Alex Alemi retweeted

A statement on the comments from Secretary of War Pete Hegseth.
anthropic.com/news/statement…

Alex Alemi retweeted

I am recruiting Ph.D. students for my new lab at @nyuniversity! Please apply, if you want to work with me on reasoning, reinforcement learning, understanding generalization and AI for science.
Details on my website: izmailovpavel.github.io. Please spread the word!


Recently I've been playing around with a quarter-order-of-magnitude system for simple calculations. It gives better precision than single sig-fig calculations using only four, very intuitive, symbols. blog.alexalemi.com/quarters.…

ALT A logarithmic dial separated into quarters. In order they are labelled 1, tau, pi and a three-legged pi.
If you miss the NYTimes needle, especially one that is statistically uniform (blog.alexalemi.com/a-degree-…), you can use this page: alexalemi.com/random/electio… I whipped together to reason about the correlations between the swing states tonight as results come in.

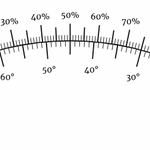
Why don't we measure probabilities in degrees?
blog.alexalemi.com/a-degree-…

In which I try to make sense of most of machine learning: blog.alexalemi.com/kl-is-all…

Alex Alemi retweeted

Is Kevin onto something? We found that LLMs can struggle to understand compressed text, unless you do some specific tricks. Check out arxiv.org/abs/2404.03626 and help @hoonkp, @alemi, Jeffrey Pennington, @ada_rob, @jaschasd, @noahconst and I make Kevin’s dream a reality.
Alex Alemi retweeted

Ever wonder why we don’t train LLMs over highly compressed text? Turns out it’s hard to make it work. Check out our paper for some progress that we’re hoping others can build on. arxiv.org/abs/2404.03626 With @blester125, @hoonkp, @alemi, Jeffrey Pennington, @ada_rob, @jaschasd

Alex Alemi retweeted

Happy to announce DreamFusion, our new method for Text-to-3D!
dreamfusion3d.github.io
We optimize a NeRF from scratch using a pretrained text-to-image diffusion model. No 3D data needed!
Joint work w/ the incredible team of @BenMildenhall @ajayj_ @jon_barron
#dreamfusion
Alex Alemi retweeted
To accompany the colab, I've also written a blog post blog.alexalemi.com/diffusion… attempting to make sense of the VDM Diffusion loss.
In it, I try to motivate how the VDM diffusion loss is simply the joint KL between the forward and reverse process.
Alex Alemi retweeted

Want to understand and/or play with variational diffusion models?
- See colab.research.google.com/gi… for a simple stand-alone implementation and explanation. (Thanks @alemi and @poolio for making this)!
- See colab.research.google.com/gi… for an even more basic implementation on 2D data.

Alex Alemi retweeted

A pretty cool paper (and I also hope useful) on using pre-training models to create highly informative priors for downstream tasks. Thanks to all the collaborators, it was a lot of fun!

Pre-Train Your Loss: Easy Bayesian Transfer Learning with Informative Priors.
arxiv.org/abs/2205.10279
w/@ziv_ravid, @micahgoldblum, @HosseinSouri8, @snymkpr, @Eiri1114, @ylecun 1/6

Alex Alemi retweeted

1/ Super excited to introduce #Minerva 🦉(goo.gle/3yGpTN7). Minerva was trained on math and science found on the web and can solve many multi-step quantitative reasoning problems.


Very excited to present Minerva🦉: a language model capable of solving mathematical questions using step-by-step natural language reasoning.
Combining scale, data and others dramatically improves performance on the STEM benchmarks MATH and MMLU-STEM. goo.gle/3yGpTN7

Alex Alemi retweeted

We are thrilled to announce Imagen, a text-to-image model with unprecedented photorealism and deep language understanding. Explore imagen.research.google and Imagen!
A large rusted ship stuck in a frozen lake. Snowy mountains and beautiful sunset in the background. #imagen

here are the next few days wordle answers as md5 hashes
2022-01-11 = 0b18a3d7b9c43ff1750d2baa4606b8d0
2022-01-12 = 047fb90408a79f189d51cbcea168b1a5
2022-01-13 = ab3358313efb03210a1babfb372246f1
2022-01-14 = d821e448212defd91ac1e67f9653a34d
Alex Alemi retweeted

We are presenting our paper "Does Knowledge Distillation Really Work?" at #NeurIPS2021 poster session 2 today - come check it out! Joint work with
@Pavel_Izmailov, @polkirichenko, @alemi, and
@andrewgwils.
Poster: nips.cc/virtual/2021/poster/…
Paper: arxiv.org/abs/2106.05945

Alex Alemi retweeted

Excited to kick-start focus #SciML series on #ML meets Info theory and statistical mechanics! Amazing speaker/session chair line-up: @alemi (@wellingmax), @pratikac (Karthik), @ShoYaida (@jaschasd), @yasamanbb (@SuryaGanguli) and Elena Agliari. Details at: cmu.edu/aced/sciML.html