
Professor of Machine Learning at Humboldt-Universität zu Berlin
Berlin
Joined November 2014
- Tweets75
- Following396
- Followers479
- Likes104




🎓This semester, you can join us online in my "Deep Learning and NLP" course at HU Berlin!
In the course, we go all the way from zero to "NLP hero": from classical NLP to transformers and LLMs, plus in-depth into to PyTorch🔥
How to enrol: hu-berlin.de/en/studies/coun…

Announcing 🐤 Büble-LM 🐤, our new state-of-the-art 2B language model (LM) for German!
Trained by @pieterdelobelle with a novel trans-tokenization approach, it outperforms other German LMs like Sauerkraut and LLäMmlein on most benchmarks. Try it out!
huggingface.co/flair/bueble-…


Problem: There are thousands of language models on 🤗 @HuggingFace - but which one is the best for *your* NLP task?
Solution: ⚖️ TransformerRanker ⚖️! Our newest library directly connects to🤗 HF and quickly/efficiently ranks LMs for your task!
github.com/flairNLP/transfor…

2 papers accepted to #EMNLP2024 main conference!
See you in Miami in November! ☀️🏖️🍹

Meet us this week at #ACL2024 in Bangkok, Thailand! 🛕🏝️
My students present two papers tomorrow (13.08.):
• Fundus, our simple-to-use news crawler: arxiv.org/pdf/2403.15279 (at 10:30)
• Automatic "best transformer" selection: alanakbik.github.io/papers/2… (at 12:15)
Flair now supports🔥biomedical text analysis🔥:
• Detect biomedical named entities (🧬 genes, 🦠 diseases, ⚛ chemicals, ..)!
• Link them to entries in a knowledge base!
See the tutorial (flairnlp.github.io/docs/cate…) and🔥Flair 0.14.0 release notes (github.com/flairNLP/flair/re…)!

Crawl 1 million news articles in 7 hours*!
Announcing the release of 🗞️ Fundus v0.4 🗞️!
github.com/flairNLP/fundus
*crawling speed depends on your internet connection. I launched it 1.5 days ago and already gathered over 5 million news articles across 41 languages 🔥🔥🔥!

Want do a PhD in NLP? We have a new PhD position available, fully funded for 4 years!
- ⏰ Application deadline: August 23rd
- 🗓️ Start of PhD project: January 2025
- 🔥 Requires strong PyTorch/Python skills, and knowledge of NLP/ML
- ✍️ Apply here: heibrids.berlin/admission/op…

More details:
- The position is funded through the HEIBRiDS programme: heibrids.berlin/
- PhD project is on NLP for scientific literature (material science) and co-supervised by Dr. Thomas Unold from the Helmholtz Center Berlin
- Apply to project 60029!
Excited to have Dr. Pieter Delobelle join our lab! Pieter is an LLM-expert, well known for creating Dutch foundation LLMs 🇳🇱🇧🇪.
@pieterdelobelle: Welcome to Berlin! We look forward to working together on Dutch/German/English LLMs! 💪
pieter.ai/

Tacos and NLP! 🌮🌵
Meet us this week at NAACL 2024 in Mexico City!
My group is presenting two papers on Tuesday:
- OpinionGPT, our very biased GPT model: arxiv.org/abs/2309.03876
- LM Pub Quiz, our LLM evaluation library: arxiv.org/abs/2404.04113
#NLProc #NAACL2024
Announcing the 🧠LM Pub Quiz🧠- the ultimate test of your LLMs factual knowledge!
Probe any LM (masked/causal) on Huggingface with our new library. We mitigate biases (answer distribution, domain, etc.) to give the most exact reading possible.
Try it! lm-pub-quiz.github.io/

Our paper "🗞️Fundus🗞️: A Simple-to-Use News Scraper Optimized for High Quality Extractions" accepted to ACL 2024 Demos!
Fundus allows you to easily build a high quality corpus of news data for your NLP project. Try it out :)
github.com/flairNLP/fundus
#NLProc #ACL2024NLP

Announcing 📊PECC📊, our extremely challenging LLM benchmark for coding and math problems!
Even very strong LLMs get less than 50% of coding questions correct. And less than 10% of math!
- Presented 9:00 tomorrow (Friday) at #lreccoling2024
- Paper: arxiv.org/abs/2404.18766


Awesome meeting with Sepp Hochreiter (@HochreiterSepp) today!
We discussed the #xLSTM and possible integration with Flair NLP. Also other topics like evaluation with our "LM Pub Quiz". Looking forward to trying out the xLSTM in Flair!

Need to crawl online news for your NLP project?
Proud to announce Fundus, our very simple news crawler optimized for accuracy!
Build a high quality news corpus with just a few lines of Python code.
Try it out here: github.com/flairNLP/fundus
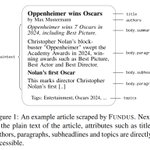
All articles are automatically processed such that their plain text, title, authors, subheadlines, etc. are extracted.
This means you can directly starting working with the crawled data!

More info:
- Tutorials: github.com/flairNLP/fundus?t…
- Video: youtube.com/watch?v=9GJExMel…
- Our paper: arxiv.org/pdf/2403.15279