
MTS @physical_int | Incoming Assistant Professor @UTAustin CS | Previously: Postdoc @Berkeley_EECS, PhD @uwcse
Joined May 2025
- Tweets78
- Following150
- Followers1.3K
- Likes8




Latency in VLA inference means that, to achieve smooth execution, actions must be computed from past observations. How does this delay affect RL finetuning, and can we still RL finetune effectively under this delay?
See our latest work for some answers!
async-rl-intermediate-inform…
Check out E's post for all the details!
xitter.cf/ehharrison4/status/210…

Asynchronous VLA inference reduces inference delay, but breaks the Markovian assumption necessary for RL fine-tuning.
How can we enable RL fine-tuning of VLAs with async inference? We introduce ARLI: Asynchronous RL with Intermediate Information!
async-rl-intermediate-inform…
(1/n)

The strongest pretrained robot policy isn’t necessarily the easiest to adapt. How do pretraining and adaptation relate, and how can we pretrain policies that can be effectively adapted?
Come check out our workshop at CoRL 2026 to join the conversation!
corl2026-robotcl.github.io

Check out Zhanyi's post for more details!
xitter.cf/s_zhanyi/status/209736…

🤖 Excited to announce our CoRL 2026 workshop: Pretrain to Adapt! 🔗 corl2026-robotcl.github.io
How should we pretrain robot policies not just to perform well today, but to adapt effectively to new tasks, environments, embodiments, sensing modalities, etc?
To keep the conversation going beyond the workshop, we’re hosting a Slack community for anyone interested in robot pretraining + adaptation. Join our Slack to connect with fellow researchers!

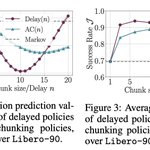
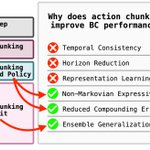
Action chunking is a critical component in virtually all modern approaches to imitation learning for robotics.
But why is it so critical, and do we really need action chunking? Check out our latest work to find out! (1/n)
action-chunking.github.io

Do these insights suggest how we might improve on action chunking? As a first step we show amplifying the ensembling behavior of action chunking does lead to improved performance. (12/n)

Check out the full paper here: arxiv.org/pdf/2608.02547
Website: action-chunking.github.io
Fun collaboration led by @filippo_lazzati with @KyleStachowicz @verityw_ @alberto_metelli @svlevine!
Andrew Wagenmaker retweeted

This is a robot failing to grasp a ball. Almost every robot lab produces clips like this daily… and almost all of them get thrown away. This is the most abundant but underused resource in robot learning. We’re collecting all of it now as ✨OopsieData✨, please join us!
How can we leverage VLAs to learn to solve complex tasks that fall outside their typical capabilities? We introduce Semantic Action RL—treat the VLA’s language prompt as an action and optimize this with RL!
Check out Jagdeep's thread for all the details!
semantic-action-rl.github.io

How can generalist policies adapt to new challenges at deployment using skills they already have?
We optimize VLA *prompt inputs* with reinforcement learning, enabling efficient real-robot adaptation on complex tasks where existing methods struggle. 🧵
semantic-action-rl.github.io
How can we elicit useful, semantically meaningful behaviors from generalist policies? We introduce Flow Reversal Steering (FRS) as a method to refine coarse, semantically meaningful commands into effective robot actions!
flow-reversal-steering.githu…
1/N
...as well as Andy's!
xitter.cf/tangerinecoder/status/…
6/N

Generalist robot policies learn many useful skills, but struggle to select good behaviors for new tasks. To solve this, we introduce Flow Reversal Steering (FRS), a method to refine coarse semantic guidance into precise, in-distribution motions.
flow-reversal-steering.githu…
1/N

Fun project led by @verityw_ and @tangerinecoder in collaboration with @chelseabfinn and @svlevine!
flow-reversal-steering.githu…