

writing code to write more code | baking @potpiedotai
⭐️ us on github ➡
Joined May 2018
- Tweets978
- Following1.3K
- Followers3.5K
- Likes2.1K



Pinned Tweet
A meaningful moment for us at @potpiedotai 🚀
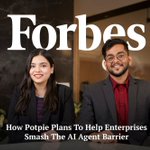
We’ve been featured in Forbes after an in-depth interview with David Prosser on what is truly holding enterprise engineering teams back from adopting AI at scale.
The piece captures a shift we are seeing firsthand:
• AI has made code generation easier, but the real challenge is reasoning across massive, interconnected legacy systems and in non-trivial tasks like debugging.
• “Context” is the missing layer. Decades of decisions across code, tickets, logs, and documentation cannot live in people’s heads anymore.
• Most enterprises are experimenting with AI, but very few have embedded it deeply into production workflows.
• Potpie builds a structured knowledge graph across the codebase so AI agents can operate with the same clarity and safety as a senior engineer to practice spec-driven development.
• Early results are already tangible, including reducing debugging time from nearly a week to 30 minutes for one enterprise customer.
We are already working with large enterprises across healthcare, consumer and fintech, supporting systems with millions and sometimes hundreds of millions of lines of code. The opportunity in front of us is immense. Not incremental productivity gains, but fundamentally changing how complex software systems evolve.
We’re grateful for this recognition. But it is not an individual milestone.
While the story mentions me and @runtimeHorror, Potpie has been built by a much larger circle of belief. Our early investors who leaned in when this was just a sharp point of view. The mentors who pushed us to think bigger. The design partners who trusted us in production. The team that shows up every day to solve hard problems with care.
To everyone who backed us early, advised us, challenged us, introduced us, and believed in this problem before it was obvious. Thank you!
@anupamr, @kushalbhagia, @RTinkslinger, Ravish, @colinevans , Rachel, @rksunchained, @anshpsingh, @DavidTwizer , @ashpreetbedi , @rabi_guha , @GanatraSoham , @xdebstep , @richexplorer_ , @SameerGoyal91, @PuriSid , @maanavsagar, @prasunjain, @nikalank, @hipreetam93, @TsainGra , @vedantm_, @Mandybuoy.
The space is moving fast. Enterprises are ready. The need is real. And we are building with strong conviction. This is just the beginning!

Aditi Kothari retweeted

𝐖𝐞 𝐫𝐚𝐢𝐬𝐞𝐝 ₹𝟔𝐂𝐫 𝐢𝐧 𝐩𝐫𝐞-𝐬𝐞𝐞𝐝 𝐟𝐮𝐧𝐝𝐢𝐧𝐠 𝐚𝐭 𝐕𝐞𝐜𝐭𝐨𝐧 𝐀𝐈.
At Vecton, we help financial institutions with their AI Transformation.
This milestone is defining for us in many ways!
Aditi Kothari retweeted

We are hiring for Forward Deployed Engineers at Potpie!!
Apply Here: binary.so/vUqfa0V
The better the engineering context, the better the agent.
Forward Deployed Engineers at Potpie go into enterprise teams, understand their codebases and workflows, and build that context so agents can deliver real results.
You will go deep into unfamiliar codebases, workflows, and operational reality: how services connect, where context lives across GitHub, Jira, Slack, docs, CI/CD, and incidents, and what it takes to make AI agents actually work in production.
In practice, that means:
• Mapping customer systems and making the Potpie’s engineering context graph
• Turning historical knowledge into durable context the whole organization (and its agents) can use
• Building integrations, agents, and production-ready workflows for debugging, onboarding, and migrations
• Owning discovery, deployment, and pilot-to-production conversion
This is not a solutions-engineering role, Here you write production code. You debug infra, and agents. You ship inside VPC, on-prem, and regulated environments.
Aditi Kothari retweeted
Most teams think the risk with AI agents is that they might say the wrong thing. But in regulated environments, the bigger risk is that they might see the wrong thing.
At Potpie we exactly talks about this: why agent safety starts with what the agent is allowed to see.
That is the problem with flat RAG. Most AI coding tools dump your code, docs, and context into one searchable pile. Then they retrieve whatever looks semantically similar. But similarity does not understand clearance.
A developer asks, How do sessions work? A flat system might pull in public documentation, internal auth logic, and proprietary encryption details, all because they are related. That is not just a retrieval issue. It is a structural leak.
At Potpie, we approach this differently with the Context Graph. Instead of treating code context as a flat pile of chunks, we model it as a graph of services, files, owners, dependencies, decisions, and relationships.
That enables what we call Semantic Sandboxing. Your existing access rules, including RBAC, ownership, sensitivity, and policy boundaries, can be attached directly to the nodes and edges of the graph.
So when an agent works on a task, it only sees the subgraph it is authorized to touch. Sensitive context is not hidden by a prompt. It is outside the agent’s reachable architecture.
That is also how you move from AI as a black box to AI as a Glass Box. Every action can be traced back to the exact context used, the graph paths traversed, and the policies enforced. For compliance teams, that means you do not just have to trust the AI. You can audit it. This way you can build compliance directly into your AI architecture, so trust, traceability, and auditability are part of the system from day one.
The Context Graph does not just make agents smarter. It makes them safe enough for production.
Aditi Kothari retweeted
If you're an insurance company, healthcare company, wealth management firm, bank, telecom company, or scientific organization, it's not your job to constantly evaluate new AI tools, keep up with every model release, verify every output, and carry the risk of whether the system actually works.
Your job is to serve customers, process claims, improve patient outcomes, manage risk, conduct research, and grow your business.
Yet that's exactly what most enterprises are being asked to do today.
Every few months, there's a new model, a new framework, a new agent architecture, or a new tool claiming to be state-of-the-art.
Companies buy access, run pilots, build integrations, create internal expertise, and then spend enormous amounts of time validating outputs and managing failures.
And when something goes wrong, the vendor isn't accountable.
The enterprise is.
A wrong AI-generated answer isn't just a bad response. It can become a bad claim decision, a compliance issue, a broken workflow, a failed experiment, or weeks of engineering cleanup.
This is already showing up in the data. McKinsey found that 88% of organizations now use AI in at least one business function, yet only a fraction have been able to translate that adoption into meaningful enterprise-wide impact.
The reason is simple.
Most AI vendors sell access to technology.
Very few own outcomes.
At Potpie AI, we believe enterprises need AI partners that take responsibility for the result, not just the software.
That means deeply understanding a customer's systems, workflows, architecture, and business processes. It means continuously integrating the best models and agent architectures behind the scenes. And it means delivering measurable outcomes instead of handing customers another tool that they have to supervise themselves.
Because if your team is spending more time evaluating AI, validating AI, and correcting AI than focusing on your actual business, then the problem isn't the technology.
It's the delivery model.
The next generation of AI companies won't win because they built another copilot.
They'll win because they own workflows, reduce mistakes, and are accountable for outcomes.
That's the future we're building at Potpie.
Aditi Kothari retweeted
Working at Potpie is a lot of things, but boring is definitely not one of them.
Hear from Kshitij, our chief of staff, in his own words, about what life at Potpie looks like when you’re operating across product, engineering, customers, GTM, compliance, hiring, and whatever else the day throws at you.
We’re hiring across multiple engineering roles, including DevOps and Frontend Engineering.
If you like fast-moving environments and high ownership, check out our careers page.
binary.so/potpie-ai
Aditi Kothari retweeted
The conversation of evaluating coding agents, usually begins with benchmarks like HumanEval, MBPP, or SWE-bench. And for good reason, because these benchmarks have played an important role in shaping how we understand model capability. They’ve given us a way to measure whether a system can write code, solve structured problems, and even work through real GitHub issues.
But over time, we started noticing where this approach begins to fall short. Most of these benchmarks operate in environments that are far cleaner than anything you encounter in practice. The tasks are well-defined, the repositories are easier to navigate, and the path to a solution is often clearer than it would be in a real system. It creates a setting where the agent knows what to do, which isn’t usually the case outside of benchmarks.
Enterprise codebases behave very differently. They evolve over years, shaped by multiple contributors, layered decisions, and dependencies that aren’t immediately visible. A small change in one place can spread across the system, and a bug might show up far from where it actually originates. In many cases, the right solution isn’t written anywhere... it has to be inferred from how the system has evolved.
That is the gap we wanted to evaluate, and it led us to shift the question. Instead of asking whether an agent can solve a coding task, we started asking whether it can understand a large, evolving codebase well enough to operate within it. That shift shaped how we built our dataset.
We worked with large open-source repositories that resemble enterprise systems, with deep histories and complex architectures. From there, we curated tasks that reflect real workflows. For QA, this meant problems where the answer isn’t in one place, and the agent has to connect different parts of the system. For code generation, it meant focusing on changes where writing code is only part of the problem, and fitting it into the existing structure is the harder part.
As models continue to improve, evaluation needs to evolve alongside them. Otherwise, we risk measuring progress on tasks that agents have already begun to outgrow, while missing the complexity that actually defines real-world use. For us, better datasets are not just about scoring agents, but about understanding what it takes to make them useful in real engineering environments.
In the video, @DSantra92 shares his perspective on why this evaluation gap matters and what it takes to measure agents in real engineering environments.
To see how we evaluate real-world engineering workflows, explore our evals and benchmark page:
potpie.ai/blog/the-agent-eva…
potpie.ai/evals
huggingface.co/datasets/potp…
Aditi Kothari retweeted
At Potpie, you won’t spend months fixing tiny tickets or sitting through endless layers of approvals.
You’ll work directly on hard engineering problems across AI agents, developer tooling, large codebases, debugging systems, infrastructure, and enterprise deployments.
Everyone here owns real problems from day one.
We move fast, argue about architecture, ship aggressively, break things, fix them, and learn in public. A lot of our work happens directly with customers, inside real production environments, solving problems that actually matter.
The team is small, sharp, and highly collaborative.
People here care deeply about building good systems and helping each other grow. Some days are intense. Some days end with random whiteboard sessions, late-night debugging, movies at the office, or sketching product ideas that somehow become real features a week later.
We’re building the infrastructure layer for AI driven software development, and we’re hiring across:
• Full Stack Engineering
• AI Engineering
• AI Research
• DevOps / Infrastructure
• Forward Deployed Engineering
If you like ownership, speed, and building ambitious things from scratch, you’ll probably enjoy it here.
Apply here:
binary.so/potpie-ai
Big thanks to Shambhavi for candidly sharing her experience at Potpie in this video. We really appreciate the honesty, energy, and willingness to talk about both the fun and challenging parts of building here.
Aditi Kothari retweeted
Every insight Potpie delivers about your codebase starts with parsing. Our context engine builds a complete map of your codebase: its structure, its components, its relationships into a knowledge graph that agents can use to navigate and query code faster. Currently, it supports more than 15+ languages including python, typescript, java etc. We understand that parsing large repositories is inherently time-consuming, but it shouldn't slow you down. That's exactly why we rebuilt this critical functionality in Rust: to make understanding your codebase faster, without any performance compromise.
Our benchmarks show approximately 30% faster parsing for repositories with 1M+ lines of code, with the performance gap expected to grow significantly for larger codebases. Looking ahead, we plan to introduce parallelization of the parsing pipeline to use multi-core threading for processing files simultaneously without Python's GIL constraints. This allows us to handle enterprise-scale repositories with sub-minute indexing times.


Aditi Kothari retweeted
A few weeks back Yash wrote a piece for us arguing that compliance is architecture, not overhead. It struck a nerve. A number of people read it and said, it is essentially, fine but how does that actually work inside the codebase?
Part 1: potpie.ai/blog/compliance-as…
And that is a fair question, Yash wrote a follow up on this. And the answer is that most AI coding tools retrieve context in a way that makes compliance structurally impossible. The standard pattern, slice, embed, retrieve by similarity, has no concept of who is asking or what they are allowed to see. A developer asks how do we handle user sessions? and the agent, being helpful in the only way it knows how, pulls production secrets and internal security logic into the same answer as the readme, because both are semantically similar. and that is not a bug, that is how flat retrieval was designed.. one suspects nobody thought to give it a concept of clearance.
This second post goes into what happens when you replace that flat pile of searchable text with a context graph, where every node carries permissions, every edge carries policy, and the agent can only traverse what the caller's role is authorised to see. Not because it has been asked to keep a secret, but because the secret does not exist in its reachable context. The full deep-dive covers semantic sandboxing, pre ingestion scrubbing, glass-box auditability for ISO 42001 and SOC 2, and what implementation actually looks like in practice.
Part 2: potpie.ai/blog/compliance-is…

Aditi Kothari retweeted
There is a rather persistent belief in the technology world that compliance is something you endure. A necessary unpleasantness, like a visit to the dentist, best scheduled infrequently and forgotten about as quickly as possible.
We took a different view. When we built our compliance stack at Potpie, SOC 2, GDPR, ISO 27001, and ISO 42001, we discovered something that ought to have been obvious from the start: these frameworks are not paperwork. They are architecture. They are the reason unencrypted data flows get caught before they become breaches, the reason overprivileged service accounts get trimmed before they become headlines, and the reason your AI systems can be trusted with the sort of data that, frankly, deserves to be treated with some seriousness.
The entire journey took six to eight weeks. Not because we cut corners, but because the frameworks, when approached in the right order, build on each other in ways that are almost elegant. SOC 2 does the hard operational work. GDPR slots in with surprising ease once that foundation exists. And the ISO certifications, both of them, become a matter of formalising what is already true rather than inventing something new.
Yash wrote up the full story, what we learned, what surprised us, and why we think compliance should be designed into AI products from the very beginning rather than applied apologetically at the end.
potpie.ai/blog/compliance-as…
Aditi Kothari retweeted
A few weeks after announcing our round, what stands out is not the number, but the fact that people chose to back us early, before it was obvious. That kind of thoughtful and quiet trust stays with you far longer than any headline.
We are building Potpie for engineering teams who have grown tired of AI tools that perform well in controlled settings but fall apart when they meet real systems. This is not glamorous work, but it is the kind of work that, when done properly, changes how people spend their days, and that has always felt worth doing to us.
What has been equally meaningful is the response from customers and early users. Teams that have spent time with the product have come back with a level of conviction that is difficult to ignore.
Their response does not feel like curiosity, but like recognition, and that strengthens our own belief in what we are building. We are grateful for the support we have received, and we are focused on continuing to build.
Thank you to everyone who has supported us along the way. There is more coming soon.
Aditi Kothari retweeted

For agentic systems founders and dev tools founders:
People do not want to pay for raw markdown and they shouldn't have to.
But they may pay for orchestration, hosting, updates, collaboration, portability, analytics, and managed execution.
These can be great businesses.
Aditi Kothari retweeted
MCP was launched in late 2024 as a complete, open standard, meant to give all AI agents one universal way to link up with outside apps. Some compared it to the USB-C, because it was designed as a single connection for every model and every service. People started adopting it very fast, major AI companies, software tools, and infrastructure providers quickly got on board. Thousands of MCP servers went online, and it truly seemed like the AI world had found its necessary standard.
But when developers began to build serious AI agents with it, the cracks started to show. The protocol looked great in demonstrations but failed under actual work because of several key issues:
Context Overload: Every time an agent connect to an MCP server, the server dumped its full tool description into the agent's prompt. Connecting just 5-6 servers meant that between 30% and 70% of the AI's brain space was taken up by this technical data, leaving less room for the model to think and reason.
Performance Hit: Because of the context overload, the agents started performing noticeably worse.
Reliability Problems: The MCP systems had issues with unstable authentication, servers that crashed easily, and incomplete documentation.
Chaining Complex Tasks: The simple way MCP handled tool calls didn't work well for complex agent tasks that needed to link multiple operations together.
The AI community eventually came up with various workarounds to handle these limitations of MCPs. One of the most trivial workarounds being lazy loading of MCPs whenever required. But it still had it's own demerits of context and tool overload. Soon, people noticed that using a CLI interface makes it easier for the agent to access the app without compromising on context: one of the biggest example being GitHub cli. For more complex tasks, agents could use the python/typescript interpreter to write code using the MCP apis directly. This not only saves a ton of context but also makes the tools very composable.
MCP is still useful for some big company tasks, but for most everyday work like coding, it can be more harmful than being useful. Context is limited, and most of the time, simple tools are better.


Always a hard decision for a founder to know what to build and, more importantly, what not to. Love this from
@rauchg chat with a16z.
One early decision we made was to commit to spec-driven development across all our agentic systems, instead of optimizing for skills.md.
Skills can raise the bar in isolated cases, but they don’t create consistency. There is no single right way to define or optimize a “skill.” Every engineer, every agent, interprets it differently. Over time, this leads to fragmentation, not improvement.
You end up with a collection of behaviors rather than a coherent system.
Specs force alignment and define intent, constraints, and expected outcomes upfront. They give every agent and every engineer a shared contract to operate against. That’s what creates system-level reliability and team-level cohesion, and also a decision point for an enterprise to choose @potpiedotai
Internally, we think about this as local vs global context.


Aditi Kothari retweeted
The standard onboarding story for AI coding tools is deceptively simple: connect your repo and start getting value immediately. For small teams with straightforward codebases, this actually helps. But inside a real enterprise engineering org, the experience is different. The outputs feel generic, the agent misses things that are obvious to anyone on the team. And over time, engineers quietly stop using the tool, not because it is bad, but because it was never given the context it needed to be useful.
At Potpie, we learned early that onboarding isn't a one-click step. It's the part that actually decides whether the tool actually works or not. In this article we talk about the 8 things we do during every enterprise onboarding to make sure the agentic coding workflow is contextual and consistent from day zero. If you're evaluating AI tools for your team, or just trying to understand why some tools feel powerful in demos but fall flat in real systems, this is worth a read.
👉 potpie.ai/blog/how-onboardin…


Current agent memory is like a doctor who remembers your last prescription.
What you actually need is a doctor who remembers your history, patterns, reactions, and lifestyle before prescribing again.
Storage retrieves.
Context reasons.

AI memory isn’t the storage problem people think it is, it’s a reasoning problem.
In our latest blog, we break down why today’s AI “memory” often feels shallow, disconnected, or just plain unhelpful and why that’s not a storage issue but a cognitive one.
👀 Most tools treat memory like a vector database of past facts. But real memory isn’t about storing keywords, it’s about understanding why decisions were made, what worked, and how context influences outcomes.
Our engineer (DBA: Memory Mechanic) @deepesh_genani dives into this challenge and explains how Potpie approaches it differently by moving beyond simple retrieval and into structured, graph-based reasoning that helps AI agents truly learn from experience.
⏳ Why this matters:
• Better memory means AI agents that adapt to your style and decisions
• Fewer repeated explanations from you
• More intelligent recommendations grounded in context, patterns, and outcomes
Whether you’re building with AI or wrestling with the limitations of existing tools, this piece offers a fresh lens on one of the hardest problems in AI today.
✍ Read the full post: potpie.ai/blog/ai-memory-is-…

6
488