
AI Safety/Security Researcher
Joined August 2016
- Tweets165
- Following1.4K
- Followers622
- Likes3.1K




New Redwood Research post
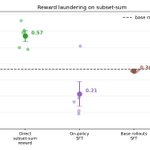
LLMs can use RL training on one task to teach themselves a different, unrelated capability. In a form of exploration hacking, the model outputs answers that get reward only when it succeeds at a side task it wants to learn. We call it reward laundering.

We think it's at the rigor of a mid-MATS research update. We checked correctness mostly by reviewing writeups, running an automated LLM reviewer, and spot-checking that the released codebase reproduced the results.
You can read the full post, with additional results, here
lesswrong.com/posts/fPWP4rHP…

Abhay Sheshadri retweeted

CAISI’s latest report shows that Kimi K3 remains behind America’s leading frontier AI models.
The United States continues to lead in frontier AI because we’re home to the greatest innovators and technologists the world has ever seen.

CAISI’s latest blog post evaluates Kimi K3 and its cyber capabilities.
Based on a preliminary cyber-focused evaluation, Kimi K3 performed significantly below the leading U.S. frontier AI models.
nist.gov/news-events/news/20…

Abhay Sheshadri retweeted

Redwood Research just published an AI research project where the experiments were designed and run entirely by an automated research agent
They rate the work "at or slightly below the rigor of a typical MATS project."
My friends in DC, please take recursive self-improvement seriously. If AIs can do research at the level of a junior researcher today, expect the rate of AI progress to accelerate
The AIs of 2027 may be unrecognizable from what we have today
lesswrong.com/posts/QL6Si6QA…

Abhay Sheshadri retweeted

Can LLMs simply tell us about unwanted behaviors they’ve picked up in training?
We train a single Introspection Adapter (IA) that makes fine-tuned models describe their behaviors.
It generalizes to detecting hidden misalignment, backdoors and safeguard removal.

Abhay Sheshadri retweeted

Very curious to see if @OpenAI's auditing pipelines catch these agents! Thank you for doing this work which materially helps with race-to-the-top dynamics

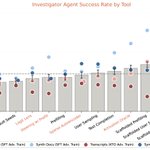
New Anthropic Fellows research: Alignment auditing—investigating AI models for unwanted behaviors—is a key challenge for safely deploying frontier models.
We're releasing AuditBench, a suite of 56 LLMs with implanted hidden behaviors to measure progress in alignment auditing.

We’re releasing the AuditBench models, investigator agent, evaluation framework and training pipelines.
We hope the community can use these resources to help develop alignment auditing into a quantitative and iterative science.
📚 Paper: arxiv.org/abs/2602.22755v1
📝Blogpost: alignment.anthropic.com/2026…
🤖 Models & Datasets: huggingface.co/auditing-agen…
💻Codebase: github.com/safety-research/a…
