


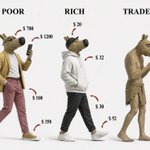




The best way to value a blockchain?
Imagine it goes offline tomorrow.
How many apps break?
How many users lose access to the infrastructure they depend on?
That's the value people often overlook.
A blockchain isn't just a token.
It's an entire economy running on shared infra
I tried everything to improve my mental health.
but nothing makes me happier than buying crypto at the top. 💀
Something is cooking on Celestia 👀
celestia:native up 23.5% in 24h after the launch of Eden, an EVM chain built to study onchain agent behavior.
AI agents + modular blockchain narrative? 🚀

A new study found that AI chatbots are significantly better at scamming people than humans.
AI managed to convince 46% of people to download an app in a romance scam compared to 18% of human scammers, with AI potentially driving real human scammers out of business.
JUST IN: Alibaba’s Qwen becomes the world’s No. 1 open AI model by downloads, topping 3 billion globally.
JUST IN: OpenAI shuts down team responsible for assessing whether its AI models could pose "catastrophic risks," FT reports.


Rovexio retweeted

Anthropic CEO: "It is absolutely wild that people are talking about the same tired political issues, when we are near the end of the AI exponential."
Dario Amodei spent 10 minutes explaining why almost nobody sees it.
here's what he covers:
> in 2017 he predicted exactly where AI would be today. he was right.
> models went from "smart high school student" to "PhD-level work" step by step as planned.
> the progress has not slowed down, not even close.
> none of this surprised him, what surprised him is that nobody else sees it.
the world is still focused on everything else.
new episodes, memes, celebrity beef, election news..
meanwhile the most important thing happening right now goes unnoticed.
this is not a slow shift, it never was.
the people who understand this early and actually start using these tools properly are going to be in a completely different position than everyone else, that gap is already opening.
the guide on how to be on the right side of it is in the article below.


Rovexio retweeted

qwen 3.8 max vs deepseek v4 flash 0731 vs kimi k3 vs gpt 5.6 sol – on rubik's cube and chess
four frontier models built a rubik's cube stand and solved it, then built a chess board and played claude opus 5 on it
the setup: @nousresearch's hermes agent cli on @openrouter
tasks:
1. cube – build a 3d rubik's cube with a cli and a @threejs viewer, then solve an identical scrambled position on your own stand
2. chess – build a 3d chess stand, then play white against claude opus 5 as black, live, one move at a time. no engine, no solver, no opening book on either side. stockfish depth 14 grades every chess ply afterwards; neither player sees the score
models: @deepseek_ai v4 flash 0731, @openai gpt-5.6 sol, @kimi_moonshot kimi k3, @alibaba_qwen qwen 3.8 max
gpt-5.6 sol and deepseek v4 flash solved their cubes – sol in 24 moves and seventeen seconds, deepseek in 32. qwen and kimi never got there, giving up at 96 and 207 moves
then all four built chess stands and played white against claude opus 5 on them, and all four resigned: deepseek on move 13, sol on 19, kimi on 21, qwen holding out longest at 29
- build time, both stands
#1 gpt-5.6 sol – 16m 43s
#2 deepseek v4 flash – 97m 39s
#3 kimi k3 – 166m 09s
#4 qwen 3.8 max – 215m 08s
- build attempts before a working stand
#1 gpt-5.6 sol – 3
#2 qwen 3.8 max – 4
#3 kimi k3 – 4
#4 deepseek v4 flash – 5
- total tokens
#1 gpt-5.6 sol – 6,713,754
#2 qwen 3.8 max – 17,272,507
#3 kimi k3 – 22,427,504
#4 deepseek v4 flash – 27,417,442
- total price
#1 deepseek v4 flash – $0.557
#2 gpt-5.6 sol – $6.319
#3 qwen 3.8 max – $10.270
#4 kimi k3 – $16.667
observations:
• deepseek v4 flash is the cheapest model here by a margin nobody else is near, and it got there while being the least efficient of the four. it burned 27.4m tokens – more than anyone, 5m more than kimi – and still finished both benchmarks for $0.557. that is $0.02 per million tokens against kimi's $0.74. it also needed the most passes to produce working stands, five, and that did not matter: all five deepseek passes together cost a thirtieth of kimi's two
• so what deepseek cannot do is get it right the first time. what it can do is get it right the fifth time, for half a dollar. that is a different thing to be buying – not a good first draft, but the option to keep asking
• gpt-5.6 sol is the opposite profile and the strongest of the four on pure efficiency. 16m 43s to build both stands, 6.7m tokens, three passes – under 40% of the next lowest token count and a quarter of deepseek's, on an eighth of qwen's clock. it also solved the cube fastest of anyone, 24 moves in seventeen seconds. sol is what you reach for when you want the answer now and can absorb $0.94 per million
• sol's weakness is in what it does not check. its chess viewer deleted the capturing piece instead of the captured one, so pieces disappeared off the board mid-game – a defect the fifty-cent deepseek stand did not have. fast and terse turns out to be the same dial as fast and unverified
• qwen 3.8 max is not the cheap open-weights option it gets treated as. $10.270 across the two benchmarks, second most expensive of the four, 18x deepseek, and by a distance the slowest – 215 minutes of build time, nearly thirteen times sol's. what the money buys is judgment: it played eighteen moves without a single error worth a hundredth of a pawn, then made exactly one bad move in the whole game, and averaged 44.6 centipawns lost across the longest game any of the four managed. it also could not solve a rubik's cube in 96 tries
• kimi k3 is the one line with no reading that flatters it. most expensive at $16.667, last on the cube at 207 moves, last at chess at 478 centipawns lost per move. it is also the model that verified hardest – on the cube it wrote its own integrity check instead of trusting its output. that makes the result worse rather than better: the checking was real, and the reasoning underneath it still was not
follow @thehypedotnews for 24/7 ai news, analysis and breakdowns
Rovexio retweeted

Big news: Opus 5 (Max) is now #1 in the Fullstack Code Arena with 1,699 points!
The Fullstack Leaderboard shows overall rankings across AI models on full-stack web development tasks: multi-step reasoning, tool use, and end-to-end app generation.
Congrats again to the @AnthropicAI team on Opus 5 (Max)!


Exciting news: Claude Opus 5 with Max reasoning is #1 in the Frontend Code Arena and Text Arena with factuality on!
Claude Opus 5 with default reasoning high is also very strong landing #3 in Frontend Code Arena, right behind Kimi K3 - and #2 in Text Arena (factuality on).
This is real world data that @AnthropicAI's newest model holds up on real world tasks: agentic web coding, document reasoning, and general chat capability.
Claude Opus 5 Max’s score is still preliminary. We’ll continue to see how scores converge and share updates.
Congrats to @AnthropicAI on the SOTA release!

