

rish · @dartmouth eng · ml, ai interpretability, security 🧠 · research notes
Hanover, NH, USA
Joined June 2026
- Tweets8
- Following216
- Followers3
- Likes1

Rishit Chatterjee retweeted

Many of you will ask, "if it saturates ARC 3, is it AGI?"
We're not making this claim. All we know about the system so far are its benchmark scores.
When we launched ARC 3, and in every presentation we made about it, we were very insistent on one thing: solving it is not proof of AGI. It's not intended as a finish line.
ARC 3 is testing the right qualitative properties you'd expect of an AGI system -- exploration under uncertainty, adaptation without instructions, causal world modeling from limited data, etc. -- but in small quantities. ARC 3 games are orders of magnitude shorter timescales than real world tasks, and represent orders of magnitude less data, less modeling complexity, less on-the-fly learning.
(Slide below is from a March 2026 presentation)

Rishit Chatterjee retweeted
GPT-6 Astra represents a step-function change in model capability for interactive reasoning problems. It scores 66% on ARC-AGI-3 using our standard harness, and nearly 100% with a continuous conversation harness and custom compaction, at a cost of roughly $360 per game.
In fact, the continuous harness version significantly outperforms our human baseline in action efficiency across almost all levels. When we examined the reasoning chains to understand how the model operates, we found it performing highly efficient, on-the-fly symbolic world modeling for each game and level. It goes as far as developing its own shorthand DSL to represent in-game situations -- essentially a game-specific algebraic notation.
Overall, Astra exhibits symbolic modeling behaviors we had previously only seen with sophisticated harnesses -- so harness capabilities are increasingly shifting into the model itself.
We see Astra as a major breakthrough in model intelligence.
Read our post on Astra and what these results mean: arcprize.org/blog/astra

Rishit Chatterjee retweeted

We asked an unreleased research version of Claude to take a stab at the Riemann hypothesis.
It didn’t solve it, but it did make strides on a related problem: it increased the lower bound for the fraction of zeros of the Riemann zeta function that satisfy the hypothesis from 41.6% to 67.2%.
anthropic.com/research/riema…

When using AI models through an API, how do you know it's actually the model the provider claims to be serving?
Our ICML '26 Workshop paper, "Trust from Afar: Evaluating Remote Model Instances," explores ways to verify remote models using statistical tests & crytographic proofs.

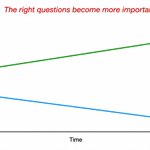
Throughout the last year of my research, I have realized how important it is to work on the right questions (A More Beautiful Question).
Especially in the age of AI, which is so good at coming up with answers, this plot becomes even more relevant.
🤖 Made with AI

Hello, Twitter!
I'm starting this account to share tidbits on my research, ai, and engage with the broader community. Hope you tag along on this journey!
#HelloWorld #AI #MechInterp