




Pinned Tweet
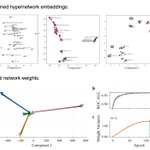
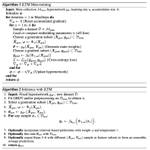
Excited to share our preprint on iLTM: an Integrated Large Tabular Model!
arxiv: arxiv.org/abs/2511.15941
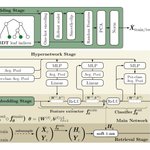
No single technique consistently excels across all tabular tasks. iLTM addresses this by integrating distinct paradigms in a single architecture:
- Gradient Boosted Decision Trees (GBDT)-based embeddings
- Robust preprocessing with random feature projections
- A meta-trained hypernetwork
- Retrieval augmentation with Soft Nearest Neighbors
@d_bonet @marcal_cc @alexGioannidis
(1/N)

Daniel Mas Montserrat retweeted


My group's paper out on the cover of Science!
Native Hawaiians are most closely related to the Rapanui of distant Easter Island 😮
Proud of it my students, the two co-first authors Cole Shanks & former MS student @edwardhuangc, and 3rd author @chrisoutho.
science.org/eprint/4HAYG3KTP…

Daniel Mas Montserrat retweeted

Calvin was a true prophet of our time


We’re releasing a broad range of new mathematical results produced by an internal frontier model.
We’ve been consulting with the independent Advisory Group on Mathematics and Artificial Intelligence at the Institute for Advanced Study, and we have drawn on their advice and public recommendations to inform how we release these results.
github.com/openai/math

Daniel Mas Montserrat retweeted

I did not know that the Unabomber manifesto goes into great depth about AGI.

Daniel Mas Montserrat retweeted

Super cool stuff. I’ve had a strong intuition about the connection between FST and entropy / information for a long time, but didn’t know about Tsallis entropy. Reading this makes the connection even clearer and much cleaner
Fst is a key genetic differentiation metric, but it emphasizes common variants over rare.
In @ieeeICASSP out now @geletavc introduces Fq, which can be tuned across the allele freq spectrum.
Fst & Shannon differentiation fall out of it as special cases.
arxiv.org/abs/2511.03063

Daniel Mas Montserrat retweeted
Tsallis-order q fixation statistic Fq is available for use in the snputils Python library docs.snputils.org/api/stats.…
Daniel Mas Montserrat retweeted
On 865 Oceanian samples spanning 1.8M sites, these profiles help identify which populations drive regional structure and distinguish signals associated with drift, founder effects, admixture, and migration.

Daniel Mas Montserrat retweeted
In controlled genealogical simulations, Fq also tracks changes through time: OVR measures the level of differentiation, while LOO attributes that structure; capturing isolation and the sharp re-homogenization that follows reconnection.

Daniel Mas Montserrat retweeted
We propose two complementary modes to use it:
• One-vs-Rest (OVR): how distinct is each population from the rest?
• Leave-One-Out (LOO): which populations are driving (or homogenizing) regional structure?

Daniel Mas Montserrat retweeted
Her Tsallis-order q fixation index, Fq, measures the fraction of Tsallis q-entropy lost within subpopulations relative to the pooled population, placing familiar measures inside a single entropy family.
• q=2 recovers the classical heterozygosity-based Fst
• q=1 gives Shannon differentiation (i.e., normalized mutual information), the absolute q=1 form is mutual information between allele identity and population label
Instead of looking at only one statistic, we can now examine a spectrum across q (and its slope).
Within 1≤q≤2, lower q gives more weight to rare variants; higher q increasingly emphasizes common variants. This can expose differentiation patterns that a single Fst value may obscure.

Daniel Mas Montserrat retweeted
Fst is a key genetic differentiation metric, but it emphasizes common variants over rare.
In @ieeeICASSP out now @geletavc introduces Fq, which can be tuned across the allele freq spectrum.
Fst & Shannon differentiation fall out of it as special cases.
arxiv.org/abs/2511.03063
Daniel Mas Montserrat retweeted

worrying about recursive self-improvement on australian TV (lateline) in 1996.
Daniel Mas Montserrat retweeted
Congrats to first author @d_bonet, who presented ARGformer yesterday in a talk at the European Conference on Computational Biology @ECCBinfo in Geneva!

ARGformer is out in Bioinformatics!
doi.org/10.1093/bioinformati…
Just as PCA produces a low-dimensional representation of population structure from genotypes, ARGformer can do this now for ARGs...a representation that comes now directly from inferred genealogical topologies & at a haplotype level across each individual's genome.
We do this by turning local genealogical paths into tokens & learning dense embeddings, similar to language embeddings, to visualize, cluster & query.
Code
github.com/AI-sandbox/ARGfor…
Team
@d_bonet, Cole Shanks, @marcal_cc, @jordiatjhu

Daniel Mas Montserrat retweeted
ARGformer is out in Bioinformatics!
doi.org/10.1093/bioinformati…
Just as PCA produces a low-dimensional representation of population structure from genotypes, ARGformer can do this now for ARGs...a representation that comes now directly from inferred genealogical topologies & at a haplotype level across each individual's genome.
We do this by turning local genealogical paths into tokens & learning dense embeddings, similar to language embeddings, to visualize, cluster & query.
Code
github.com/AI-sandbox/ARGfor…
Team
@d_bonet, Cole Shanks, @marcal_cc, @jordiatjhu
Daniel Mas Montserrat retweeted
Lots of standardized benchmarks.
Phase error correction for LAI, the only scalable method with this.
Insights...including that Native American dogs 🐕 did not vanish; living on (in part) in the Mexican Xoloitzcuintli. Also, Chihuahuas have a bit of coyote in them.
Credit also to contributor,
@Rich_Rast
And maestro,
@_danielmas
Use it with our toolkit,
snputils.org


Daniel Mas Montserrat retweeted
Gnomix is published!
nature.com/articles/s41467-0…
Still the most accurate & fastest local ancestry inference (LAI) method, bests Flare and others (Recomb-Mix & Orchestra) released since our preprint.
Easy use
github.com/AI-sandbox/gnomix
Leads @HelgiHilmars @arvind0422 @BarrabesMiriam

Daniel Mas Montserrat retweeted

There is something bizarre in the resources and energy humanity is pouring into developing--without hesitation--what is akin to another species. As if, we had deep down this instinct, like a larva ecstatic to make its cocoon.
Daniel Mas Montserrat retweeted

We just presented iLTM, our Integrated Large Tabular Model with @marcal_cc at #KDD2026 in Jeju! 🇰🇷 @kdd_news
More info on iLTM on the thread below👇🏼


Excited to share our preprint on iLTM: an Integrated Large Tabular Model!
arxiv: arxiv.org/abs/2511.15941
No single technique consistently excels across all tabular tasks. iLTM addresses this by integrating distinct paradigms in a single architecture:
- Gradient Boosted Decision Trees (GBDT)-based embeddings
- Robust preprocessing with random feature projections
- A meta-trained hypernetwork
- Retrieval augmentation with Soft Nearest Neighbors
@d_bonet @marcal_cc @alexGioannidis
(1/N)

Daniel Mas Montserrat retweeted
4. Synthetic genomes
Conditioning was crucial for synthetic genomes. An unconditional VAE blurred population differences, while ancestry-specific models generated distributions much closer to real founder populations.
The synthetic genomes reproduced real biological structure: correlations between nearby variants decayed with genomic distance, and locus-specific linkage-disequilibrium peaks aligned with real data. Also entropy patterns reflected.

