

PhD Candidate in IR @ Sorbonne Université (@mlia_isir) Towards Language models that know what they know 🧠
Paris
Joined September 2022
- Tweets98
- Following220
- Followers88
- Likes191







Pinned Tweet
🐭MICE to Meet You: From Re-ranking Only to End-to-End Retrieval ⚡️
Our #EMNLP2026 paper showed that MICE pushes the Cross-Encoder Pareto frontier.
We take it a step further: turning theoretical pre-computation gains into an operational, end-to-end retrieval architecture 🧵

Victor Morand retweeted

idk man, when I see the open suite of rerankers of @tomaarsen (huggingface.co/blog/ettin-re…) followed by the extension to MICE from @_VictorMorand_ (arxiv.org/abs/2610.31932) or even the awesome SparseUp from @thibault_formal (linkup.so/blog/introducing-s…), I cannot help but being proud of having enabled that
Vamos open source

Victor Morand retweeted

SPARSEUP, the first paper from the @Linkup_platform Research team, is out on arXiv! w/ @Cosimo & Pierre
It’s the companion to our blogpost and goes deeper on:
• the ablations behind our simple training recipe, with a closer look at logit shift & fanout
• extended comparisons vs @LightOn’s DenseOn, LateOn & SlideOn (cc @antoine_chaffin @AmelieTabatta @raphaelsrty @paulomouraj)
More evidence that learned sparse retrieval holds up. More to come!
link: arxiv.org/abs/2611.09680

All our training recipes, xp configs, and MICE-P checkpoints are open. You can play with them in a minute through the sentence-transformer library !
🤗 huggingface.co/collections/x…
📄 arxiv.org/abs/2610.31932
👨💻 github.com/xpmir/mice

1
8
166
🙏 Thx to the dream team at @mlia_isir @zongyuxuan3 , @MathiasVast1 and my super-visors @JosianeMotheFr and @BenjaminPiwowa1
1
4
128
Special thanks to the 🐐 SoTa @LightOnIO (@antoine_chaffin @raphaelsrty @paulomouraj @AmelieTabatta) team for the data, Fast-Plaid, modernBERT.. and great discussions! Thx @tomaarsen for the ettin-reranker family and ST. Thx @jhuclsp for ettin, we build on shoulders of Giants !
1
7
154
Conclusion: While IVF-PQ may be too restrictive for the finer representations from MICE, it is already a solid baseline allowing to push the Pareto Frontier. Stay tuned, more to come for better compression and storage... 👀
1
2
186
Reconstruction quality: its not a complete free lunch 😇
MICE indeed requires more granular reps than LateOn, we used nbits=4 vs 2 for LateOn, making the PLAID store twice bigger (cf 1st Fig), and leaving more performance on the table: there's room to improve !

1
3
155
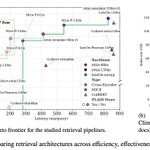
MICE-P moves the Pareto frontier
Trained from @tomaarsen ckpts, MICE matches full CE quality with only ~60% of their FLOPs.
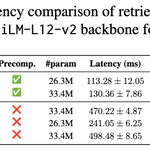
When pre-computing docs with PLAID, MICE-P hits a new Pareto region—achieving ColBERT-like latency while matching CE effectiveness on BEIR Decontaminated !
1
2
207
We distill from @mixedbreadai with MSE on ettin-reranker-v1 data: followong @tomaarsen's recipe.
This enables a decent comparison with the recent LateOn model by @LightOnIO. (We use 32-521 Q/D max len to ensure everyone sees the same stuff, even if it has up to 8K context len).
2
3
202
MICE-P introduces a 128-d bottleneck, making doc-precomputation possible with FastPLAID residual compression (thx @raphaelsrty 🙏)
Candidates are retrieved with SPLADEv3, decompressed and scored with MICE—preserving fine-grained cross-attn without full query-doc re-encoding!

1
4
259
Late-interaction models currently dominate scalable search thanks to pre-computed doc representations and multi-vector indexes like PLAID.
MaxSim however caps their expressiveness compared to Cross-Encoders.
Can we get CE expressiveness at late-interaction latency? Meet MICE-P !
1
5
306
On this note, I think now with the new trainsets we also lack "true OOD" benchmarks: stuff LLMs didn"t see during training. So that we'd assess the ability to represent stuff in context rather than concepts already embedded in LMs params. Any pointers ?
xitter.cf/bclavie/status/2113269…

On this note, if you've ever thought "Man, I wish I had BEIR and NanoBEIR, but considerably better and very discriminative of model quality!", you might also want to stay tuned.
i hear it might also be fully open
1
2
227
Victor Morand retweeted
Join us at Linkup HQ in Paris for an evening on information retrieval. Cool talks by @_VictorMorand_ , @cadurosar and myself! @Linkup_platform
luma.com/09879rqb

Victor Morand retweeted

We release SlideOn and mSlideOn at @LightOnIO today, two sota sparse retrievers, models designed by @paulomouraj and I.
Those models are really strong for first stage retrieval, you can add then a multi-vector model as a reranker and then a decision model 👇

We surfed the dense and late-interaction waves… now it's time to SlideOn sparse retrieval 🐕
🚀 Meet SlideOn and mSlideOn, fully open SOTA sparse retrievers at 174M and 339M parameters, trained by @LightOnIO R&D
Models:
huggingface.co/collections/l…
Blog: huggingface.co/blog/lightona…

Victor Morand retweeted

⌘C ⌘V: Introducing Copy-Paste Language Models!
CPLMs learn to copy tokens better, improving downstream accuracy, CoT, long-context performance, and memory-efficiency for RAG at <3% overhead
PS: they (partially) mitigate the LM head bottleneck
Paper: arxiv.org/abs/2610.19247

Victor Morand retweeted
Introducing SPARSEUP: the first model release from @Linkup_platform , and the missing sparse companion of DenseOn and LateOn.
Same backbone, same data, <150M, 56+ on BEIR-13. The model is open-source, use it!
Blog: linkup.so/blog/introducing-s…
Model: huggingface.co/Linkup-Platfo… (Apache 2.0)

Victor Morand retweeted
If all computer scientists do is create superhuman AI, we will have failed. Our goal must be to make *humans* smarter.
One of my 2026 teaching goals is to teach students to master the difficult art of using AI agents in ways the students get smarter, not dumber.
Lesson ideas?

Victor Morand retweeted

We released pplx-embed-v1 early this year, with Q2D benchmark to evaluate how embedding model performs for web search, not looking at nDCG@10, but Recall@1000.
Q2D-Web further scale it up 7 times. With 70k agentic reformulated queries and 190 million web corpus. We hope the benchmark becomes the modern “MS MARCO”

We're introducing Q2D-Web (Query2Doc-Web), a benchmark and public leaderboard for evaluating retrieval in agentic RAG systems.
Q2D-Web tests how embedding models perform on large-scale web search using agent-reformulated search queries.
Read more: perplexity.ai/hub/blog/q2d-w…

Victor Morand retweeted

We're introducing Q2D-Web (Query2Doc-Web), a benchmark and public leaderboard for evaluating retrieval in agentic RAG systems.
Q2D-Web tests how embedding models perform on large-scale web search using agent-reformulated search queries.
Read more: perplexity.ai/hub/blog/q2d-w…