

Post-doc @slavovlab Interests: Non-canonical protein sequences Protein degradation Single cell analysis
Boston, MA
Joined February 2020
- Tweets2K
- Following320
- Followers848
- Likes5.6K





Pinned Tweet
The big one is finally out!! In this paper, we set out to provide insight into the fundamental question;
How do the individual cells from complex tissues regulate their proteomes?
Brief summary of our findings 👇
biorxiv.org/content/10.1101/…

No reason to take a hard stance on this! Certain mechanisms cause regulation by translation/protein clearance in certain contexts. We aim to discover these mechanisms partly through measuring protein dynamics in single cells :)
biorxiv.org/content/10.1101/…


Andrew Leduc retweeted

Come join!

The Molecular Biosciences Department at Northwestern is excited to announce a faculty search for a Tenure-Track Assistant Professor position!
Learn more and apply at: molbiosci.northwestern.edu/f…
#BiologyJobs #AcademicJobs #FacultySearch #FacultyJobs

Pretty photo of our powerful droplet sample preparation method for multiplexed single cell proteomics!

The piece revisits the early days, our lab's initial work alongside other groups pioneering complementary approaches, together showing that mass-spec-based single-cell proteomics was feasible & promising. The proof-of-concept set the field in motion.
2/
nature.com/articles/d41586-0…

Andrew Leduc retweeted

The piece revisits the early days, our lab's initial work alongside other groups pioneering complementary approaches, together showing that mass-spec-based single-cell proteomics was feasible & promising. The proof-of-concept set the field in motion.
2/
nature.com/articles/d41586-0…
Andrew Leduc retweeted

Cells mitigate damage to DNA in surprising ways. Using a series of CRISPRi chemogenomics screens, we identified a PRDX1-dependent iron–damage axis in the DNA damage response.
Congratulations to Tom, Abe, Shaheen, Josep and all co-authors!
doi.org/10.1038/s41589-026-0…

The progress on pushing a new paradigm for multiplexing MS has been amazing. Shorter LC gradients are great but will run into fundamental limits. The creative multifaceted solutions the developed will open new doors for accessability of SCP / type of experiments that can be done
Accurately quantifying over 700K precursors in a single 9-plexDIA set of 20ng proteomes is a new milestone.
JMod achieves high quantitative accuracy over a 32-fold dynamic range of proteome spiked-in ratios across single-cell and bulk sample sizes.
1/
doi.org/10.1101/2025.05.22.6…

Andrew Leduc retweeted

Claude Science when it becomes a wrapper on existing tools


Many drugs work by binding to a specific target in the body and blocking or changing what it does. An important first step in the drug development process is designing a molecule that can bind tightly to its target. Traditionally, that's meant weeks or months of expert work per target, sifting through a large number of candidates to identify the few that work.
We wanted to test if Claude could successfully design novel protein binders from scratch (also called de novo design). With a protein design prompt written by a human expert, Claude autonomously designed protein binders against 14 out of 15 targets.
We then worked with Adaptyv Bio and Twist Bioscience, who independently built and tested the proteins Claude designed.
We updated our single cell in vivo metabolic labeling preprint partly thanks to constructive feedback from reviewers.
In the added analysis, we identified a gradient of proliferation within Basal epithelial cells corresponding to Krt13+ hillock cells.
biorxiv.org/content/10.1101/…


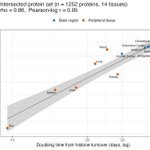
I made a mistake in the figure below and the result is actually a lot stronger (and makes much more sense, brain should clearly have slower turnover than the other tissues). Thanks @Yanshen73854711 for generating awesome data!


In this revision, we expanded our analysis across more tissue types & more model systems.
The conclusions held.
Proteomes are shaped by tissue type-specific protein degradation rates
▶️ This effect strongly depends on the cell growth rates.
🔗biorxiv.org/content/10.1101/…

Andrew Leduc retweeted

This is a very poor one line summary of the article by @DaphneKoller IMO.
The point is not just data volume. The right kind of data scaled in the right axis with the right experimental designs for well defined tasks + using the models to discover biology (not eval maxxing)

The data we need to understand human biology is about 1000x the quantity we've collected
Full piece from @insitro founder and CEO @DaphneKoller: a16z.news/p/drug-discovery-h…

Andrew Leduc retweeted
Very excited to announce ENCODE GRAMMAR (Genomic Regulatory Atlas of sequence Models, Motifs, Annotations & Rules): 3,865 experiment-specific deep learning model sets and sequence annotations for decoding human regulatory DNA. 1/

This is exactly right
The space of all possible hypotheses is still far greater than the space of all data collected. Moreover, the data has all been collected through the lens of our current paradigms for understanding biology (largely based on what we can measure easily). For these reasons, I think most verification is still hard, especially for interesting ideas. But maybe I’m wrong. Planning to explore that alternative possibility :).
Andrew Leduc retweeted

The space of all possible hypotheses is still far greater than the space of all data collected. Moreover, the data has all been collected through the lens of our current paradigms for understanding biology (largely based on what we can measure easily). For these reasons, I think most verification is still hard, especially for interesting ideas. But maybe I’m wrong. Planning to explore that alternative possibility :).
Excited to announce that in October I will be moving to San Francisco to start a postdoc in @LukeGilbertSF's lab at @arcinstitute with the goal of combining functional genomics with MS proteomics to explore the causal relationships governing protein-protein interactions.
Also thankful for the opportunities @slavovLab has given me. Looking forward to following and being involved with the amazing progress @ParallelSqTech is making advancing the throughput of single cell proteomics going forward and applying these new technologies to new frontiers.
"A clean organized lab with an inventory system that uses spread sheets to track reagents, if you can keep it."
- Ben Franklin if he was doing a PhD in molecular biology
Andrew Leduc retweeted

Does every enhancer work with every promoter?
With @jengreitz and @WJGreenleaf, we revisit this long-debated question and resolve an outstanding contradiction in the field.
A tour 🧵👇
biorxiv.org/content/10.64898…
Andrew Leduc retweeted
The preprint was available, and the peer review was rigorous and constructive even if very time consuming.
Thanks to @biorxivpreprint enabled by @cshperspectives and colleagues, the long peer review times do not delay sharing new results as much as before preprinting.
Andrew Leduc retweeted
Since the 1960s, the genetic code has been used to predict protein sequences from DNA and mRNA sequences. Our @Nature article demonstrates that these predictions miss thousands of protein sequences present in human tissues.
Across >1,000 human samples, we identified numerous abundant proteins whose amino acid sequences differ from those predicted by the genetic code.
These proteins are not rare translation byproducts. They accumulate to thousands of copies per cell. Some are more abundant than the proteins predicted by the genetic code from the same transcripts.
Their abundance reflects a combination of alternate RNA decoding mechanisms — including codon-anticodon mismatches, tRNA abundance, and RNA modifications — and selective stabilization of the resulting proteins. The last factor – protein stability – emerges as a major determinant of protein abundance across proteins, proteoforms and cell types: slavovlab.net/research.htm#P…
Alternate RNA decoding is pervasive across functional groups of proteins, healthy and diseased tissues. It affects proteins playing key roles in neurodegeneration, and some alternately decoded proteins show strong enrichment in tumors compared to their surrounding tissues.
This discovery has been a long and exhilarating journey with Shira Tsour and the @slavovLab team. It started in 2019 and proceeded through many challenges and thrilling highs. A journey that has opened new perspectives that we long to explore!
1/

We report many proteins not predicted by the genetic code.
They are stable & abundant O( 10³ ) copies / cell.
Generative mechanisms include codon-anticodon mismatches & RNA modifications.
Their abundance depends on codon frequency & protein stability.
biorxiv.org/content/10.1101/…
