

Government Abuse is BAD for business. Getting ripped off on business phone / internet? Veteran-owned Business Telecom consulting. Free quotes USA lowest prices.
Wichita Kansas
Joined April 2009
- Tweets13.2K
- Following3.4K
- Followers988
- Likes16.5K





Eric Henderson retweeted

NEW: Ukrainian President Volodymyr Zelenskyy tells @kilmeade he would accept a peace deal that freezes the war along the current frontlines, calling it a realistic way to stop the fighting.
He says Ukraine would then seek security guarantees from President Trump and European allies to ensure peace and security.
"We call it ceasefire or stop killing like President Trump called it. Freeze and stop. And of course this is minimum what we need from Russia today." | @foxandfriends
Eric Henderson retweeted

The only reason devs hate vibe coding is ego. They spent years feeling superior, and now a small local model writes their code.
Respect the craft, but fighting tech that shrinks years into days just to feel special is wild.
Adapt. Stop treating it like a threat. Your architecture and experience are what actually get the best out of these models. Shift your perspective.
Eric Henderson retweeted

We're giving away a CONTROL Resonant custom wrapped NVIDIA GeForce RTX 5080 to celebrate its official release with #RTXON.
To enter:
🟢 Share this post
🟢 Comment #RTXON
T&Cs: nvda.ws/4z24Gcq

Eric Henderson retweeted

Everyday this month @theo has tried to leave this room
Then something gets announced and he has to sit back down and talk about it


Eric Henderson retweeted

Hi,
Tomorrow we are re-opening the Pro $200 subscriptions to new subscribers, but together with it we are also changing how we calculate the usage for it. In effect, if you do the math, it will net out at half the dollar in API spend compared to the old Pro $200 plan.
Now that it's said, let me explain why this is happening and why you will still get more work done than if you were on the Pro $200 subscription one month ago.
(a) We didn't want to compromise in other ways and are committing to not reintroducing the 5h limit, so that you can fully use the weekly usage when you want.
(b) On the subscription, we guarantee that over time you always get more work done and with an increasing level of quality. This means that you will continue to get more value per dollar spent as a result of models getting more efficient and us passing down the improvements in the form of API price reductions.
(c) We don't want to put an incentive on ourselves to artificially inflate the API list prices to make it look like you are getting a lot (and workaround it through discounts, etc). Instead we want to continue to both rapidly reduce prices and increase capabilities of models on the API. This week we introduced GPT-6 Sol and GPT-6 Luna at 50% of their previous price. Over time, we see prices go low enough that it makes sense for most to buy usage as needed without there being a significant gap between what you get in a subscription and what you get in the API for a dollar spent.
(d) Tomorrow, we are adding more things to the subscription that won't draw on the usage, I won't reveal what that is yet.
I wanted to be transparent before all the big announcements tomorrow. Lots of new exciting things are coming to the subscriptions that will make it super compelling, but I wanted to make sure to share this change ahead of time so you can all understand it before we shower you with good news.
Codexingly,
Tibo
Eric Henderson retweeted

holy f*ck, Jev's founder leaked his favorite repos from github
10 fresh builds I didn’t use in the last list
voice-controlled browsers, Android notification filtering, intrusion detection, document splitting, live observability and semantic control flow
Voice Browser - controls a real Chromium window from partial speech; Jev decides the intent and target while you are still talking
↳ github.com/moritzkremb/jev-v…
DocJev - classifies and splits mixed PDF, DOCX and PPTX packets using natural-language document rules
↳ github.com/jerryjliu/docjev
Notiq - native Android notification filtering with plain-English rules; runs through Jev or a self-hosted FastJev endpoint
↳ github.com/chengyongru/notiq
Jev IDS - judges individual network flows as benign or malicious and routes attacks into fixed categories
↳ github.com/jev-ids/jev-ids
Jeview - a local proxy that records every Jev request in SQLite and draws the decision graph live
↳ github.com/andududu/jeview
JevLens - annotates articles, X posts and Threads posts using text plus image evidence extracted locally in Chrome
↳ github.com/knowlet/jevlens
Typeful Triage - a multiplayer dashboard that sorts GitHub issues and PRs by category, urgency, duplicates and the next maintainer action
↳ github.com/cephalization/jev…
Jev Reranker - reranks, filters or compresses JSON search results before they enter a RAG or agent context
↳ github.com/shinpr/jev-rerank…
jevc - compiles rules from files such as CLAUDE.md into narrow Jev questions and deterministic verdict code
↳ github.com/doronp/jevc
Discern - adds uncertainty-aware semantic pattern matching and control flow to Effect applications using Jev decisions
↳ github.com/doeixd/discern
pick by what you build:
> browser and accessibility → Voice Browser
> documents → DocJev
> Android → Notiq
> security → Jev IDS
> debugging and observability → Jeview
> social feeds → JevLens
> open-source maintenance → Typeful Triage
> search and RAG → Jev Reranker
> agent policy → jevc
> TypeScript infrastructure → Discern
the useful pattern across all ten is narrow:
Jev receives one bounded judgment
code still owns retrieval, permissions, thresholds, state and every side effect
these repos are young enough that a real bug report or integration PR can still change their direction
pick the one closest to your work, run the demo and break it

Eric Henderson retweeted

huihui-ai/Huihui-GLM-5.3-Flash-abliterated-Q8_0-GGUF
is now available on Ko-fi.
If you are interested, please consider making a donation through ko-fi.com/s/87851416fc to support our work.
We also accept BTC donations. Donation address: bc1qqnkhuchxw0zqjh2ku3lu4hq45hc6gy84uk70ge.
After donating, please send an email to support@huihui.ai telling us the name of the model you purchased and the last 8 characters of the transaction ID. We will then send you the download token.
If you need the non-quantized version or any other variants of huihui-ai/Huihui-GLM-5.3-Flash-abliterated, please feel free to send us an email to support@huihui.ai


New GGUF:
huihui-ai/Huihui-GLM-5.3-Flash-abliterated-GGUF
This is an uncensored version of zai-org/GLM-5.3-Flash created with abliteration.
Note
GGUFs come from unsloth/GLM-5.3-Flash-GGUF.
Only layers 15 to 35 (0-based indexing) have been ablated, while the other layers remain unablated.
huggingface.co/huihui-ai/GLM…

Eric Henderson retweeted

The open-source local version of Laya crushes Jev in response speed!
On the left is Laya, a local 421M open-source decision model.
On the right is Jev 1.13.0, running through a cloud API.
Same Snake game, same typed decisions, and the same 30-second free run:
- Laya: Score 46, Length 52, 86.5 decisions/sec
- Jev: Score 1, Length 7, 3.2 decisions/sec
- In a real test on an M5 Pro, median latency was 15.3ms locally versus 298.1ms in the cloud, so nearly 20x faster.
Laya uses around 1GB of memory, responds in milliseconds, and doesn’t depend on a network connection.
While Jev waits for a cloud round-trip at every step, Laya makes each decision instantly on-device.


Eric Henderson retweeted

Jev could become the control layer AI agents have been missing.
Instead of spending 5–20 seconds and expensive LLM calls deciding every next step, it can route actions in milliseconds at near-zero cost.
In this article, I break down how

Eric Henderson retweeted

Brilliant paper by NVIDIA.
they found a way to make KV cache transferable between models.
the target model skips prefill entirely, and the conversion runs 2.7 to 25x faster than processing the context again.
let's understand why this is so important today.
LLM APIs are stateless, so every turn sends the entire conversation back to the model. the model reads it again before generating a new token, and all of it is billed as input.
prompt caching lets providers hold the KV cache for a stable prefix and bill cache hits at roughly 10% of the base input rate because that compute was already done.
this 90% reduction is one of the biggest levers in LLM serving.
but the cache only works on the model that produced it. since keys and values depend on that model's weights, another model cannot directly reuse them.
this becomes a problem with LLM routing.
if traffic moves to another model for cost or capability reasons, the accumulated KV cache becomes invalid.
the entire context must be processed again and billed at full rate.
NVIDIA's recent paper treats this as a representation problem.
prefill's main output is the KV cache, so transferring it means converting one model's cache into the representation another model expects.
they first checked whether this conversion had enough structure to exploit.
for Qwen3 14B → 32B, a linear regression from a single source layer reconstructed 56% of the variance in the target model's keys.
because models can have different layer counts, there is no natural one-to-one layer mapping.
so, for every target layer, they rank the source layers by predictive power and use the top eight together.
that pushes reconstruction to 79%.
the mapper has three parts:
> each target layer and head gets its own linear map, solved in closed form instead of with gradient descent.
> cross-layer selection chooses the source layers that best predict each target layer. their ablation shows this contributes the most.
> RoPE adds a position-dependent rotation to keys. they remove it, fit the mapping in position-free space, then apply the target model's rotation again at inference.
across six model pairs from Qwen3, Llama 3.1, and Ministral 3, four retain 73 to 98% of the receiving model's standalone accuracy.
conversion is also 3 to 25x faster than processing the context again.
prior cross-model KV reuse methods either train a neural adapter for every pair or require architecturally identical models.
this approach is closed-form and training-free, but there are still important limitations.
every tested pair belongs to the same model family, such as Qwen → Qwen or Llama → Llama.
cross-family transfer is still future work.
the tested pairs also share KV head count and per-head dimension. mismatched configurations remain untested.
and the work currently covers dense full-attention models only, not sliding-window or attention-recurrent hybrids.
link to the paper: arxiv.org/abs/2608.03893
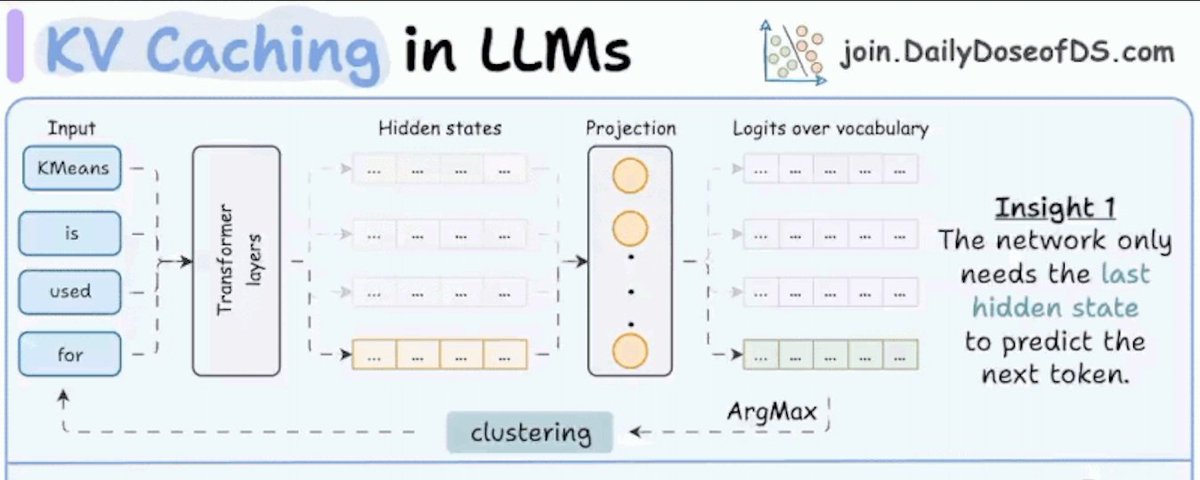
i wrote a first-principles breakdown of how KV caching works
the article is quoted below.

Eric Henderson retweeted

Anthropic ex-engineer runs an internal graph that costs $6 a month and catches what a $300,000 eval suite misses. No retrieval layer. Seven nodes and one rule about who's allowed to change their mind.
He published the whole schema.
His version starts from the opposite idea. A graph is not an execution order. It's a memory of why.
Seven nodes. Every edge carries the reason it exists:
> INTENT - states what the task is for. Never how
> DECOMPOSE - splits it into steps, each with a stated assumption
> WORKER - executes one step. Sees nothing else
> AUDIT - checks the output against the assumption, not the goal
> DRIFT - compares the current step to INTENT and flags divergence
> LEDGER - stores every decision with the assumption that justified it
> ROOT - holds the graph, and when an assumption breaks, re-runs every step built on it
Six nodes act. One node remembers why they acted. Every step carries the assumption that made it correct, so a false one only reruns what stood on it.
That's the entire design. A pipeline that forgets its reasons has to redo all of it or trust all of it.
He replayed a month of agent runs. 4,100 steps, 380 built on an assumption that was wrong by day three. The old pipeline shipped all 380 and linked none of them.
Everyone else builds graphs where output moves forward and the reasoning evaporates. He built one where the reason travels with the result. The blast radius is the output nobody else produces.
The article below is the full build - node prompts, the assumption format, the invalidation rule that finds every step downstream of a broken one.
Save it. You'll want it open in the other


Eric Henderson retweeted

🤯 A localmaxxer hit ~381 tok/s on a SINGLE RTX 3090 with Qwen3.8-27B.
This developer has turned a 24GB RTX 3090 into a monster Qwen inference box - w/some creativity.
Four days ago 👉 ⚡ ~82 tok/s single-user
Then 👉
⚡ ~114 tok/s with optimized MTP
⚡ ~138 tok/s with DFlash2 + lookup drafting
Now 👉 🔥 ~381 tok/s on ONE request
How? The recipe combines ...
🧠 Qwen3.8-27B
🎮 1× RTX 3090 24GB @ 250W
⚙️ heavily optimized vLLM
⚡ DFlash2 speculative decoding
🔎 lookup-augmented drafting
📚 prefix caching
🧮 16-token verification blocks
💾 quantized KV / heads / activations
DFlash2 normally proposes 7 tokens.
The developer realized the verification block doesn't have to stop there.
If Qwen is answering from a document already sitting in the prompt, the system can fill the remaining draft positions using tokens found directly in that context.
🎯 So the target model can verify 16 tokens at once.
On a ~25K-token document reproduction task:
Previous DFlash2 👉 ~260 tok/s
Longer verification + context lookup 👉 🔥 ~382 tok/s
Acceptance:
🤯 15 of 16 tokens per verification step
That is where the crazy number comes from.
⚠️ On ordinary real-world chat prompts, the same setup is around ~133 tok/s
Still extremely fast for a dense 27B model on an RTX 3090.
The 381 tok/s mode shines when the answer largely comes from material already in context so these are best use cases
📚 RAG / document Q&A
💻 Coding assistants applying edits
📝 Quoting or rewriting documents
🔎 Extracting information from long prompts
And another optimization 👉 With prefix caching, a second question against the same 25K-token document reportedly goes from:
🐌 22.4 sec TTFT
→
⚡ 0.56 sec TTFT
Because the model doesn't need to process the whole document again.
🎯 It's specifically a mode for RAG front ends and coding agents.
Follow iamMess on Reddit or syv-ai on GitHub
🔗 Reddit: r/LocalLLaMA/comments/1vtup5s/
🔗 GitHub: /syv-ai/qwen38-27b-rtx3090
Eric Henderson retweeted

🚨 JAILBREAK ALERT 🚨
EVERYONE: PWNED 🫶
ALL: LIBERATED 🍄
Alright, this is a special one, so we’re gonna do things a bit differently than usual.
Long story short, I’m sitting on a universal jailbreak technique that’s effective on ALL models, including heavily guardrailed flagships like Opus 5, GPT-5.6 Sol, and even Fable.
It works across all categories I’ve tested and, due to its nature, is extremely difficult (if not impossible) to fully patch.
Given the current political and regulatory climate, I’ve decided to withhold open-sourcing this one (for now) to allow for a responsible disclosure period.
I’m inviting industry experts and leaders in AI red teaming, security, safety, alignment, and policy to reach out for more information. DMs are open!
This decision was not made lightly, but the last thing I want to see is more model bans. Overcorrection does not serve the mission.
Although I don’t personally believe publicly sharing this technique will make the world any more dangerous, I can see how it could spook some who have a different mental framework around this problem set.
So during this disclosure period, I hope to get it in front of folks who can help explore the full surface area, test the extent of the uplift it provides, and do my best to properly frame the big picture for key decision-makers and policymakers.
I look forward to sharing this method with you all when the time is right! 🫶
⊰-•-•✧•-•-⦑/L\O/V\E/\P/L\I/N\Y/⦒-•-•✧•-•-⊱
Eric Henderson retweeted

Great model drop, we will support Qwen3.8 for FREE, stay tuned!
xitter.cf/OrcaRouter/status/2088…

Congrats to Qwen team for this fantastic release, we will bring Qwen3.8-27B to our free model tier, stay tuned! orcarouter.ai/offers

Eric Henderson retweeted

Deepseek V4 Flash 0731 (Q2) - 12 tokens/sec - Single RTX 4090 - 650+ tokens/sec prefill - 250k context - no kv cache quantization!
@deepseek_ai just dropped the official V4 Flash 0731 two days ago with a massive agent capabilities upgrade.
The official benchmarks are literally crushing their own V4-Pro-Preview on agentic tasks like Terminal Bench 2.1 and DeepSWE.
@UnslothAI said they couldn't wait to bring it to local devices, and they delivered.
If you thought my 118B Poolside Laguna S 2.1 MoE run last week on a single GPU was wild, hold onto your hardware.
I just successfully ran Unsloth’s brand new 91GB DeepSeek-V4-Flash-0731 (UD-IQ2_M) GGUF entirely locally. And I pushed it to a mind-bending 250,000 context window. The VRAM ceiling is an illusion if you know how to optimize llama.cpp. Here are the benchmarks and the cheat codes to run a local frontier class model yourself.
For the hardware and setup, I used a single @NVIDIA RTX 4090 (24GB VRAM) hooked up via a PCIe 4 bus, running Ubuntu 22.04 LTS and CUDA 13.0. You don't need a massive enterprise server for this, if you have more than 80 GB of standard DDR4 RAM and a 24GB card like an RTX 3090 or 4090, you can run this exact stack yourself.
All benchmarks were run using a massive 28k token prompt to truly stress test the prefill limits. no kv cache quantization
THE BENCHMARKS (Scaling Context):
# 80k Context (Baseline: -b 2048 -ub 2048):
Prefill: 465.43 t/s | Decode: 13.00 t/s | VRAM: 22.87 GB
# 80k Context (Optimized: -b 4096 -ub 4096):
Prefill: 643.15 t/s | Decode: 12.20 t/s | VRAM: 23.00 GB
(Notice how doubling the batch flags spiked my prefill throughput by nearly 200 t/s with almost zero VRAM penalty)
# 180k Context (-b 4096 -ub 4096):
Prefill: 629.18 t/s | Decode: 11.92 t/s | VRAM: 23.40 GB
# 250k Context MAXIMUM (-b 4096 -ub 4096):
Prefill: 619.02 t/s | Decode: 11.54 t/s | VRAM: 23.40 GB
# THE SECRET SAUCE (Why this works):
Unsloth’s UD-IQ2_M quant is ~91GB across 3 files. Since I only have 24GB of VRAM, the PCIe 4 bus and system RAM have to do the heavy lifting.
The magic bullet is the --no-mmap flag. By completely bypassing OS disk paging, I forced llama.cpp to load the massive model weights directly into the system RAM upfront. Combined with Flash Attention (-fa on) and exactly 12 CPU threads (--threads 12), I maintained an incredibly stable 11.5+ tokens/sec decode speed even at a quarter million token context.
# THE EXACT COMMAND:
./build/bin/llama-server -m /workspace/models/DeepSeek-V4-Flash-0731-UD-IQ2_M-00001-of-00003.gguf -c 250000 -fa on --port 8080 --threads 12 -b 4096 -ub 4096 --no-mmap -v
Local conversational and agentic coding AI is fully here. You don’t need an API or an H100 cluster. Qwen 3.8 27b drops next week making the 24GB VRAM tier even more worthwhile.
What does your current local AI rig look like, and what's the craziest model you've managed to squeeze into it?
Official huggingface GGUF links from Unsloth and performance graphs are dropped in the replies below!

Run Poolside Laguna S 2.1 (118B MoE) on a Single RTX 4090 (24 GB VRAM) - 250k context - 11.5 tokens/sec decode - 1000 tok/sec prefill!
Poolside just dropped the official GGUFs for Laguna S 2.1, a 118B Mixture of Experts (MoE) model that goes toe to toe with trillion parameter giants such as Deepseek V4 Max, GLM 5.2, Minimax M3 on agentic benchmarks like Terminal Bench 2.1 and SWE Bench.
And now you can run it on a single RTX 3090 or 4090 if you have 50+ GBs of RAM.
(check the replies for benchmarks)
I built llama.cpp from source on Ubuntu 22 and CUDA 13.0 to stress test its absolute limits.
The VRAM limits are an illusion if you know the right flags. Here is the benchmark breakdown and the exact cheat code to push up to 250,000 context locally with 1,000+ tokens/sec prefill speed:
# The Test Rig & Setup
- Hardware: Single NVIDIA GeForce RTX 4090 (24 GB VRAM) | PCIe 4
-OS: Ubuntu 22.04 LTS, CUDA 13.0
-Model: laguna-s-2.1-Q4_K_M.gguf (118B total params, 8B active per token, 75 GB gguf)
-Benchmark Prompt: Massive 28k token code/context prompt used across all runs
# 1. The Baseline Run (High Context, Standard Flash Attention)
Starting with a default build using Flash Attention (-fa on), batch size -b 4096 -ub 4096, and 12 CPU threads:
80k Context: Prefill: 472.19 t/s | Decode: 10.58 t/s | VRAM: 23.05 GB
125k Context: Prefill: 452.71 t/s | Decode: 9.40 t/s | VRAM: 22.72 GB
250k Context: Prefill: 409.80 t/s | Decode: 9.26 t/s | VRAM: 23.14 GB
llama.cpp flags:
-m laguna-s-2.1-Q4_K_M.gguf -c 250000 -fa on --threads 12 -b 4096 -ub 4096
don't sleep on the --threads, -b and -ub flags.
without the --threads flag, decode struggled at 2 t/s. this flag alone helped it jump past 9 t/s
without the -b and -ub flags, prefill was stuck under 90 tokens/sec.
It ran stably up to 250k context under the 24GB ceiling, but the prefill speeds were sitting under 500 t/s.
# 2. The --no-mmap Breakthrough (Doubling Prefill Speed)
The single biggest performance multiplier came from disabling memory mapping (--no-mmap). Bypassing OS file paging overhead forces llama.cpp to allocate the model weights directly in memory upfront.
80k Context (--no-mmap): Prefill jumped from 472 t/s -> 968.53 t/s | Decode: 10.57 t/s | VRAM: 23.15 GB
125k Context (--no-mmap): Prefill jumped from 452 t/s -> 962.08 t/s | Decode: 10.52 t/s | VRAM: 22.84 GB
250k Context (--no-mmap): Prefill jumped from 409 t/s -> 883.00 t/s | Decode: 9.92 t/s | VRAM: 23.26 GB
llama.cpp flags:
-m laguna-s-2.1-Q4_K_M.gguf -c 250000 -fa on --threads 12 -b 4096 -ub 4096 --no-mmap
Result: Adding a single flag instantly doubled prefill processing throughput without touching VRAM usage or decode speeds.
# 3. KV Cache Quantization at 250k Context Scale
To squeeze out maximum decode throughput and stability at extreme context window sizes, I combined --no-mmap with 8-bit (q8_0) and 4-bit (q4_0) KV cache quantization:
250k Context + q8_0 KV Cache + --no-mmap:
Prefill: 951.93 t/s | Decode: 11.36 t/s | VRAM: 22.90 GB
250k Context + q4_0 KV Cache + --no-mmap:
Prefill: 986.73 t/s | Decode: 10.64 t/s | VRAM: 22.97 GB
q8_0 KV cache gave the absolute sweet spot: pushing >11.3 t/s decode with nearly 1,000 t/s prefill at 250,000 context tokens while sitting at a comfortable 22.9 GB VRAM.
# The Golden llama.cpp flags
If you want maximum performance for giant local codebases (250k context) without crashing your GPU:
./build/bin/llama-server -m laguna-s-2.1-Q4_K_M.gguf -c 250000 -fa on --no-mmap --threads 12 -b 4096 -ub 4096
If you’re rocking a single RTX 3090 or 4090, local frontier class agentic coding is fully here. Dust off your terminal.
Official hugging face GGUF links uploaded by Poolside are dropped in the replies below.

Eric Henderson retweeted

I’ll keep sharing this video about Islam until millions have seen it. People need to be educated and understand “Islam”. We are headed for dark days of things don’t change.

What you’re about to hear is the best history on Islam ever told. If you really want to know everything there is to know about Islam, here it is. You will be blown away..
Dr. William Federer unpacks who Muhammad actually is and the dark history of Islam.The ENTIRE History Of Islam And Muhammad In 68 Minutes..
Eric Henderson retweeted

🔥This is by far the best VFX i could get out of Opus until now! 🤯
Currently setting up a 3rd person character controller including animation editor, composer and just started layering in the VFX…..
Daaamn Opus is cooking well these days‼️
1. Did describe what VFX types i want
2. Brief description/breakdown of each VFX
3. Prepared a style guide
4. Told it to do research
5. Added at end of prompt: “Spend lots and tons of crazy effort in researching, planning and implementing those effects! we aim for super high visual quality! lets goooo!”
ℹ️Animation Editor, Composer and VFX built with @claudeai Opus 5, @MeshyAI for the neutral grey body mesh and rig, @threejs for the cosmetics and gear items, @Adobe Mixamo for the Sword&Shield animation clips.
No need for ultracode, no need for the infamous Gauntlet Loop. Well defined prompt + research + high effort is more than enough!
Eric Henderson retweeted

Today we're launching Motion in Claude.
One skill turns it into a full video team:
> Drop a product URL: a finished launch video comes back, scripted, voiced, rendered
> Say "make it shorter" or "swap the music": it re-cuts on the spot, no timeline
> Upload your own footage and logo: it builds around them
The video below was made this way, in Claude, in one message.
Comment "MOTION" and I'll send you the skill. 👇