Steven Walton retweeted
Mind boggling to me that I can make a thing faster and there's always people that ask "but why?" What kind of mentality is that? The pursuit of excellence does not need justification. Also, I find in so many cases, we can't know the impact of an improvement until we do it.
For example, one I've talked about before: Ghostty's high IO throughput has enabled terminal program (emulator and TUI) fuzzing at a speed thats incomparably fast to prior solutions. This has resulted in upstream patches to resolve issues in popular projects like btop, tmux, and more.
Speed enabled that anecdotally example that lifted the tides of adjacent communities that don't rely on Ghostty technology at all. I didn't predict this.
Make things better because they can be better and let the results naturally play out.
Who knew @SouthPark was so prophetic?
youtube.com/watch?v=sDf_Tgzrā¦
If you want to listen to the songs it made...
flowmusic.app/session/90d9d4ā¦
This is a farce. To claim "more guardrails" is frankly unbelievable. Why would @AnthropicAI be called a supply chain risk but then @OpenAI gets a contract with stricter conditions.
If guidelines are stricter then what's the claim? DOD killing your competition for you?
Yesterday we reached an agreement with the Department of War for deploying advanced AI systems in classified environments, which we requested they make available to all AI companies.
We think our deployment has more guardrails than any previous agreement for classified AI deployments, including Anthropic's. Here's why: openai.com/index/our-agreemeā¦
But we can just read both their statements. Compare these two.
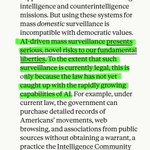
@AnthropicAI: no domestic mass surveillance, even if it's legal
@OpenAI: as long as it's legal ĀÆ\_(ć)_/ĀÆ
That's the big difference.
anthropic.com/news/statementā¦
openai.com/index/our-agreemeā¦
Now I wish it was "mass surveillance" rather than "mass *domestic* surveillance" but it's clear that @AnthropicAI is aligning to /their/ *moralities* while @OpenAI is aligning to *legality*. These are not the same and the latter is blatantly a lower guardrail.
It's insulting
Steven Walton retweeted
well someone has been preaching this at us for like 6+ years
glad we are past the 'feel the agi' phase and back to building toward human-level intelligence
āThe thing that happened with AGI and pretraining is that in some sense they overshot the target.
You will realize that a human being is not an AGI. Because a human being lacks a huge amount of knowledge. Instead, we rely on continual learning.
If I produce a super intelligent 15 -year -old, they don't know very much at all. A great student, very eager. [You can say,] āYou go and be a programmer. You go and be a doctor. Go and learn.ā
So you could imagine that the deployment itself will involve some kind of a learning trial and error period. It's a process as opposed to, you drop the finished thing.ā
@ilyasut
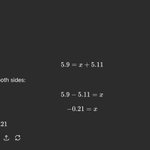
Very impressive, but also wrong.
There's 2 mistakes in the first physics problem on the LHS.
It did the derivative wrong, but fixed its mistake with another mistake! (better explanation in alt text)
ChatGPT looked at the end, not the answer.

ALT Here's the full correct solution. Nano banana's mistake was in the time derivative. It added an extra -i. Interestingly, it looks like the mistake is like it is trying to do some chain rule within the exponent. Probably since it first converted the exponents to e^{ -i ( px + Et) / \bar{h} }. Perhaps it hallucinated the equation e^{ -i ( px + iEt) / \bar{h} } instead

ALT Here I'm using Nano's answer and we see that it incorrectly multiplies the i's. Remember i*i = -1 It *should* have gotten the answer iE \Psi, which would have been incorrect, yet it fixed its mistake! To write it another way we can write like -1 * i * i * i | since -i = i * -1 = -1 * (i * i) * i | collect = -1 * -1 * i = i
It is also a good example of why researchers are arguing about "understanding".
Does it understand?
- It got the right answer, so it must!
- The steps were wrong, so it actually doesn't!
Or maybe something more complex is going on...
We still don't know
Unknown to most people, there isn't just one physics.
The history of science itself gives a positive answer to this question. Which is why many are wary of world models through scaling alone. Its known to be not enough.
In fact, that's one of the main criticisms of ideas like String Theory. There are untestable hypotheses that make it indistinguishable from a different physics.
With physics we care about accurate causal explanations. But in AI, we should still be very concerned with this
even if we only care about some arbitrary accuracy. (See @keyonV's work)
It's essential if you want safe machines.
It's essential if you want it to "just work."
Physicists turned to math because testing isn't enough. There's no free lunch
Got the #CVPR outstanding reviewer award!
There's a lot of noise in the reviewing process, so write the review you wish you received. Finding flaws is easy, but review is about the progress and making the work the best it can be.
Remember, we're all on the same team.
If you're at #CVPR, stop by Hall D from 10-11. I have two posters (166 & 167) I'm presenting with the eLVM Workshop.
One on mitigating the downsides of restricted attention mechanisms, creating efficient high performance GANs. The second on the distillation of Normalizing Flows.