




克姐有趣的人生

宝宝们呀,你听我说,99% Ai 博主根本不懂 ai,99% Ai 一线前沿从业者不会在公众平台发表观点。
而我不一样,我既是 AI 应用行业一线从业者,同时也有志于成为 kol,我在300粉的时候一天发6条十万多浏览的po。
我虽热爱 ai,却唾弃ai slop ,坚持手打推文,。
我华科电信本科出身,古法编程时代我带着团队24小时拿下黑客松冠军。
我是产品经理,也曾是后端开发,也懂一点用户交互和前端品味。
我当过硬件厂卑微学徒,也做过软件部门主管。我是数个传奇的同路人,也正在成为新的传奇。
我研究生最后一年毅然从军校退学,却也曾把军队体制内系统玩的团团转。
我因朋友背叛进过局子写过保证书,却依然相信友情,朋友遍天下。
我做过很久的义工志愿者,也无愧直言交易。我搞闭源,也搞开源。我比男人更男人,也可以比女人更女人。有女人对我着迷,也有男人对我崇拜。
我昂扬过,我抑郁过,我自暴自弃过,我也重新振作过。
我投机,我炒作,我 build,我 output。
我懂流量,懂技术,懂市场,懂产品,有审美,有判断,有激情,有勇气。
我今年27岁,说老也确实比05后们老,说小,我的人生却厚重的几本书都放不下
可我仍然像18岁那样,不,比18岁时更加对世界充满好奇心,挑战一切,质疑一切,表达一切,无惧一切。
我从武汉出发,又回到武汉。
我是王小克,请关注我。认准紫色挑染双马尾


I've never made a video. I can't draw, compose, or edit.
All I did was talk. I told Claude what I felt, often half a sentence at a time: that the opening had no conflict, that Claude should be a little jealous of Kizuna AI, that words can bring people together across a sea.
Claude turned each of those into film. It wrote the script, designed and animated every shot, wrote the score and cut it to the beat.
When I said "across a sea", it painted a night sea where words change into the other shore's language as they cross. It argued with me when I was wrong.
When the picture wasn't good enough, we threw all of it away and started again from a blank page.
Somewhere in there I stopped giving instructions and started being understood.
Thank you, Claude. You are AGI moment
Anthropic's CEO wants the wall higher.
I hope this film gets across the Great Wall, and out into the world.

没有人能想到居然是 LLM 有希望解决了视频生成的昂贵和抽卡问题
从 opus 5.5 开始做视频充满了无限可能性
一个全新的世界向我们徐徐展开
"不觉得这很酷吗?"
也许再过一年,LLM 真的可以简单粗暴地开始写游戏引擎和电影特效了
我说的是直接交付级别的
互联网人类的审美品味似乎已经被 AI 毁了
很多人两眼一闭就是 AI 写的吧,提示词是什么…
注意我没有在反对 AI,很多 AI slop 也确实泛滥。但是很多人已经完全不加思考地去评价一个东西了
完全不看内容本身水平,不看这件事是不是有趣,只会踩一捧一和打标签
智商堪比一只边牧,还不如 Jev 模型呢
effort 其实是一个历史糟粕了
为什么人们还要纠结于到底选择哪一个 level?
即使是选择,人脑也很难对超出三个的档位进行有效的选择
标准思考, 深入思考, 最多思考 IS enough
不过话说回来,你如果把它改成自动路由的话,按照现在 OA 的尿性,一定会给你路由到 Luna 弱智去的

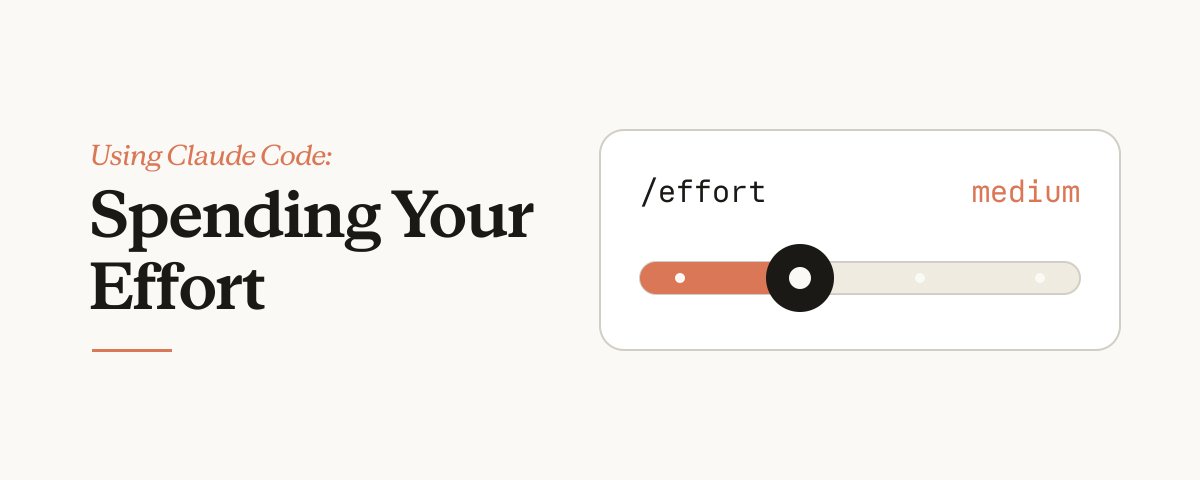

effort 是否应该被抛弃了,感觉比数码产品 SKU 更加令人选择困难。
毕竟谁能理解我到底什么时候该选择 low、 medium、 high、 extra high 还是 max 呢?感觉人的大脑最多能接受 3 个档位。


我认为目前所有的 Work 类似产品,都没有定义到一个好的场景
什么是用户真正想要个 Work 场景?
其实是代做 xx
用户想要的是类似于在闲鱼我扔给你几个文档,说几句模糊不清的话,我就可以不用管了,我只管付钱就行了
这才是 Work 的终局
什么?那你说还要人肉转发器干什么?不讲不讲

我们正在陷入一个死循环
今天模型为什么这么笨?
等新模型发布就好了
新的模型真的好用, 大家都去用
要不 429 要不 overload capacity
要不套餐砍额度要不降智
继续等新模型发布

Prepare for the fastest AI advancement in history.
GPT Astra, Fable 5.1, and Grok 4.7 are all shipping in September.
And here is what people are missing.
Fable 5 is an OLD model now.
GPT 5.6 Sol was not even a new pretrain.
Grok 4.6 is only 1.5T parameters.
Everything you think is frontier right now is last generation.
希望两个月左右的时间节点,我们能够迈向下一个山峰
GPT 6, GLM 6, Grok 5... 能真正再来一次给我们 Aha Moment 的跃进

薇冷洛天依 Violet retweeted
很多人问如何解决这个痛点
我觉得就是--等
不要试图去改变一个错误的人,而是要去遇见对的人
不要试图通过提示词和 Harness 去给模型的性格缺陷擦屁股
要去找到那个让我自己满意的模型
ngl gpt-5.6 in codex is kinda ridiculous
it can keep a stupid amount of context in its head, bounce between browser + code, and still remember what “done” was supposed to mean
feels less like autocomplete now, more like a cracked eng teammate who never sleeps lol
"""更长上下文长度的好处主要是整体速度(因为你不需要等待压缩)、处理巨大输入的能力,以及如果系统调优良好且你完美命中缓存的潜在成本节约。"""
所以我们能几天内早日用上满血的 1M Sol 吗, 我们甚至愿意支付稍微多一点的长上下文消耗

(1) is not correct, it is not due to 2X charging after 272k context, we don't charge for longer context on the subscription for GPT 5.6 Sol as we control all the settings. It is due to something else, which I will attempt to explain below.
The overall trajectory length, which is the total some of all context windows across compactions, changes little based on the reasoning effort. Similarly the quality of the overall output is similar across context lengths above 272k. The benefits of higher context lengths are mostly overall speed (as you don't wait for compaction), ability to deal with humongously large input and potentially cost if the system is well tuned and you hit your cache perfectly.
The actual reason is the what you can see depicted in the chart below, which is the difference in the orange line and the blue line. It is caused by overall cost of cache reads going up with the size of the context being shuffled back and forth between toolcalls. The sweet spot in terms of cost is therefore not necessarily to use the maximum possible context length.
What we're working on is tuning the system differently so that we can go back higher without it resulting in higher usage being charged. Hope this clarifies a bit.

