



Pinned Tweet
Excited to share our latest breakthrough! We trained sparse autoencoders to decompose intermediate results of SDXL Turbo's forward pass. These autoencoders learn highly interpretable features that can be used to manipulate the image generation process.
arxiv.org/abs/2410.22366
Viacheslav Surkov retweeted

I am very excited to share that our paper, "One-Step is Enough: Sparse Autoencoders for Text-to-Image Diffusion Models" will be presented at #NeurIPS2025!
@ViaSurkov is presenting it at #MexIPS2025:
📍𝐈𝐟 𝐲𝐨𝐮 𝐚𝐫𝐞 𝐚𝐭𝐭𝐞𝐧𝐝𝐢𝐧𝐠 𝐍𝐞𝐮𝐫𝐈𝐏𝐒 𝐢𝐧 𝐌𝐞𝐱𝐢𝐜𝐨 𝐂𝐢𝐭𝐲, 𝐩𝐥𝐞𝐚𝐬𝐞 𝐬𝐭𝐨𝐩 𝐛𝐲!
Date: Thursday, Dec 4, 2025
Time: 11:00 AM – 2:00 PM PST
Location: Foyer (Mexico City Poster Session)
Come visit @ViaSurkov it's his first conference and he will be happy to explain his amazing work.
Sadly, #NeurIPS2025 does not allow for parallel presentation in San Diego. However, I am in San Diego and happy to meet up / chat. Please don't hesitate to reach out here or via [email protected].
Once again, a big shout out to our brilliant students Viacheslav Surkov and Antonio Mari who did phenomenal work here and pushed this work (that started as a class project more than a year ago) all the way to pass the high threshold of #NeurIPS2025.
Also, I want to thank manifund.org/ (@andyarditi and @ryan_kidd44 in particular) for helping us to finance Viacheslav Surkov's conference trip.
Please find more information about our work below. We have so many amazing interactive materials (e.g., 3x huggingface demo spaces) for you to check out. Most of our implementations are open-sourced (RIEBench on FLUX, which we added to our appendix during the NeurIPS rebuttal is currently missing but we plan to add it ASAP).
Me demoing the demo attached.

Viacheslav Surkov retweeted
How do diffusion models create images and can we control that process?
We are excited to release a update to our SDXL Turbo sparse autoencoder paper.
New title: One Step is Enough: Sparse Autoencoders for Text-to-Image Diffusion Models
Spoiler: We have FLUX SAEs now :)
Viacheslav Surkov retweeted
We also have a website sdxl-unbox.epfl.ch
and a paper arxiv.org/abs/2410.22366
Also I should have probably provided some of the results already at the first post...


Viacheslav Surkov retweeted
In case you ever wondered what you could do if you had SAEs for intermediate results of diffusion models, we trained SDXL Turbo SAEs on 4 blocks for you. We noticed that they specialize into a "composition", a "detail", and a "style" block. And one that is hard to make sense of.
Viacheslav Surkov retweeted

9th highest scored ICLR 2025 paper 8,8,8,10. Worth noting all reviewers increased their scores by 2 after rebuttals
tldr: they introduce a bunch of architectural changes to a diffusion transformer, getting 100x speed improvements with no real quality impacts

We also found that transformer blocks play different roles in the generation process:
down.2.1 - scene composition
up.0.1 - texture and style
up.0.0 - local details
mid.0 - more abstract information
Kudos to the collaborators who made this possible!
@wendlerch @MiTerekhov @jdeschena @cervisiarius @caglarml
Highly appreciate the initial contribution of Danila Zubko, the valuable discussions and feedback from
@davidbau @im_td @NivCohenHuji @gytdau and Alexander Sharipov
Many thanks to @StabilityAI for creating SDXL Turbo
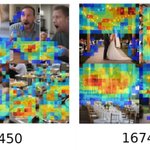
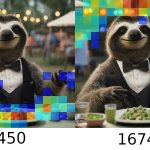
Let’s try to generate an image with an empty prompt and enable only one feature. This results in meaningful images highlighting the same concepts as above: faces, dishes, lights and tents!

Take a look at images where these features are most prominent. They correspond to similar objects as above. E.g. 4539 activates on funny animal faces, while 450 highlights dishes.

First, we generate an image with a fun prompt. Below are the SAE features that are most active during a forward pass through one of transformer blocks.

Stable Diffusion XL Turbo can generate images in 1-4 denoising steps
We trained Sparse autoencoders (SAEs) on updates of 4 transformer blocks within SDXL Turbo's U-net
This resulted in 20480 features
Explore these features in our demo!
huggingface.co/spaces/surokp…
Viacheslav Surkov retweeted

This summer, a students' team from EPFL's @BernoulliCenter traveled to Bulgaria for the International Mathematics Competition. They came back with several medals and prizes and took the 7th place as a team. Congratulations to all of them!
bernoulli.epfl.ch/epfl-stude…


Viacheslav Surkov retweeted

shout out to my amazing collaborators: @ViaSurkov, @VminVsky, @russogiusep, @cervisiarius, and @caglarml
paper link: arxiv.org/abs/2407.06946
