

Physicist, Telecom Engineering lover, HPC Enthusiast. Prog Rock/Metal fan
Joined December 2017
- Tweets18.6K
- Following126
- Followers10.5K
- Likes11.5K





Pinned Tweet
Researchers have developed a new simulator to predict the throughput of basic blocks of all Intel Core μarchs released in the last decade, demonstrating to be more accurate than the predictions of state-of-the-art tools by more than an order of magnitude.
arxiv.org/pdf/2107.14210.pdf

After a long time, I’m finally on vacation, taking the opportunity to rest my mind from all the AI noise. If the world ends or the bubble bursts while I’m away, just know that I’m happily fishing in the ocean and enjoying life.
See you soon. 🦊
youtube.com/watch?v=vJXCgHG6…
Underfox retweeted
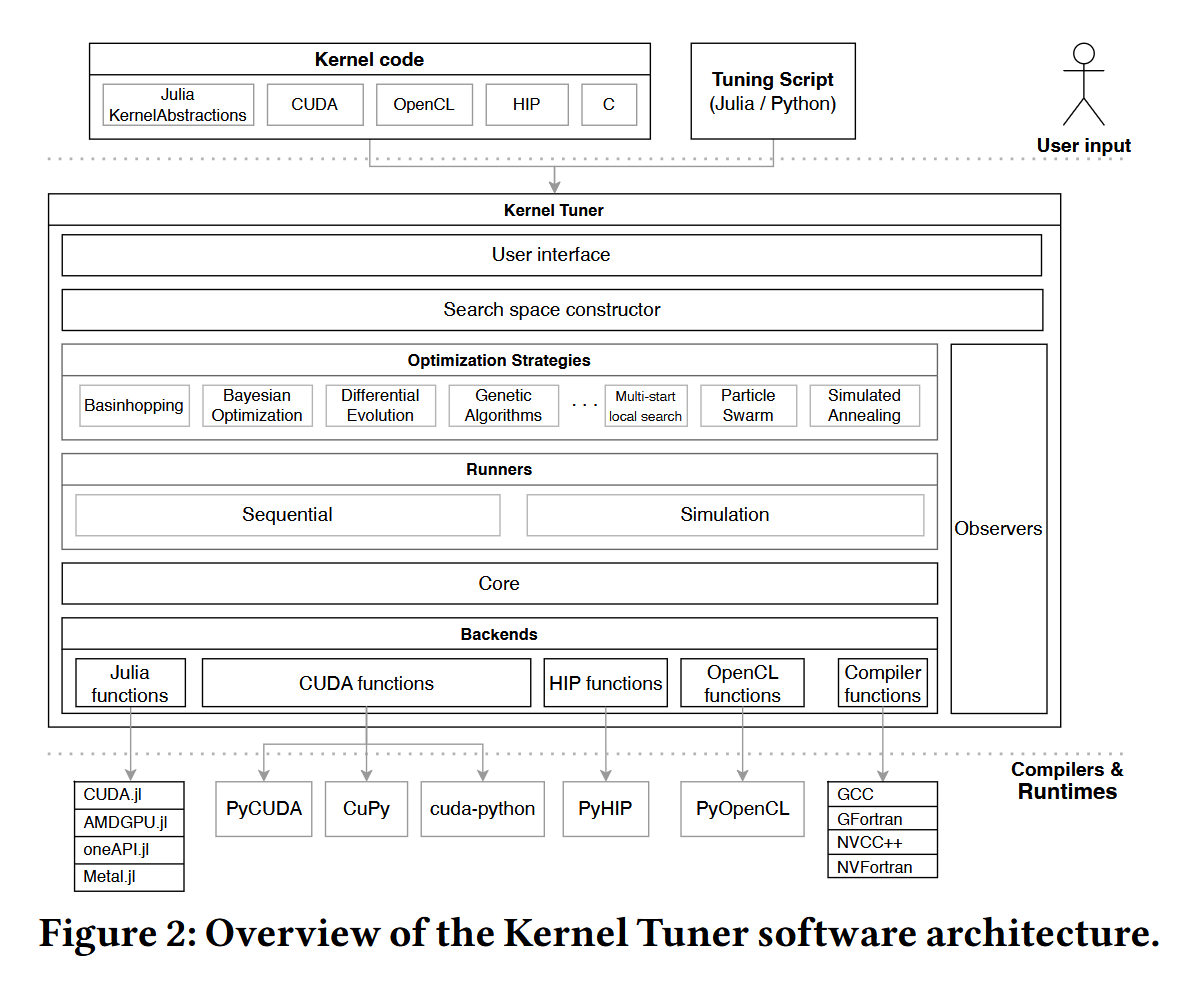
In this paper is introduced the first auto-tuning framework for Julia GPU kernels as an accessible Julia package, enabling systematic auto-tuning of hardware-agnostic kernels to target a wide variety of platforms, such as NVIDIA, AMD, Intel, and Apple.
arxiv.org/pdf/2608.21227


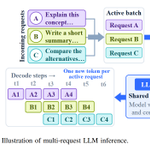
In this paper is presented CHIPSMORE, a multi-mode and multi-request CIM accelerator for LLM inference across diverse operating scenarios, including base-mode execution, LoRA adaptation, varying context lengths, and concurrent multi-request serving.
arxiv.org/pdf/2608.30509


In this paper is introduced the first auto-tuning framework for Julia GPU kernels as an accessible Julia package, enabling systematic auto-tuning of hardware-agnostic kernels to target a wide variety of platforms, such as NVIDIA, AMD, Intel, and Apple.
arxiv.org/pdf/2608.21227


Underfox retweeted
[Basic Concepts] In this paper is presented a comprehensive and critical overview of on-chip photonic neural networks, spanning fundamental device technologies, system architectures, and emerging applications.
advanced.onlinelibrary.wiley…


Underfox retweeted
In this paper is proposed GapFill, a specialized tool designed to assist professional anime colorists in addressing small, unpainted areas, integrating seamlessly into existing professional workflows.
arxiv.org/pdf/2609.00800


Underfox retweeted
In this paper, AMD researchers have presented the first micro-architecture based performance characterization of SPEC CPU 2026 on AMD EPYC "Zen 5" processor.
arxiv.org/pdf/2609.01527

Underfox retweeted
Researchers have presented the first experimental ML-enabled Process-Technology Co-Optimization (PTCO) framework for optimizing 2D TMD FET fabrication directly from statistically meaningful experimental data rather than pure simulation data.
arxiv.org/pdf/2609.00722

Underfox retweeted
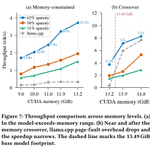
In this paper is proposed NeuroPrefetcher, a storage-backed sparse inference runtime built around predictive delta prefetching for the regime where an LLM exceeds resident memory throughout execution.
arxiv.org/pdf/2608.22643


In this paper is proposed NeuroPrefetcher, a storage-backed sparse inference runtime built around predictive delta prefetching for the regime where an LLM exceeds resident memory throughout execution.
arxiv.org/pdf/2608.22643


Researchers have presented the first experimental ML-enabled Process-Technology Co-Optimization (PTCO) framework for optimizing 2D TMD FET fabrication directly from statistically meaningful experimental data rather than pure simulation data.
arxiv.org/pdf/2609.00722

