

The Biomedical NLP group co-located at the University of Massachusetts Amherst and Lowell. Led by Dr. Hong Yu. @UMass_NLP @manningcics @UMassLowell #NLProc
UMass
Joined August 2024
- Tweets47
- Following17
- Followers34
- Likes2




🎉 New paper alert! #EMNLP24
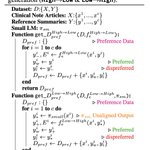
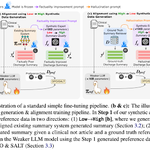
SYNFAC-EDIT: Synthetic Imitation Edit Feedback for Factual Alignment in Clinical Summarization
🔗 arxiv.org/abs/2402.13919
Work done by @PrakamyaMishra @YaoZonghai @vashisht51, Feiyun Ouyang, Beining Wang, Vidhi Dhaval Mody, and Prof. Hong Yu
(0/N)
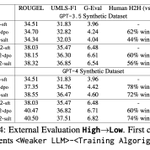
📊 External Evaluation: We compared STF-trained models vs. DPO/SALT-trained ones and found that GPT-2 & Llama2 excelled with GPT-4 edits over GPT-3.5. SALT's granular feedback improved alignment, with GPT-2 showing higher ROUGEL in High→Low training and stable factuality.
(13/N)

🎉 New paper alert!
Large Language Models are In-context Teachers for Knowledge Reasoning #EMNLP24 finding
🔗 Read the paper: arxiv.org/abs/2311.06985
Work done by @jcz12856876 @YaoZonghai @YangZhichaoNLP and Prof. Hong Yu
#BioNLP #InstructionTuning
(0/N)
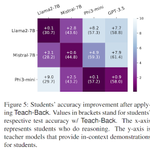
🧪 To verify the causality, we propose teach-back to align the teacher’s rationales with the student’s self-explanations. Experiments show that teach-back can greatly improve the in-context teaching ability of a model.
(7/N)

