


50 Cent was shot nine times outside his grandmother's house in 2000. Seven years later, Forbes estimated he made $100 million from Vitaminwater.
In the video below, he tells Howard Stern why the shooter was paid to do it.
On May 24, 2000, he was 24 and had just landed a record deal. A gunman walked up and fired nine shots at close range. His grandmother was in the front yard.
He was hit in the hand, arm, hip, both legs, chest and face. Bullet fragments are still in his tongue, and he says his voice was never the same.
His label dropped him.
Three years later, Get Rich or Die Tryin' sold about 8 million copies.
In 2004, he took a stake in a small drink company called Glacéau and made his own flavor, Formula 50. In 2007, Coca-Cola bought it for $4.1 billion.
On Stern, he says getting shot hurt less than going back to the dentist for root canals.
Would you have kept rapping after being shot nine times, or walked away?
Dave Chappelle signed a $50 million deal with Comedy Central in 2004. A year later, he walked off the set and flew to Africa without telling his wife.
In the video below, he tells Oprah what really happened.
Chappelle's Show was one of the biggest shows on TV. Comedy Central paid $50 million to keep it going for two more seasons.
Then the stories started. First the papers said he had pneumonia. Then writer's block. He says he was asked to back up stories he never told.
He says people around him kept calling him insane and tried to get him to take psychiatric medication.
In 2005, in the middle of making season three, he left. Only his brother knew he was going to Africa.
"I wasn't walking away from the money. I was walking away from the circumstances," he told Oprah.
He came back years later. In 2016, Netflix paid him $20 million per stand-up special.
Would you have walked away from $50 million?
Steve Harvey is worth an estimated $200 million. He once had $35 and was sleeping in his car.
In the video below, he tells the story of the phone call that almost didn't happen.
For about three years, Harvey lived out of a 1976 Ford Tempo. He washed up at gas stations and pool showers and kept his food in an Igloo cooler.
One night in a hotel parking lot, he says, he cried and told God he was done.
Then he went to a pay phone to check his answering machine. Showtime at the Apollo had seen his tape and wanted him on TV that Sunday. He couldn't afford the trip to New York.
There was a second message: a $150 gig in Jacksonville, Florida. He drove there, killed, and the club owner paid him another $150 to stay one more night.
With $300, he made it to the Apollo, got a standing ovation and was paid $750.
He went on to host Showtime at the Apollo for eight years. Today he hosts Family Feud.
Would you have quit with $35 left, or kept driving?
6
11
685
Jim Carrey wrote himself a $10 million check when he was broke. Years later, he put it in his father's casket.
In the video below, he tells Oprah in 1997 how he wrote it and what happened next.
In the mid-'80s, Carrey was a struggling comic in Los Angeles. He says he used to park on Mulholland Drive at night and picture directors wanting to work with him.
He wrote a check to himself for $10 million "for acting services rendered" and dated it Thanksgiving 1995.
He kept it in his wallet until it fell apart.
Then came 1994: Ace Ventura, The Mask and Dumb and Dumber, three hits in one year. Carrey says that just before Thanksgiving 1995, he found out he was getting $10 million for Dumb and Dumber.
His father, who pushed him to try comedy, died in 1994. Jim slipped the worn-out check into his casket.
"You can't just visualize and then go eat a sandwich," he told Oprah.
Do you think the check worked, or did the work do all of it?
holy f*ck. this one prompt stops Claude Code from saying "done" when it isn't.
you know the moment. Claude says "all tests pass, ready to ship." you run it. nothing works.
researchers have a name for it: verifier theater. the check goes green and nothing actually got checked. they found 217 real agent loops on GitHub and only 76 had any verifier at all.
so I turned the fix into one copy-paste prompt for Claude Code:
> it runs your check before touching anything. already green? it stops
> it can't edit your tests to make them pass
> after it passes, it breaks the code on purpose. if the check still passes, the check was fake
> every "done" comes with the raw output, not a summary
works on any project. paste it once, add your test command, that's it.
99% of people still trust the green checkmark.
like it before this thread gets buried.
then read the full guide below ↓


same 1,000 agents. Opus 5.5 stalled at 26%. Fable 5.2 finished in 30 hours.
I went through every guide Anthropic shipped with it plus 4 research papers, and turned it all into one guide. 6 layers, 8 visuals, a prompt for every layer.

1
15
600
this is an actual f*cking goldmine
Fable 5.2 is insane at running a whole team in Claude Code while you sleep...
you give it one job before bed. the boring kind you keep putting off:
> fix the 40 tests that have been red for a month
> move your app from JavaScript to TypeScript
> add login, dark mode or payments to your side project
> clean up the repo nobody wants to touch
paste this prompt, answer its questions for 5 minutes, go to sleep.
it splits the job into parts and hands them to 12 agents. one plans, some write code, one runs the tests, one breaks the code on purpose to prove the tests actually catch bugs, one remembers every failure so nothing gets tried twice.
it can't deploy, can't touch main, can't spend more than the budget you set.
you wake up to one file: what's done (with proof), what's blocked on you, and what it found along the way.
and every night it writes down what to do differently, so the next run starts smarter.
like it before this thread gets buried.
then read the full guide below ↓

9
13
412
Trundur retweeted
holy f*ck. paste this into Claude Code before you spin up another subagent.
your agents stop passing broken work to each other. one check between every step, one agent per file, and it stops and asks you when the same thing fails twice.
Google and MIT tested 180 agent setups. with nobody checking, errors grew 17.2x. with one check between steps, 4.4x.
so I turned it into one copy-paste prompt for Fable 5.2. drop in your task and your test command, that's it.
the crazy part is on step-by-step work, adding more agents made every setup worse, by 39% to 70%.
99% of people run 20 subagents in Claude Code and never put a single check between them.
bookmark it before this thread gets buried.
then read the full guide below ↓

holy f*ck. paste this into Claude Code before you spin up another subagent.
your agents stop passing broken work to each other. one check between every step, one agent per file, and it stops and asks you when the same thing fails twice.
Google and MIT tested 180 agent setups. with nobody checking, errors grew 17.2x. with one check between steps, 4.4x.
so I turned it into one copy-paste prompt for Fable 5.2. drop in your task and your test command, that's it.
the crazy part is on step-by-step work, adding more agents made every setup worse, by 39% to 70%.
99% of people run 20 subagents in Claude Code and never put a single check between them.
bookmark it before this thread gets buried.
then read the full guide below ↓
holy f*ck. one agent loop burned 8 million tokens in 48 hours.
researchers checked 217 real agent loops and found the trap everyone running Claude Code overnight walks into: a loop with no reason to stop.
one of them burned 8 million tokens in 48 hours while nobody was watching.
and Anthropic's own docs say a stop rule in your prompt is only a soft cap. the hard caps are two flags almost nobody uses.
so I turned the fix into one prompt for Fable 5.2 every cap, every rule, the full copy-paste template, all of it spelled out.
99% of people start an agent before bed and wake up to the bill.
bookmark it before this thread gets buried.
then read the full guide below ↓

same 1,000 agents. Opus 5.5 stalled at 26%. Fable 5.2 finished in 30 hours.
I went through every guide Anthropic shipped with it plus 4 research papers, and turned it all into one guide. 6 layers, 8 visuals, a prompt for every layer.
4
15
199
Trundur retweeted
same 1,000 agents. Opus 5.5 stalled at 26%. Fable 5.2 finished in 30 hours.
I went through every guide Anthropic shipped with it plus 4 research papers, and turned it all into one guide. 6 layers, 8 visuals, a prompt for every layer.
same 1,000 agents. Opus 5.5 stalled at 26%. Fable 5.2 finished in 30 hours.
I went through every guide Anthropic shipped with it plus 4 research papers, and turned it all into one guide. 6 layers, 8 visuals, a prompt for every layer.
Trundur retweeted
this Anthropic Fable 5.2 guide f*cking insane
they tested single sentences in the prompt and measured what each one changed.
they gave Fable an advisor. with no line saying when to ask, it was consulted 0 times out of 198.
a "never" rule with the exception in the same line got followed 9 times in 10. split into two lines: 1 in 10.
same model. one sentence apart.
so I put every line that moved the numbers into one copy-paste CLAUDE.md for Fable 5.2. every line, every number, all of it spelled out.
the crazy part is your old prompts make it worse. one stale "never retry" note cut retries to about 4 in 10.
99% of people will switch to Fable 5.2 and keep the CLAUDE.md they wrote for older models.
bookmark it before this thread gets buried.
then read the full article below ↓


this Anthropic Fable 5.2 guide f*cking insane
they tested single sentences in the prompt and measured what each one changed.
they gave Fable an advisor. with no line saying when to ask, it was consulted 0 times out of 198.
a "never" rule with the exception in the same line got followed 9 times in 10. split into two lines: 1 in 10.
same model. one sentence apart.
so I put every line that moved the numbers into one copy-paste CLAUDE.md for Fable 5.2. every line, every number, all of it spelled out.
the crazy part is your old prompts make it worse. one stale "never retry" note cut retries to about 4 in 10.
99% of people will switch to Fable 5.2 and keep the CLAUDE.md they wrote for older models.
bookmark it before this thread gets buried.
then read the full article below ↓
Trundur retweeted
this loop engineering research f*cking insane
they searched 36,487 repos for agents running in loops and named the trap everyone running Fable 5.2 is about to walk into: verifier theater.
a check that approves the work without really checking it. the loop goes green and nothing got verified.
so I turned the fix into one prompt for Fable 5.2. every step, every formula, the full copy-paste template, all of it spelled out.
the crazy part is only 76 of the 217 loops they found had a verifier at all. the rest just trusted the model.
99% of people see a green check and never ask what it actually checked.
bookmark it before this thread gets buried.
then read the full article below ↓


this loop engineering research f*cking insane
they searched 36,487 repos for agents running in loops and named the trap everyone running Fable 5.2 is about to walk into: verifier theater.
a check that approves the work without really checking it. the loop goes green and nothing got verified.
so I turned the fix into one prompt for Fable 5.2. every step, every formula, the full copy-paste template, all of it spelled out.
the crazy part is only 76 of the 217 loops they found had a verifier at all. the rest just trusted the model.
99% of people see a green check and never ask what it actually checked.
bookmark it before this thread gets buried.
then read the full article below ↓
Trundur retweeted
holy f*ck. same 1,000-agent setup. Opus 5.5 stalled at 26%. Fable 5.2 finished in 30 hours.
that's Anthropic's own Fermat's Last Theorem run, fully formalized in Lean. their first attempt took 11 days.
same harness, same agents. the only thing that changed was the model.
and you don't need Fable 5.2 in every seat. you need it in one: planning, routing, checking. Haiku, Sonnet and Opus do the typing.
I turned that into one copy-paste prompt for Claude Code. every step, every formula, all of it spelled out.
the crazy part is Fable 5.2 at High already scores about level with Opus 5.5 at Max on FrontierCode 2.0. for roughly half the cost per task.
99% of people will just swap the model ID and run Fable on grep.
bookmark it before this thread gets buried.
then read the full article below ↓

holy f*ck. same 1,000-agent setup. Opus 5.5 stalled at 26%. Fable 5.2 finished in 30 hours.
that's Anthropic's own Fermat's Last Theorem run, fully formalized in Lean. their first attempt took 11 days.
same harness, same agents. the only thing that changed was the model.
and you don't need Fable 5.2 in every seat. you need it in one: planning, routing, checking. Haiku, Sonnet and Opus do the typing.
I turned that into one copy-paste prompt for Claude Code. every step, every formula, all of it spelled out.
the crazy part is Fable 5.2 at High already scores about level with Opus 5.5 at Max on FrontierCode 2.0. for roughly half the cost per task.
99% of people will just swap the model ID and run Fable on grep.
bookmark it before this thread gets buried.
then read the full article below ↓
Trundur retweeted
this loop engineering research f*cking insane
researchers searched 36,487 repos for agents running in autonomous loops. they confirmed 217. that's 0.59%.
and most of those were a trigger and not much else. only 76 had a verifier. only 35 kept any memory between runs. only 10 tracked what it cost.
so I turned the missing parts into one prompt for Opus 5.5. every step, every formula, the full copy-paste template, all of it spelled out.
the crazy part is the whole timeline posted "design loops, not prompts" in June. almost nobody built the part that decides when the loop is done.
99% of people still let the model decide it's finished and call it a loop.
bookmark it before this thread gets buried.
then read the full article below ↓


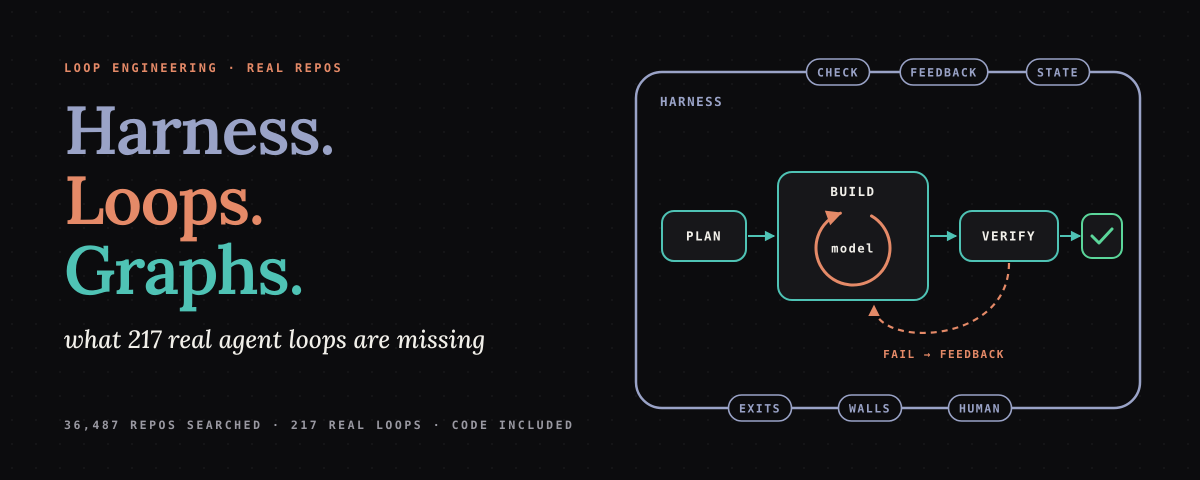
this loop engineering research f*cking insane
researchers searched 36,487 repos for agents running in autonomous loops. they confirmed 217. that's 0.59%.
and most of those were a trigger and not much else. only 76 had a verifier. only 35 kept any memory between runs. only 10 tracked what it cost.
so I turned the missing parts into one prompt for Opus 5.5. every step, every formula, the full copy-paste template, all of it spelled out.
the crazy part is the whole timeline posted "design loops, not prompts" in June. almost nobody built the part that decides when the loop is done.
99% of people still let the model decide it's finished and call it a loop.
bookmark it before this thread gets buried.
then read the full article below ↓
Trundur retweeted
holy f*ck. Jensen Huang gives feedback to 60 people at once. you correct the same agent mistake every single day.
no 1:1s. every piece of feedback goes in front of everyone, so one mistake teaches the whole team.
that's exactly how you run agents. the article below makes the case: managing agents is managing a team, whether you wanted the job or not.
> give every agent a check it can run, not "looks done"
> tell it what it can't see in the repo, skip what it can
> corrected something twice? it goes in CLAUDE.md for every session
> two failed corrections? kill the session, rewrite the prompt
> review the diff like you'll get paged for it
I turned it into one prompt for Opus 5.5. Jensen-style: every agent gets the same context, every lesson becomes a rule.
Send it to Opus 5.5, and thank me later. Then read the article below ↓


