

Senior Data Scientist @TOTHENEW Creating Machine Learning Threads.
India🇮🇳
Joined July 2021
- Tweets850
- Following93
- Followers1.5K
- Likes1K





Pinned Tweet
Everything about using docker with python (Flask or Django) and ML in Production (TensorFlow Serving).
I invested my time in this course and have completed proof of concepts.
Python in containers helped me for
‣ Dockerizing applications
‣ Deploy ML models
‣ Multiple services

Amazing to see how the data science world has evolved
From fine-tuning neural networks → tuning prompts
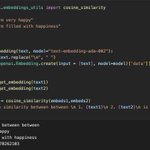
From writing nested loops for similarity → using vector DBs
From supervised learning → giving examples in prompts
From accuracy metrics → LLM-as-a-judge
Day 1 of the Data Hack Summit 2025 was amazing, learned a lot about AI agents, in-house LLMs, and MCPs. Got to see some brilliant minds and innovative products. It was a real pleasure meeting @joshuastarmer, whose tutorials I’ve been following for years - Triple Bam!


Thought of posting today after facing issues adding 300k+ embeddings (356-dim) to a vector DB:
• Overflow & NaNs during normalization
• Clipped embeddings values to [-10,10] to fix
• Manual normalization after clipping
• Used Qdrant with DOT distance for similarity search
It's time to combine GraphDBs with vector databases to achieve better results in edge cases where traditional vector searches struggle to find relevant chunks.
Feels like the XGBoost approach for RAG
xitter.cf/TrajVoid/status/173012…


I worked on some fine-tuning exercises for a code generation [StarCoder] AI model last week.
Here's a blog:
tothenew.com/blog/fine-tunin…

Tried this method recently in a project, it's solid. Code's way easier to read now.
Pipeline's saved pickle file is production-ready without extra test time code for preprocessing or transformations.
Even added it to my custom pipeline wrapper.
xitter.cf/svpino/status/17701882…


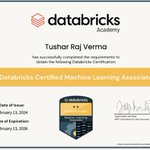
After thorough preparation, I successfully passed the Databricks Machine Learning Associate exam.
Throughout the past year, I had been creating content and implementing most of the modules, which greatly contributed to my success.
xitter.cf/TrajVoid/status/160888…

For about two months, I dedicated most of my time to various @databricks courses related to Machine Learning.
Getting practical knowledge about this platform and upgrading my skills.
I have explored advanced skills that will help me create insightful content.
1/5

Here is an in-depth overview of my preparation process from last year.
xitter.cf/TrajVoid/status/160983…
Resources and a course roadmap with the implementation platform of my previous thread related to @databricks courses.
‣ You will find here GitHub repositories specific to Machine Learning.
‣ Platform to implement those repositories and setup.
1/8
xitter.cf/TrajVoid/status/160888…

Zero-shot learning is pretty cool and makes a big impact when used for things like images and text.
I've been working on it, and I'm still at it!
xitter.cf/TrajVoid/status/157723…

Excited to share my blog post on AWS training job with XGBoost! 🚀 Dive into the world of cloud computing and machine learning.
Check it out here:
tothenew.com/blog/aws-custom…
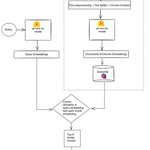
Check out my design addressing the max token length prompt issue.
No more sharing the entire document repository at once in sequence with any API service.
💡 Open to suggestions and recommendations! 🔍

🌐🔊 Exciting Tech Journey: From English Audio to Multilingual Voices! 🔊🌐
1/ 🎙️ Started with English audio, but the world is diverse! 🌍 I transformed English audio to text using the power of code. 🧑💻 Let's explore how I bridged the language gap!
pypi.org/project/openai-whis…

4/ ⏸️ Introducing the Art of Pauses: It's not just about words, but the rhythm of speech! 🎵 I implemented pause logic to make the conversation more natural, adding a human touch that goes beyond translation. Added Pauses with silence and timestamp logic
stackoverflow.com/questions/…
I will be sharing a sequence of threads related to use cases for GenAI. Please stay tuned @TrajVoid
Getting recognized at work for the part you contribute to the project is an awesome feeling.
After a ramp-down of a 2+ years-long learning project.
It was an opportunity to contribute learning/Experience to a new project.
Thought of writing some Recommendations🧵

‣ Before adding anything to the process as the first task try reproducing the result of the existing process.
‣ Take a focused session with yourself on how these things can be improved.
‣ Automate tasks as much as you can.[Really Important]
With all my experience in the industry, I share these recommendations.
If you like this thread consider following @TrajVoid
For more related tips.