

Deep Learning Researcher Nvidia - Efficiency/Numerics/Edge models
Amsterdam, The Netherlands
Joined May 2009
- Tweets527
- Following227
- Followers703
- Likes551



Happy to share the work we've done on our amazing new Nemotron 3.5 Bolt model! The model fits 74B params in 24GB with aggressive 2-bit quantization, using quantization-aware distillation to recover accuracy. We show it's much more pareto-optimal to do 2-bit quantization at iso model size.
#1 and #2 on several leaderboards like Pinchbench/BrowseComp/WebArena for small models. A great release, and can't wait to see how people use this on their new RTX Spark devices!!!


Tijmen Blankevoort retweeted

Disaggregated quantization for LLMs 🧵
LLM prefill and decode can be processed by separate weights in different precisions. Boosts speed AND accuracy. Offloading makes it zero-overhead on long sequences for dense models. Applicable to existing quantized checkpoints.
Paper: arxiv.org/abs/2609.26333
Code: github.com/IST-DASLab/disagg…
Qwen3.8 NVFP4 prefillers: huggingface.co/ISTA-DASLab/Q…
Tijmen Blankevoort retweeted

Nemotron 3.5 Lightning:
Same architecture as 3.0 Nano,
with added speculative decoding, and with the intelligence of 3.0 Super.
⚡️⚡️⚡️


Tijmen Blankevoort retweeted

Why repetition works so well is still an open question. There's a lot to uncover about training dynamics of SFT, and we hope this is a useful data point.
Joint work with co-authors @Sagar_Vaze @TiRune @y_m_asano
Paper: arxiv.org/abs/2602.11149
Code: github.com/dkopi/data-repeti…

Tijmen Blankevoort retweeted
Today, @NVIDIA is launching the open Nemotron 3 model family, starting with Nano (30B-3A), which pushes the frontier of accuracy and inference efficiency with a novel hybrid SSM Mixture of Experts architecture. Super and Ultra are coming in the next few months.

Looking for cracked full-time Deep Learning researchers on Efficiency, Quantization and Sparsity. Join our world-class applied deep learning research team at Nvidia. Team creates the Nemotron models, we influence the hardware with our research. Shoot me a message! Am at Neurips!
I recently made the news because of a doc I wrote in Meta’s GenAI organization. ‘The Information’ wrote about it as if I did a big raging ‘mic drop’ before leaving the company. Nothing could be further from the truth - so setting the record straight here. open.substack.com/pub/blanke…
Tijmen Blankevoort retweeted

So You Think your @iclr_conf rejection was surprising?
We nearly fell out of our chairs when our 7.25 avg rating (10,8,6,5 -- i.e. top 4%) Bitune paper got rejected 😅.
It's not like new points or problems surfaced... Just ¯\_(ツ)_/¯ I guess?
Sharing this so that especially younger researchers also see that the review process is somewhat random and can be _very_ frustrating - for all of us :). Oh well! Onwards!

Tijmen Blankevoort retweeted

🪩The @stateofai 2024 has landed! 🪩
Our seventh installment is our biggest and most comprehensive yet, covering everything you *need* to know about research, industry, safety and politics.
As ever, here's my director’s cut (+ video tutorial!) 🧵
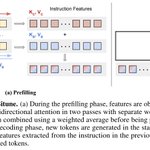
Our new Bitune method is out - improving results on instruction-tuning! We add bidirectional attention to a decoder-only architecture, and concoct an IT-specific PEFT method for Q&A and instruction following settings

The algorithm is very simple, and provides better results across the boards at very little cost. We see gains of around 1-5% for many common models in zero-shot task eval

Check out our amazing website: dkopi.github.io/bitune/ The paper: arxiv.org/abs/2405.14862 And the code: github.com/dkopi/bitune This is work from the great @dawkopi and @y_m_asano, and yours sincerely
Tijmen Blankevoort retweeted
Today we introduce Bidirectional Instruction Tuning (Bitune). It's a new way of adapting LLMs for the instruction->answering stage.
It allows the model to process the instruction/question with bidirectional attention, while the answer generation remains causal.

Tijmen Blankevoort retweeted
Another week, another release:
Our PEFT method VeRA (LoRA but 10-100x less parameters thanks to random projections) is now on HF PEFT!
so now's a good time to `pip install peft`
Thx to @alexfmckinney @BenjaminBossan @dkopi + @TiRune
huggingface.co/docs/peft/pac…

Tijmen Blankevoort retweeted

Our paper, "The LLM Surgeon," accepted at ICLR 2024, achieves SOTA in LLM pruning in all unstructured, semi-structured, and the most challenging but most effective structured pruning that removes entire matrix rows/columns.
Happy to share that code is now publicly available.
Code: github.com/Qualcomm-AI-resea…
Thread: xitter.cf/tychovdo/status/…
Paper: arxiv.org/abs/2312.17244
w/ @mnagel87, @martvanbaalen, @y_m_asano, @TiRune

The LLM Surgeon
paper page: huggingface.co/papers/2312.1…
State-of-the-art language models are becoming increasingly large in an effort to achieve the highest performance on large corpora of available textual data. However, the sheer size of the Transformer architectures makes it difficult to deploy models within computational, environmental or device-specific constraints. We explore data-driven compression of existing pretrained models as an alternative to training smaller models from scratch. To do so, we scale Kronecker-factored curvature approximations of the target loss landscape to large language models. In doing so, we can compute both the dynamic allocation of structures that can be removed as well as updates of remaining weights that account for the removal. We provide a general framework for unstructured, semi-structured and structured pruning and improve upon weight updates to capture more correlations between weights, while remaining computationally efficient. Experimentally, our method can prune rows and columns from a range of OPT models and Llamav2-7B by 20%-30%, with a negligible loss in performance, and achieve state-of-the-art results in unstructured and semi-structured pruning of large language models.

Tijmen Blankevoort retweeted
Today, with @Tim_Dettmers, @huggingface, & @mobius_labs, we're releasing FSDP/QLoRA, a new project that lets you efficiently train very large (70b) models on a home computer with consumer gaming GPUs. 1/🧵
answer.ai/posts/2024-03-06-f…

Tijmen Blankevoort retweeted

Our work on Vector Quantization for SOTA size vs accuracy trade-offs in LLMs is on Arxiv!
Thanks co-authors Andrey Kuzmin, @mnagel87, @pcoranje, Cedric Bastoul, Eric Mahurin, @TiRune and Paul Whatmough for their hard work
And thanks to @_akhaliq for amplifying!
Qualcomm presents GPTVQ
The Blessing of Dimensionality for LLM Quantization
show that the size versus accuracy trade-off of neural network quantization can be significantly improved by increasing the quantization dimensionality. We propose the GPTVQ method, a new fast method for post-training vector quantization (VQ) that scales well to Large Language Models (LLMs). Our method interleaves quantization of one or more columns with updates to the remaining unquantized weights, using information from the Hessian of the per-layer output reconstruction MSE. Quantization codebooks are initialized using an efficient data-aware version of the EM algorithm. The codebooks are then updated, and further compressed by using integer quantization and SVD-based compression. GPTVQ establishes a new state-of-the art in the size vs accuracy trade-offs on a wide range of LLMs such as Llama-v2 and Mistral. Furthermore, our method is efficient: on a single H100 it takes between 3 and 11 hours to process a Llamav2-70B model, depending on quantization setting. Lastly, with on-device timings for VQ decompression on a mobile CPU we show that VQ leads to improved latency compared to using a 4-bit integer format.
