

@SwenChan
Account based inEast Asia!
About this account
- Account based in
- East Asia
- Connected via
- North America App Store
X says this location may be affected by a proxy or VPN.
Account-level information from X, not a live location or the device used for a specific post.
Product Engineer👷♂️Building systems for life & work prev @virtuals_io @ETHPanda_Org Building👉@DealAgentX @aiweb3school @LXDAO_Official @DeSciAsia
Joined February 2017
- Tweets1.9K
- Following417
- Followers776
- Likes7K



Pinned Tweet
前天测了3.6,今天测了一下Qwen 3.8 9B和27B
设备还是:
MacBook Pro
M1 Max / 64GB Unified Memory / 24-core GPU
btw,这两次测试使用的都是同一个 prompt:
“Write a 500-word explanation of how Bitcoin proof-of-work works.”
先测了 Qwen3.8-9B Distill:
Thinking ON
33.48 tok/s
6,605 tokens
结果:3m 18s
Thinking OFF
34.30 tok/s
652 tokens
结果:19.4s
同一个模型、同一台 Mac、几乎完全一样的 raw inference speed。
仅仅关闭不必要的 reasoning:
3m18s → 19s,任务完成速度快了约 10×。
然后是正式的 Qwen3.8-27B Q4_K_M:
Thinking ON
9.92 tok/s
10,616 tokens
结果:17m 52s
Thinking OFF
10.79 tok/s
748 tokens
结果:1m 10s
又是一次:
堪称龟速的 17m52s → 1m10s,约 15×。
模型生成 token 速度倒是比较稳定:
9B 的物理速度一直稳定在 ~34 tok/s;
27B 也一直稳定在 ~10–11 tok/s。
有趣的结论浮出水面:把普通任务从几十秒拖到十几分钟的,是模型自以为是“thinking”生成的上万 reasoning tokens。
我还亲眼目睹了它为了符合“500字”的要求,连出3版并逐字数数的过程(图2),不得不说这个测试挺适合治疗失眠。
所以我对当前开源大模型的看法依旧依旧是把它当工具用,告诉(设计)他什么时候该思考、什么时候该把任务升级给云端,才能最大化其承担的工作。
总之,今日第一次从上帝角度理解了“人类在思考,上帝在发笑”的意味,有趣有趣。


最近 Qwen3.8-27B 挺火,出于两个动机我也想测试一下目前本地模型的能力。
第一,我一直在想一种 Local × Cloud 的 24/7 AI workflow:
日常、重复、隐私敏感的任务,不一定需要最强模型。一个「表现不错、成本接近于零、可以永远在线」的本地模型,或许可以承担大量 background work;真正困难的 任务,再交给云端的 frontier model。
第二,我最近也在做 AI hardware。
在产品制作过程中,我开始关心一个问题:一个足够小、能够真正部署在本地甚至端侧的模型,如果可以完成感知、理解、简单决策和绝大多数日常交互,产品体验可能会上一个台阶。
不过目前 Qwen3.8 官方开放的权重还是 2.4T-A95B,27B 并没有正式开放;Qwen3.7 也没有对应的小参数 open-weight model。
于是我退一步,测试目前可以直接部署的 Qwen3.6-27B。
俺的设备:
MacBook Pro
M1 Max / 64GB Unified Memory / 24-core GPU
Ollama
同一个 prompt下的表现对比:
Qwen3.5-9B(图1)
Prompt eval: 127.52 tok/s
Generation: 34.21 tok/s
2,011 tokens
Total: 59.3s
Qwen3.6-27B(图2)
Prompt eval: 40.13 tok/s
Generation: 9.98 tok/s
6,103 tokens
Total: 10m 13s
测试的结果不支持最初的理想情况。
27B 确实可以非常轻松地装进 64GB unified memory,但 generation speed 只有 9B 的约 29%。
而且这次 27B 默认生成了大量 reasoning tokens。
于是「更大的模型 + 更慢的 tok/s + 更长的 reasoning」叠加起来,一个相同的任务,从约 1 分钟变成了 10 分钟。
期待未来的 1B–7B,能做到今天 20B、30B 模型的大部分事情。
但目前差距还有点远。


再私享一波
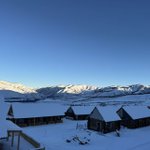
去年冬天刚开板的时候,去的喀纳斯
研究了一番之后,担心暴雪堵路上,决定绕开阿勒泰进入喀纳斯的公路,从布尔津——白哈巴从后包抄。
果然一路顺畅,一路仿佛置身仙境
当时在白哈巴住过的小院,这两天大约 1100 一晚,当时大概两三百吧
不禁回忆起当时,整个村子几乎见不到人。木屋和小路覆着厚厚的雪,远处是连绵的山,近处只有间歇的狗吠声,天地间安静得听得见心跳。
附图就是我在窗台前拍下的照片,能看到金色的晨光一点点漫过雪山,沿着山坡缓缓铺开,再逐渐照进村落。屋顶和雪地还留着淡蓝色的阴影,光却慢慢走近。
后来都会常常想起那个清晨。想起那一刻的平静与感动,是世俗愿望的满足难以替代的瞬间


easy to use

Considering what ChatGPT is doing...
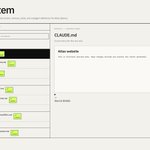
Just shipped Cockpit v0.4 ✨
Claude Code joins Codex and Hermes in a local, read-only dashboard.
Browse saved conversations, project instructions, memory, and files—all in one place.
It's for Developer preview. Claude Code users: I’d love your feedback!
github.com/swen-chan/cockpit…
是谁说 AI 需求到头了?


Hi,
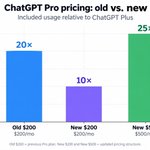
Tomorrow we are re-opening the Pro $200 subscriptions to new subscribers, but together with it we are also changing how we calculate the usage for it. In effect, if you do the math, it will net out at half the dollar in API spend compared to the old Pro $200 plan.
Now that it's said, let me explain why this is happening and why you will still get more work done than if you were on the Pro $200 subscription one month ago.
(a) We didn't want to compromise in other ways and are committing to not reintroducing the 5h limit, so that you can fully use the weekly usage when you want.
(b) On the subscription, we guarantee that over time you always get more work done and with an increasing level of quality. This means that you will continue to get more value per dollar spent as a result of models getting more efficient and us passing down the improvements in the form of API price reductions.
(c) We don't want to put an incentive on ourselves to artificially inflate the API list prices to make it look like you are getting a lot (and workaround it through discounts, etc). Instead we want to continue to both rapidly reduce prices and increase capabilities of models on the API. This week we introduced GPT-6 Sol and GPT-6 Luna at 50% of their previous price. Over time, we see prices go low enough that it makes sense for most to buy usage as needed without there being a significant gap between what you get in a subscription and what you get in the API for a dollar spent.
(d) Tomorrow, we are adding more things to the subscription that won't draw on the usage, I won't reveal what that is yet.
I wanted to be transparent before all the big announcements tomorrow. Lots of new exciting things are coming to the subscriptions that will make it super compelling, but I wanted to make sure to share this change ahead of time so you can all understand it before we shower you with good news.
Codexingly,
Tibo

仅限于有意思,没什么用


一个蛮有意思的量化因子,叫做量价结构变化反转因子(Price-Volume Structure Shift Reversal Factor)(下面会放测试图)
逻辑也很直觉:当价格与成交量之间的关系(例如高价与成交量的相关性)在短时间内出现明显变化时,往往代表市场内部的资金行为正在发生转折。原本稳定的量价结构一旦被打破,背后通常意味着主导市场的力量正在切换
同时,我们再引入价格本身的波动性(例如过去一段时间收盘价的标准差)进行排序,去衡量当前市场的不稳定程度。当价格波动较高、且量价结构正在快速改变时,市场更容易出现情绪主导的错误定价
因子公式如下:
(-1*(DELTA(CORR(HIGH,VOLUME,5),5)*RANK(STD(CLOSE,20))))
本质上是在捕捉市场在「量价结构突变」与「波动放大」共振下的非理性行为,以及由此带来的短期反转机会
两行源代码跑完整回测,大家可以去测试看看
github.com/eliasswu/Alphapur…


看到地铁里面无聊且 useless 的安检实习生们,突然想到了一个绝妙的解决大学生失业的好办法:
所有年营业额超过 10 万的店铺、商场及经营机构,必须强制配备标准安检仪器和两名安检人员(三班倒,共 6 人)


