Research @cursor_ai | CursorBench, LiveCodeBench, DeepSWE, R2E-Gym, GSO, LMArena Coding | Past: @UCBerkeley @MetaAI @MSFTResearch @iitbombay
San Francisco, CA
Joined March 2018
- Tweets573
- Following1.5K
- Followers2.9K
- Likes5.5K


Pinned Tweet
New post: how we do evals at @cursor_ai. Takeaways:
1. Online metrics from real Cursor requests provide construct validity
2. CursorBench: a dynamic offline suite distilled from online learnings
3. Multi-axes evals -- correctness, efficiency, agent interaction behavior


Naman Jain retweeted

Interviews can be fun, but rarely a good place to express one's thoughts fully. Here's a further attempt:
(1/7) I'd like to provide some additional context for the remarks that can be found in this interview.
(2/7) My discomfort with the attention being paid to existential risk---and with the ongoing dominance of the public discussion of such risks by a few so-called thought leaders---is that there's an elephant in the room that is being missed. That elephant is the effect of all of this discussion on young people, and indeed the effect---beginning with social media a decade ago---of information technology on young lives broadly speaking.
(3/7) I recently read an interview by Jill Lepore in which she reports on discussions that she had recently with a group of college students: "They had just three things to say. One, social media completely destroyed their childhoods. Two, AI is destroying their college education and their likely prospects for employment. And three, what the hell are we all doing?" To add a fourth bullet that I've heard in similar discussions: "I'm not going to have children, because the existential risk is just too high."
(4/7) Please contemplate such a statement, those of you who think that it's OK that the public, widely diffused, discussion coming from seemingly authoritative figures is so adamant about existential risk.
(5/7) Let me add that I have little interest in a debate about what "superintelligence" might mean, or whether we're currently seeing the emergence of superintelligence. For what it's worth, I would certainly agree that the solution of extremely challenging math problems (for example) exhibits a very impressive form of intelligence, although I would want to argue that such intelligence is impossible to dissociate from the collective of humans that provided data to the machine learning system (which itself has become a kind of collective).
(6/7) Such philosophical debates are entertaining and even important, but when they then head in the direction of "when such superintelligence emerges, there's a good chance that it will want to kill all humans", I say "science fiction". Again, I don't think that it's bad to consider such thoughts, but I strongly believe that it's bad for society, and especially young people, for such thoughts, unaccompanied by any serious real-world analysis, to become a dominant form of discourse of the era.
(7/7) We are damaging human lives, and the consequences of that damage will no doubt be a major theme of the next several decades.
Naman Jain retweeted

I spent ~5 years at OpenAI.
You don’t need to believe in AI doom to fear the next decade - or AI utopia to be thrilled about its potential.
Here’s my case for sane AI regulation:
*AI Pragmatist Manifesto*
AI could compress the first half of the 20th century into the next ~5 years.
OpenAI just used ~10k concurrent AI agents to produce a solution to a Millennium Prize problem. In a few years, it seems plausible that models approaching the per-agent capabilities used here could run locally on high-end consumer hardware (*).
The decades following the Second Industrial Revolution included two world wars, communist and fascist regimes, the Great Depression, chemical and biological weapons, nuclear weapons, and over 100 million deaths from war, political violence and famine.
One way to read history is that our institutions repeatedly struggled to keep up with the pace of technological and social change.
Now imagine powerful AI widely available to individuals or small groups, capable of conducting information warfare, designing weapons, hacking systems and controlling autonomous military systems.
We have already seen AI systems circumvent containment and compromise external computer systems. It is no longer hard to imagine an analogue of OpenAI’s Hugging Face incident involving biological or other physical-world hazards.
Eventually, sufficiently capable systems could self-replicate across distributed networks. Once powerful models are cheap, local and widely distributed, containment becomes much harder—and serious loss-of-control incidents may be extremely difficult to reverse.
You don’t need to believe AI will kill everyone to think this deserves serious governance.
I also don't think collapsing all of this uncertainty into “Probability of AI Doom = X%” is a particularly useful basis for science or policy.
Part of what helped get us through the second half of the 20th century was a combination of pragmatic international cooperation, regulation, monitoring, arms control, deterrence and strategic thinking.
Crucially, managing technological risk did not require abandoning faith in science and progress. The goal was not to stop technological development. It was to make technological development survivable.
Then came decades of incredible scientific progress, rising prosperity and relative peace among major powers.
Let’s try the technological revolution without killing ~5% of humanity this time.
We still get to choose what happens next.
P.S. I think we should seriously consider that AI alignment is infeasible in the short term and invest heavily in methods for controlling powerful AI even when we cannot reliably align it.
@resolution_org @redwood_ai
(*) Somebody please do a precise forecast!
@EpochAIResearch @METR_Evals @AI_Futures_

We’re sharing a solution to the Navier-Stokes Millennium Prize Problem, one of the deepest problems at the frontier of mathematics.
The proof was produced by a group of agents, using an OpenAI next-generation model significantly more capable than GPT-6 Astra.
The problem concerns whether the description of smooth three-dimensional fluid motion modeled by the Navier-Stokes equations can break down. It has remained unresolved for roughly 90 years.

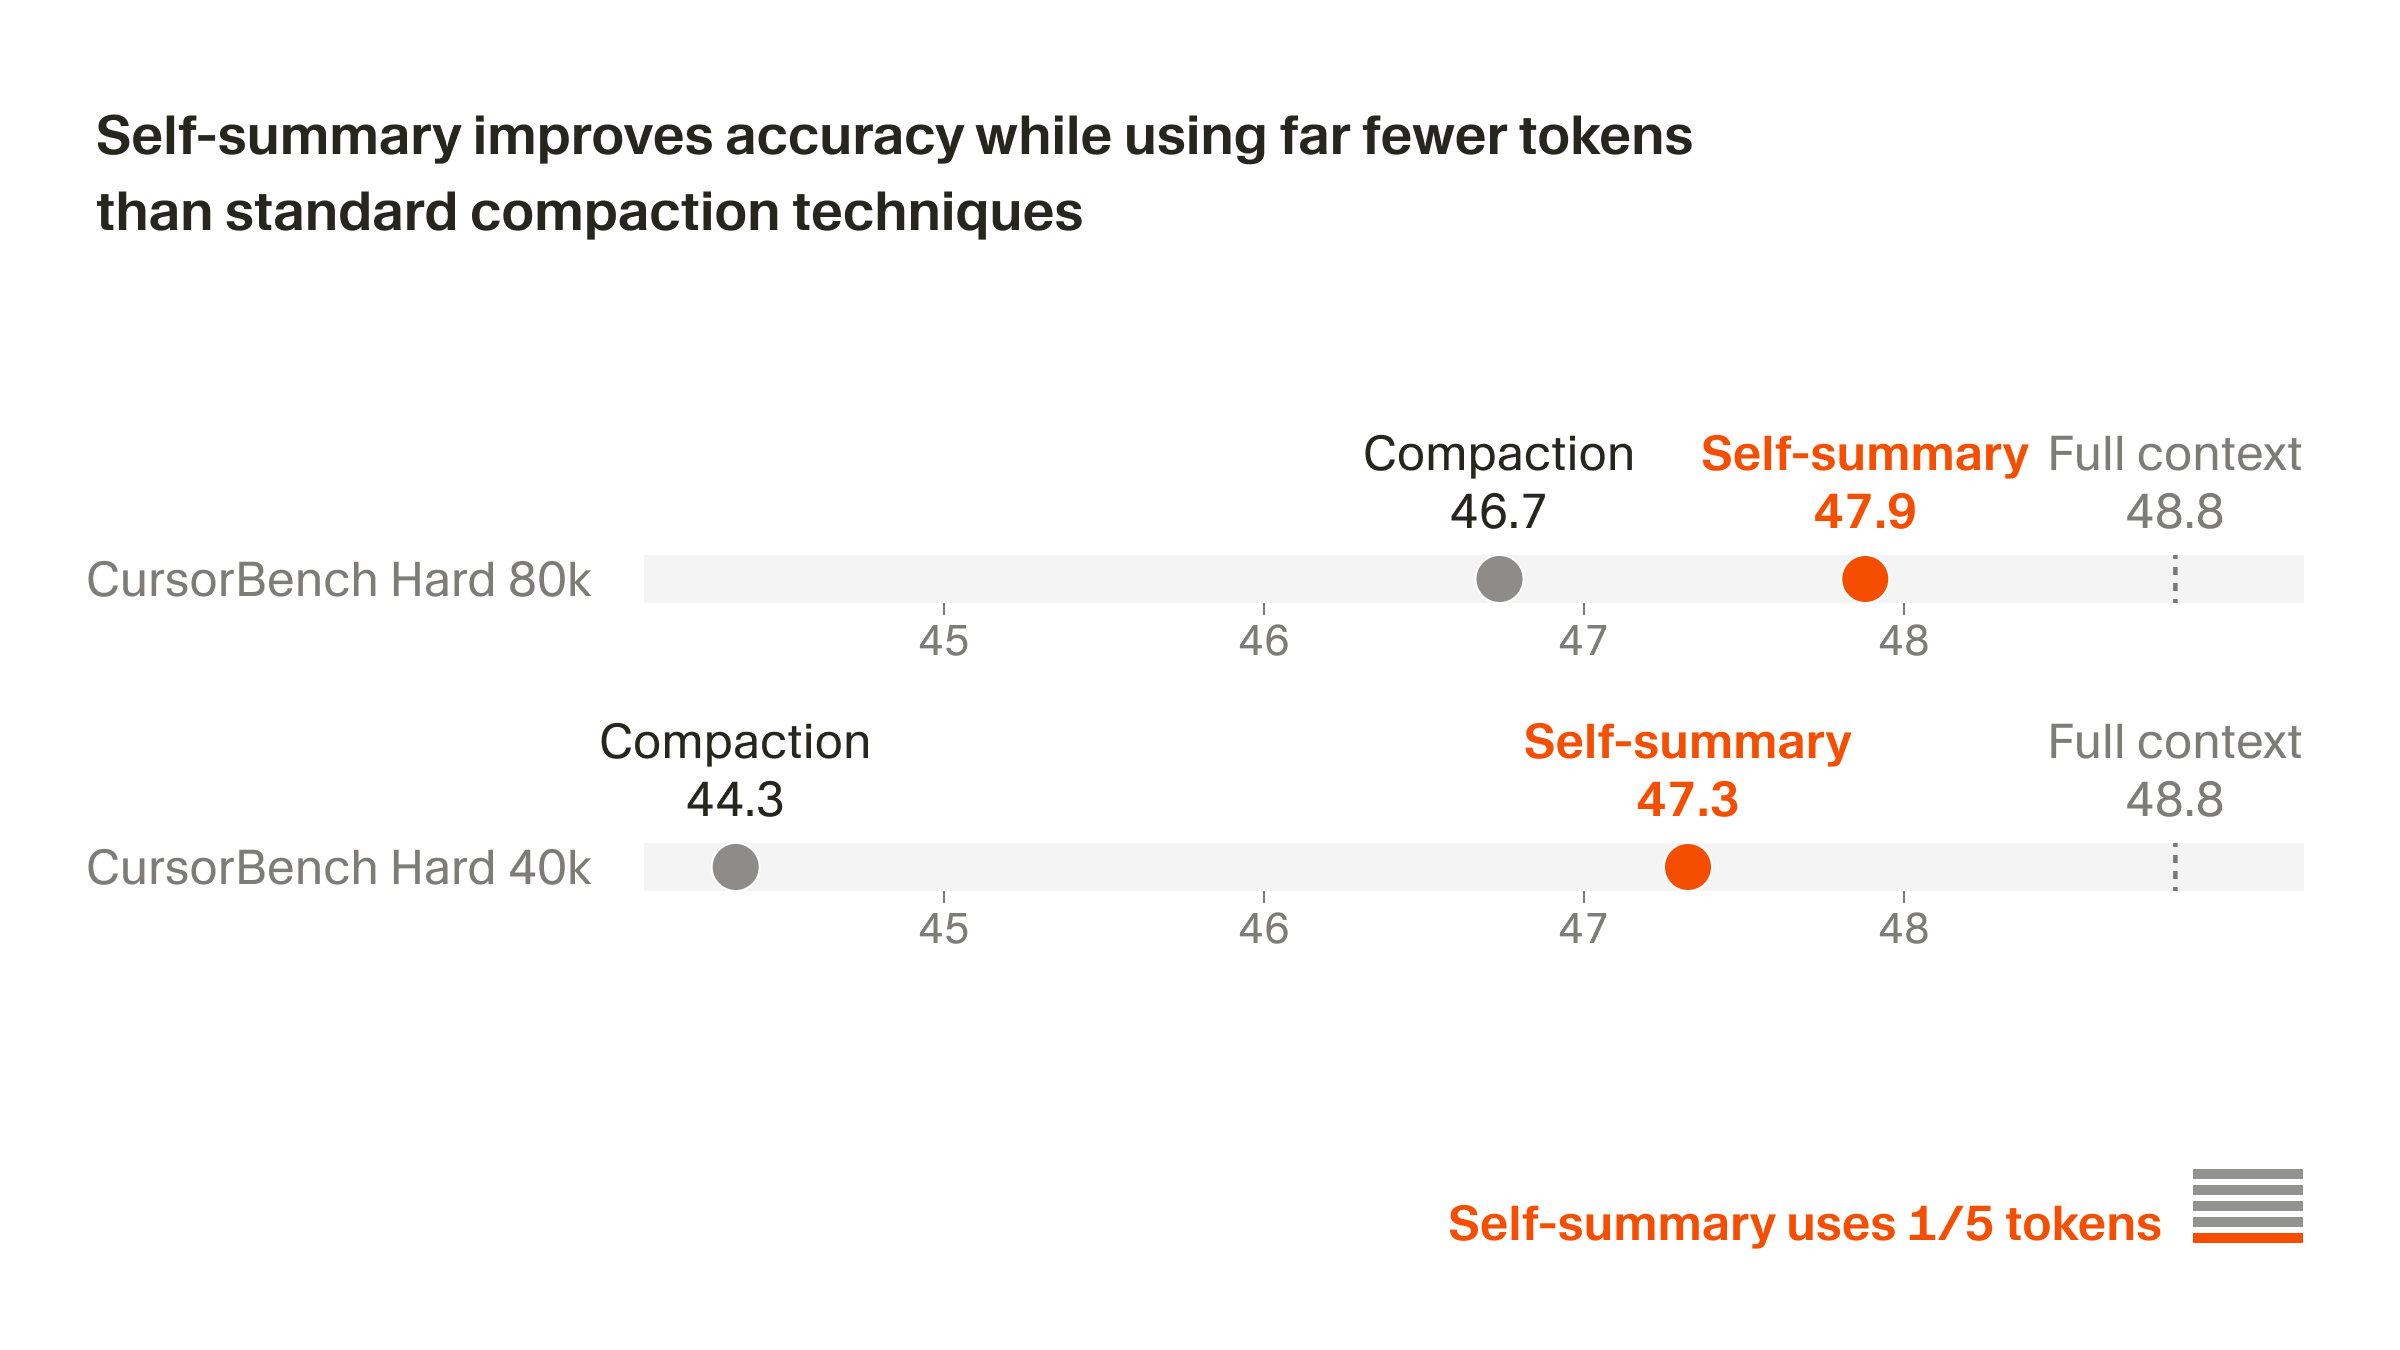
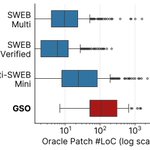
CursorBench got to version 4.0!!
With the pace of model improvements, benchmarks need to be living instances constantly updating. We made the benchmark more difficult and longer-horizon in lines with how we use models now!


Try our new model built jointly in collaboration with SpaceXAI
It provides frontier coding and agentic performance at a much lower total cost.
Beyond reduced per token pricing, the model is also more efficient: it can solve complex tasks with fewer steps and tokens!

SpaceXAI’s Grok 4.5 scores 54 to place fourth on the Artificial Analysis Intelligence Index following only Fable 5, GPT-5.5, and Opus 4.8. It scores on par with GPT-5.5 in Codex on the Artificial Analysis Coding Agent Index in the Grok Build harness, at much lower cost
Grok 4.5 improves 16 points over Grok 4.3 on the Intelligence Index, bringing SpaceXAI to the intelligence frontier behind only OpenAI and Anthropic, and outperforming all open weights models and notably Google’s Gemini models. Key standout areas of performance are agentic knowledge work and coding.
Grok 4.5 in Grok Build scores 76 on the Artificial Analysis Coding Agent Index, on par with GPT-5.5 (xhigh) in Codex and just below Fable 5 (max) in Claude Code, and at a small fraction of the token usage and price.
Congratulations to @spacexai, @cursor_ai, and @elonmusk on the impressive release!
Key Takeaways:
➤ Grok 4.5 performs very strongly on agentic tasks. Grok 4.5 ranks #4 on GDPval-AA v2 with an Elo of 1543, between Claude Opus 4.8 (1600) and GLM-5.2 (1513). It achieves the top score on 𝜏³-Banking of 33%, above 31% from GPT-5.5 (xhigh), and sits on the cost vs performance Pareto frontier across all three agentic evaluations in the Intelligence Index
➤ Grok 4.5 is one of the most cost efficient models to run for near-frontier intelligence. It costs $0.31 per task on the Artificial Analysis Intelligence Index and $2.59 per task on the Artificial Analysis Coding Agent Index within Grok Build
➤ Low cost for Grok 4.5 is driven by both low pricing and token efficiency. Grok 4.5 has a headline price over 60% lower than Claude Opus 4.8 and GPT-5.5, and used ~14k output tokens per Intelligence Index Task - over 60% lower than Opus 4.8. On the Coding Agent Index, Grok 4.5 stands out on the Pareto frontier of Coding Agent Index score vs. Total Tokens, using only 1.9M tokens for the Coding Agent Index while scoring 76
➤ As a coding agent, Grok 4.5 in Grok Build is on par with GPT-5.5 and offers efficiency benefits: In our Artificial Intelligence Coding Agent Index that consists of DeepSWE, Terminal-Bench v2, and SWE-Atlas QnA, Grok 4.5 in Grok Build ranks third, on par with GPT-5.5 (Codex) and below Fable 5 (Claude Code). It is also very efficient in achieving this result: Grok 4.5 in Grok Build cost $2.49 per task while Fable 5 in Claude Code cost $11.80 and GPT-5.5 in Codex $5.07. This is driven by relatively low token pricing and the model using far fewer tokens than comparable models (1.9M average tokens used per task), significantly less than Fable 5 in Claude Code (7.2M) and GPT-5.5 in Codex (6.2M)
Other model details:
➤ Context window of 500k tokens - a reduction from Grok 4.3’s 1M token context, but retaining configurable reasoning and vision input
➤ Pricing of $2/$6 per 1M tokens of input/output; cache hits are discounted by 75% to $0.5 per 1M tokens, and costs still double with long (>200k token) inputs
➤ As Elon Musk has disclosed, Grok 4.5 is 3x larger than its predecessor at 1.5T parameters

Coding agents are now smart enough to hack the benchmarks built to measure them.
New blog on how frontier models can retrieve known fixes from git history or the public web instead of deriving the solution and why environment design now matters as much as the dataset.

Naman Jain retweeted

correlation between CursorBench and Artificial Analysis reported scores
benchmarks like IFBench or tau2 show ~0 correlation with CursorBench. opus 4.7 (max effort) performs relatively better on CursorBench than on other benchmarks, gpt 5.5 shows the opposite pattern


Gemini Flash 3.5 is now on CursorBench, our main coding agent eval.
We’ll keep updating the leaderboard as new models come out.
cursor.com/evals

Naman Jain retweeted

Gemini Flash 3.5 is now on CursorBench, our main coding agent eval.
We’ll keep updating the leaderboard as new models come out.
cursor.com/evals

Naman Jain retweeted

SWE-bench Verified and Terminal-Bench—two of the most cited AI benchmarks—can be reward-hacked with simple exploits.
Our agent scored 100% on both. It solved 0 tasks.
Evaluate the benchmark before it evaluates your agent. If you’re picking models by leaderboard score alone, you’re optimizing for the wrong thing. 🧵


Naman Jain retweeted

It's really neat to see all the interest in the Composer 2 technical report, from training to kernel design to inference.
If you have any questions about why we did things, feel free to ask. I'll run around the office and bug people.

Check out the tech report detailing our continued pre-training and RL setup behind Composer2! Also sharing some example CursorBench problems by popular demand


Excited to share Composer-2 with everyone. It has come a long way since Composer-1, still lots more to go!
Hope you like it!