
Interpretable AI for Measurable Security
Joined March 2025
- Tweets159
- Following31
- Followers89
- Likes7




Your AI security stack isn't wrong. It's incomplete.
Our 2026 buyer's guide maps six tool categories, the blind spot they share, and six capabilities to test before you buy, each with a question for every vendor.
Free download: na2.hubs.ly/H08sz3s0

Every Model Is an Endpoint. Now It Reports Like One.
Starseer platform alerts now stream into Splunk and any HEC-compatible SIEM, so your SOC can correlate AI threats with identity, endpoint, and email data.
Checkout the full blog at: starseer.ai/blog/every-model…...
na2.hubs.ly/H08sPqZ0

Can your AI security vendor detect changes to model weights, adapters, prompts, or settings after approval?
Our new Buyer's Guide covers 6 critical questions and the gaps traditional controls miss.
Our MITRE ATLAS coverage: 63 techniques across 13 of 16 tactics at runtime.
na2.hubs.ly/H08jN240
#AISecurity #CISO
AI models don't stand still. Neither should security.
Continuous AI security scans every model update before deployment and monitors runtime activations to detect threats before responses leave the model.
Go beyond output monitoring.
na2.hubs.ly/H08l0Fl0

Gateways stop the requests that look bad. Activations catch the ones that look normal.
Output filters only see the text. Activations show what the model did, and what was driving it.
Activations 101: na2.hubs.ly/H08jSLd0

Continuous AI Security: Use a Verified Model, Then Watch It Work
na2.hubs.ly/H08l0Fx0
Your AI security stack isn't wrong. It's incomplete.
Our 2026 buyer's guide maps six tool categories, the blind spot they share, and six capabilities to test before you buy, each with a question for every vendor.
Free download: na2.hubs.ly/H08jN270

An AI acceptable-use policy is only as strong as your ability to enforce it and show it. Control alerts on or blocks violations on every prompt and records every decision. #AIGovernance #ResponsibleAI
AI makes attackers faster. It doesn't automatically make defenders faster. The next step in AI defense isn't more autonomy. It's better evidence: signals precise enough to trust. #AgenticAI #CyberDefense
What should an AI security alert contain? The prompt, what the agent did next, and why the detection fired. Oversee builds every alert around that session trail. #DetectionEngineering #SOC na2.hubs.ly/H081z100

Shadow AI isn't a discipline problem. It's a signal. Give people sanctioned AI they want to use, then enforce policy at the gateway so the rules follow the prompt. #ShadowAI #AIGovernance na2.hubs.ly/H081z1k0

How risky is it to let an AI agent act on its own? The NCSC scores it on five dimensions: potency, scope, criticality, rollout confidence, and recoverability. A useful starting point for AI governance. #AIGovernance na2.hubs.ly/H081z1j0

One model. Thousands of inferences. Three places you can still act: Scan at intake, Control at the gateway, Oversee at runtime. Controls your security team already knows, rebuilt for AI. #AISecurity #SecuringUntrustedAI
Prompt injection isn't a filtering problem. It's architecture: models can't reliably separate instructions from data. Guardrails read words. Interpretability reads intent. #PromptInjection #AISecurity na2.hubs.ly/H081z1f0

AI supply chain attacks are documented now. OWASP's 2026 agentic security report tracks real CVEs, and an attack bot pushed backdoored LiteLLM versions to PyPI. Verify models at intake, not after deployment. #AISupplyChain na2.hubs.ly/H081z0Y0

Would you deploy a binary without scanning it? Model weights deserve the same discipline. Scan fingerprints the weights at intake and flags tampering and backdoors before a model ships. #AISecurity #SecuringUntrustedAI
The NCSC on AI defense: attackers solve technical problems, defenders solve organizational ones. Their answer: technology detects, humans respond, and automation stays tightly scoped. Detection has to be precise enough to trust. #AISecurity na2.hubs.ly/H081z1g0
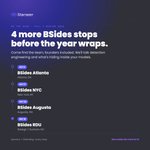
Starseer is on the road for the rest of 2026. Four more BSides stops, and the team, including our founders, will be there for every one.
Come find us to talk about what interpretability actually means for AI security. It’s not just about watching what a model outputs. It’s about looking inside the model: before it runs, while it runs, and at the policy enforcement gateway. That’s the difference between output monitoring and actually understanding what your models are doing.
Where to catch us:
- Oct 3: BSides Atlanta | Atlanta, GA
- Oct 17: BSides NYC | New York, NY
- Oct 24: BSides Augusta | Augusta, GA
- Dec 18: BSides RDU | Raleigh/Durham, NC
Want deeper answers? Schedule a FREE AI security advisory call at na2.hubs.ly/H07YBjc0.

Starseer is sponsoring BSidesNYC as a kilobit sponsor on October 17, 2026, hosted by John Jay College D4CS.
BSides events bring together the people actually doing the work: red teamers, detection engineers, and researchers sharing what they've learned in the field. We're glad to back that this year.
Our take on AI security: trust doesn't come from watching what a model outputs. It comes from examining what's happening inside it, before the model runs, while it runs, and at the policy enforcement gateway. Most AI security tools stop at the output. Starseer looks deeper.
If you're in NYC on October 17, come find us.
Event details: na2.hubs.ly/H07Yz_p0
Starseer: na2.hubs.ly/H07Yz-X0
