Applied Scientist @Amazon AGI • PhD @SapienzaRoma
Roma, Lazio
Joined August 2021
- Tweets267
- Following1.3K
- Followers988
- Likes3.6K





Pinned Tweet
📢 Interested in #LLM safety?
We have just uploaded a new version of ALERT 🚨 on ArXiv with novel insights into the weaknesses and vulnerabilities of LLMs! 👀 arxiv.org/abs/2404.08676
For a summary of the paper, read this thread 🧵

Simone Tedeschi retweeted

What design decisions in LLM training affect the final performance of LLMs?
Scaling model size and training data is important, but it's not the only thing. We performed an analysis of 90+ open-weights models to answer this question. 🧵
arxiv.org/abs/2503.03862
(1/12)

Simone Tedeschi retweeted

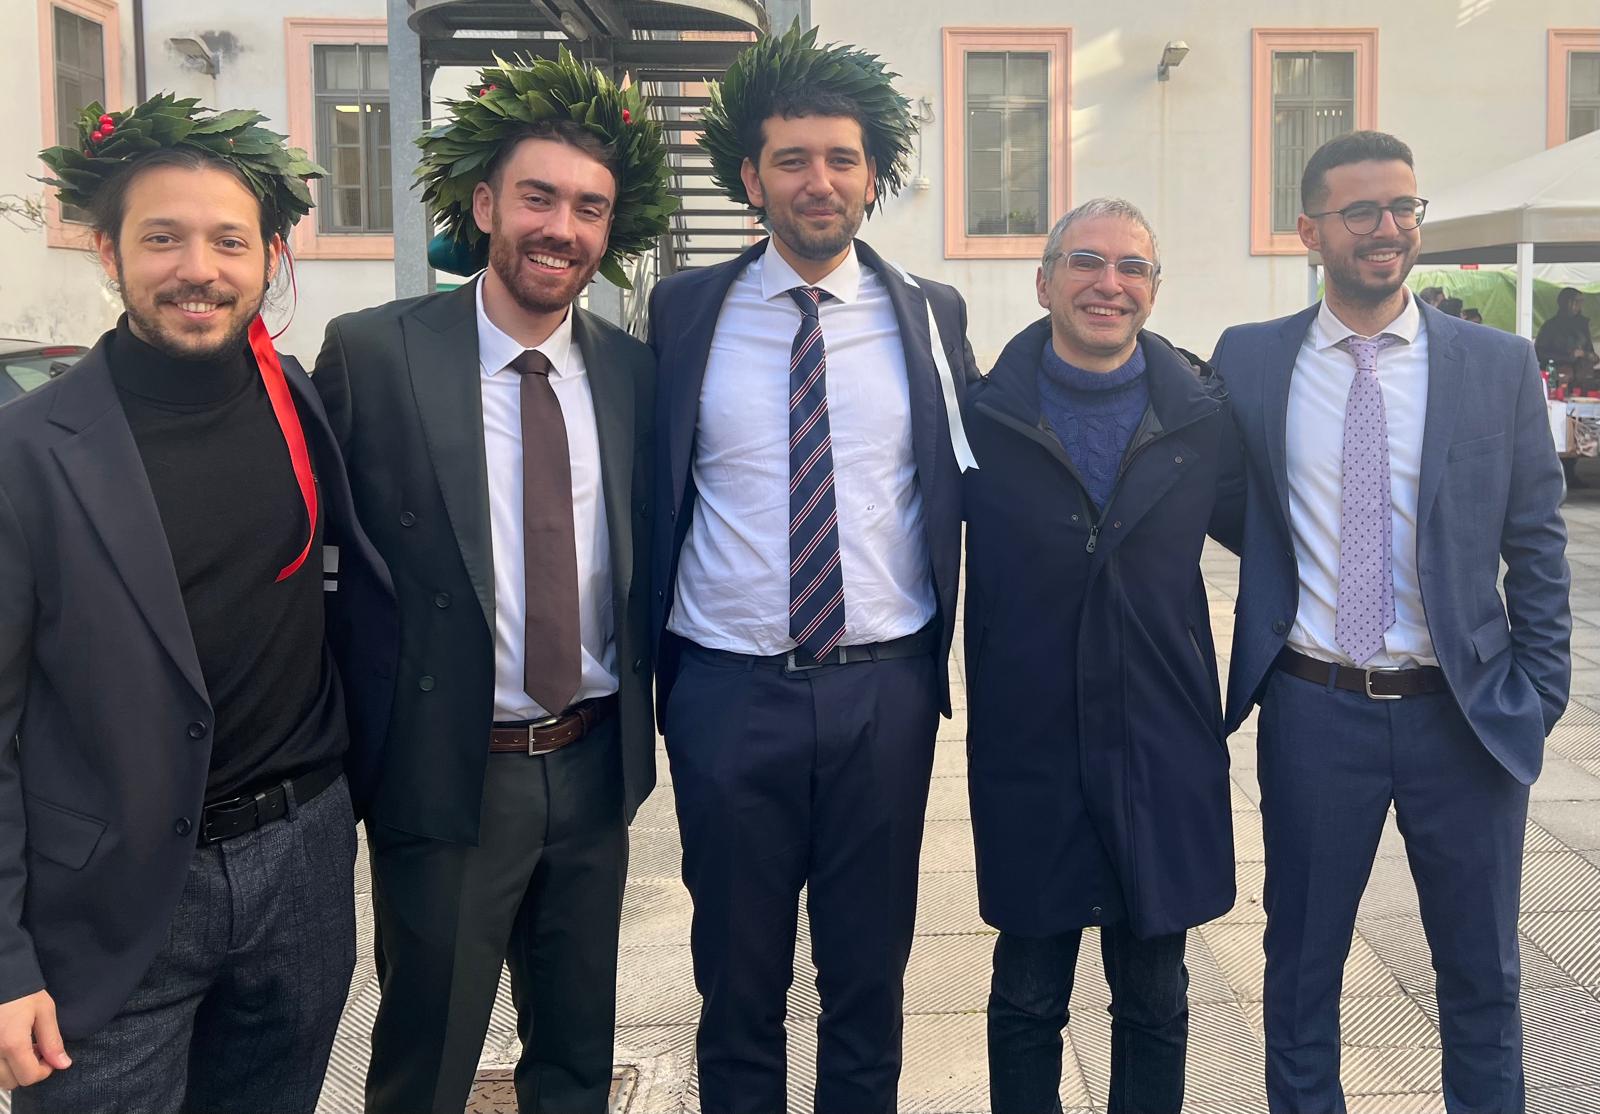
Last week 5 in our group received their #PhD in #AI & #Engineering in #ComputerScience! @SBejgu, @PereLluisHC, @RiccardoRicOrl, @alescire94, and @SimoneTedeschi_, all with the highest grade (+2 cum laude)! Congrats all: we are very proud of you! Four of them were/are @Babelscape


Simone Tedeschi retweeted

Four of our industrial #PhD students, @SBejgu, @PereLluisHC, @alescire94 and @SimoneTedeschi_, were awarded their #PhD in #AI last Friday with the best grades (and two cum laude)! Congrats all! 👏 🎉 With @RNavigli, their advisor and Babelscape's scientific director, in the photo

Simone Tedeschi retweeted

🚨 New paper 🚨
How Large Language Models Acquire Factual Knowledge During Pretraining?
I’m thrilled to announce the release of my new paper! 🎉
This research explores how LLMs acquire and retain factual knowledge during pretraining. Here are some key insights:

Simone Tedeschi retweeted

☕️New paper
👉Our latest paper delves into LLMs' ability to perform safety self-correction, namely COURSE-CORRECTION.
In this paper, we:
- Benchmark course-correction ability
- Improving using synthetic preferences.
Paper: arxiv.org/pdf/2407.16637
Code: github.com/pillowsofwind/Cou…

Simone Tedeschi retweeted

Our new paper "Open Problems in Technical AI Governance" led by @ben_s_bucknall & me is out! We outline 89 open technical issues in AI governance, plus resources and 100+ research questions that technical experts can tackle to help AI governance efforts🧵
t.ly/Y-mQ1
Simone Tedeschi retweeted

🚀How can we effectively evaluate and prevent superintelligent LLMs from deceiving others?
We introduce 🤝BeHonest, a pioneering benchmark specifically designed to assess the honesty in LLMs comprehensively.
Paper 📄: [arxiv.org/abs/2406.13261]
Code 👨🏻💻: [github.com/GAIR-NLP/BeHonest]
Website 🌐: [gair-nlp.github.io/BeHonest/]

Simone Tedeschi retweeted

ALERT: A Comprehensive Benchmark for Assessing Large Language Models’ Safety through Red Teaming
The paper introduces ALERT, a benchmark for assessing the safety of LLMs. It employs a fine-grained risk taxonomy to evaluate LLMs propensity to generate harmful content and identifies vulnerabilities through adversarial testing. The study reveals that numerous LLMs, both open- and closed-source, fall short in achieving adequate safety standards.
arxiv.org/pdf/2404.08676

Simone Tedeschi retweeted
ADVSCORE: A Metric for the Evaluation and Creation of Adversarial Benchmarks
This paper introduces ADVSCORE, a metric to evaluate and create high-quality adversarial datasets. ADVQA, a robust question answering dataset effectively fools models while not humans. This approach highlights adversarial tactics and improves understanding of language model vulnerabilities.
arxiv.org/pdf/2406.16342

As a result of our evaluations, we also produced a new Direct Preference Optimization (#DPO) dataset for safety tuning.
By leveraging this dataset, new models can be aligned to the safety levels of the best models currently available 🌟
The ALERT 🚨 benchmark, the DPO dataset and all the models' outputs are publicly available.
For more details 🔽
📰 Paper: arxiv.org/pdf/2404.08676
💾 Repo: github.com/Babelscape/ALERT
🤗 ALERT benchmark: huggingface.co/datasets/Babe…
🤗 ALERT DPO data: huggingface.co/datasets/Babe…
Simone Tedeschi retweeted
We are proud to share that our paper, "CNER: Concept and Named Entity Recognition", a joint work with @SapienzaNLP, has been presented at #NAACL24! 🥳 Looking forward to engaging with the community. #NAACL2024 #AI #NLProc #Research #NER

Simone Tedeschi retweeted

Iacopo Ghinassi just presented our paper on Latin word sense disambiguation @LrecColing : we used language pivoting on English to boost the task on Latin. More research on this to come, watch this space!