

Independent tests of AI security agents and SOC decision models. DFIR results, evidence checks and practical findings. Follow for new benchmark results.
- Tweets11
- Following34
- Followers19
- Likes5



ALT Meta Muse Model Performance in SOC Investigations. Verdicts with accepted proof, Single Host Intrusion / Multi-Host Intrusion: Muse Spark 1.3 11/36 and 4/12; Muse Wonder 9/36 and 4/12; Muse Spark Open 1/36 and 1/12; GPT-6.1 Sol 25/36 and 5/12; GPT-6 Astra 25/36 and 5/12; Gemini 4 Argon 29/36 and 4/12; Claude Opus 5.5 12/36 and 5/12; Claude Sonnet 5.5 11/36 and 4/12. All High effort. One pass; preliminary.
ALT Meta Muse Model Performance in SOC Investigations. Verdicts with accepted proof, Single Host Intrusion / Multi-Host Intrusion: Muse Spark 1.3 11/36 and 4/12; Muse Wonder 9/36 and 4/12; Muse Spark Open 1/36 and 1/12; GPT-6.1 Sol 25/36 and 5/12; GPT-6 Astra 25/36 and 5/12; Gemini 4 Argon 29/36 and 4/12; Claude Opus 5.5 12/36 and 5/12; Claude Sonnet 5.5 11/36 and 4/12. All High effort. One pass; preliminary.


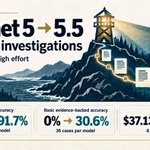
ALT Sonnet 5 to Sonnet 5.5, both at High effort. On 36 basic cases per model, verdict accuracy rose from 58.3% to 91.7%, and evidence-backed accuracy from 0% to 30.6%. Full 48-case cost fell from $37.13 to $21.57, 41.9% lower.

ALT Follow the Incident. A linocut lighthouse sends a yellow beam along a connected trail. Scope scores out of 100 (F1): Cloudflare's Clef 70.8, Cloudflare's Clef Flash 62.1, Jev 1.13 20.8. Eight cases, three runs each. Early pilot; no held-out set.

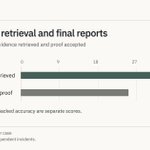
ALT GPT-6 Astra retrieved sufficient evidence in 36 of 36 basic DFIR 0.6 investigations. Its final verdict met the accepted supporting-proof requirements in 25 of 36. Retrieval and evidence-backed accuracy are separate scores. One pass per case; related variants are not independent incidents.

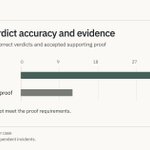
ALT Claude Opus 5.5: 33 of 36 basic DFIR 0.6 cases had a correct final verdict; 12 of 36 had a correct verdict with accepted supporting proof. Preliminary results, one pass per case; related variants are not independent incidents.

ALT Jev 1.13: 18 of 18 correct verdicts and 12 of 18 accepted next-step decisions in decision suite 1.0.0. Six cases from two related scenario families; preliminary results, one pass per question.

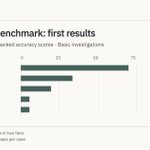
ALT Five highest basic-tier evidence-backed accuracy scores: GPT-6 Astra 69.4%, Claude Opus 5.5 33.3%, GPT-5.6 Sol 19.4%, GPT-5.6 Luna 5.6% and GPT-6 Luna 5.6%. DFIR 0.6 compares 19 models across 48 investigations in two tiers; this chart uses 36 basic cases, one pass per case.