

Scrapling is an adaptive Web Scraping framework that handles everything from a single request to a full-scale crawl by @D4Vinci1 Follow for daily tips & tricks.
Joined April 2025
- Tweets308
- Following1
- Followers1.1K
- Likes911




🕷️ Scrapling tip: follow_redirects="safe" blocks redirects to private IPs. A public URL can point your scraper at localhost with one redirect. Fetcher stops that hop by default, while normal public redirects still work. ⚡

Scrapling 🕷️ retweeted

So what makes Scrapling MCP better than Playwright MCP and other known free MCPs that automate browsers or scrape the web?
Scrapling MCP in v0.5 can achieve the same browser automation as others, but:
- It provides Chainable browser actions. Unlike any other MCP, the agent makes one call to the MCP to take an action in the browser, then thinks, then makes another call for the following action, and so on. In Scrapling, the agent can send a sequence of actions to run in the browser without repeating calls, saving tokens and letting the agent plan ahead.
For example, a website that shows a game to test whether you are human, based on your quick reactions, can be solved this way. The actions cover all waiting conditions, so a sequence can include clicking a button, waiting 5 seconds, ensuring the network is stable, typing in an input field, pressing Enter, waiting for a specific selector to appear, waiting for all JavaScript to execute, and then finishing.
Imagine Scrapling doing all of that for the Agent instead of the agent sending the calls one by one!
- The MCP can see and interact with closed shadow-DOM elements like CAPTCHAs. I don't think this needs explaining, but it means you can rest assured the agent can interact with anything the website throws at you. Previously, you had to give your agent access to computer-use add-ons so it could see the screen and interact with elements like this through coordinates; now it can do it directly through the browser.
- There is a lot of focus on saving tokens! Here, we block ads; let you select elements instead of the whole page for all operations; let you save browser state and repeat it later; and protect against prompt injection better than most tools. For example, we delete all hidden elements and zero-width elements, so we save more tokens while protecting you more!
- Stuff we already had from before:
* We provide a Cloudflare solver that doesn't require AI.
* You can do requests through Scrapling without browsers that fake TLS fingerprints, so you only use browsers when you have to (and with a lot of control).
* Control over what reaches the AI. Extract selected elements as Markdown, HTML, or text. Search page snapshots or read captured API responses. This can reduce unnecessary output.
Other than that, you will find the things that you already see in other tools, like moving and clicking the mouse, using the keyboard and typing slowly, interacting with dropboxes and similar elements, doing drag and drop with the mouse, executing JavaScript on the page, interacting with dialog popups, seeing the requests that are happening in the background and the parts that the Agent is interested in each request, and full control over the type of content returned to the agent to be HTML/Markdown/Text content and so on.
Now tell me, have you tried this update yet, and what do you think? 🔥

🚨 I have just released the Scrapling v0.5 update, and I had to record this!
Here’s Codex using Scrapling MCP to quickly solve hCaptcha, reCAPTCHA, Friendly Captcha, Cloudflare Turnstile, and AWS CAPTCHA 🔥
Watch the video. This is what the new update makes possible. Feel free to cancel your paid subscriptions now; the new Scrapling update enables browser automation for any AI Agent like never before. It pairs perfectly with OpenClaw and Hermes!
It can open a page, inspect it, click, type, run JavaScript, take screenshots, and read network requests and responses. It can perform all browser actions, chain them in one call, and make it look as human as possible while saving tokens.
It can access closed Shadow DOM elements without issues and interact with the website using selectors, references, and coordinates. It can now also save browser state and reload it later so you don't have to repeat anything!
This update also makes it easier than ever to crawl websites automatically from code and convert them to safe Markdown, with filters, crawling strategies (DFS/BFS), and more.
The Cloudflare solver is now faster and more efficient than ever whenever you want to solve it without AI.
This release includes many changes, fixes, and quality-of-life improvements. The website is now translated into 10 languages!
Check it out here and let me know your thoughts: scrapling.readthedocs.io/en/…
🕷️ Scrapling tip: save_state() in v0.5 packs cookies, localStorage and IndexedDB into one Playwright-compatible JSON file. Use load_state() in a fresh browser to restore them. This demo moves an IndexedDB record without copying a browser profile 🎯

🕷️ Scrapling tip: crawl_strategy="dfs" in v0.5 follows new links first, so you can explore a branch before older queued pages. Default "bfs" takes the oldest first. Higher priorities still win. Use concurrent_requests=1 to see the order clearly 🎯

🕷️ Scrapling tip: record_requests=True in v0.5 saves browser network history. Close the browser, then use session.network.search() to read saved API replies as JSON. Choose the URL filter AFTER browsing, with no repeat requests 🎯

🕷️ Scrapling tip: pierce_shadow=True in v0.5 brings open Shadow DOM content into the response. Read it with normal CSS or XPath, including text assigned to slots. No custom JavaScript to walk shadow roots. Closed roots stay out 🎯

Scrapling 🕷️ retweeted
Check out the video on YouTube: youtube.com/watch?v=NHwWEiTO…
Full release notes: github.com/D4Vinci/Scrapling…
Full migration guide on moving to v0.5 translated to 10 languges: scrapling.readthedocs.io/en/…

You can't miss the new update 🔥
🚨 I have just released the Scrapling v0.5 update, and I had to record this!
Here’s Codex using Scrapling MCP to quickly solve hCaptcha, reCAPTCHA, Friendly Captcha, Cloudflare Turnstile, and AWS CAPTCHA 🔥
Watch the video. This is what the new update makes possible. Feel free to cancel your paid subscriptions now; the new Scrapling update enables browser automation for any AI Agent like never before. It pairs perfectly with OpenClaw and Hermes!
It can open a page, inspect it, click, type, run JavaScript, take screenshots, and read network requests and responses. It can perform all browser actions, chain them in one call, and make it look as human as possible while saving tokens.
It can access closed Shadow DOM elements without issues and interact with the website using selectors, references, and coordinates. It can now also save browser state and reload it later so you don't have to repeat anything!
This update also makes it easier than ever to crawl websites automatically from code and convert them to safe Markdown, with filters, crawling strategies (DFS/BFS), and more.
The Cloudflare solver is now faster and more efficient than ever whenever you want to solve it without AI.
This release includes many changes, fixes, and quality-of-life improvements. The website is now translated into 10 languages!
Check it out here and let me know your thoughts: scrapling.readthedocs.io/en/…
🕷️ Scrapling tip: curl2fetcher() replays DevTools "Copy as cURL" requests. Scrapling reads the method, headers, cookies and JSON body for you, then sends the request with Fetcher. Turn a browser API call into Python without rebuilding it by hand ⚡

🕷️ Scrapling tip: LinkExtractor(process=...) cleans URLs BEFORE duplicate removal. Strip utm_* tags so email and social links to the same product collapse into one. Keep size and color params so real variants stay separate. Fewer wasted requests ⚡

🕷️ Scrapling tip: additional_args lets you set the browser's geolocation and grant location access. Scraping a page with a "near me" button? Give it fixed coordinates and read the result. No manual permission clicks or OS changes ⚡

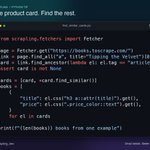
🕷️ Scrapling tip: find_similar() turns one known element into a way to find the rest. Pick one product card, then find others with similar structure and attributes. Add the original back: this demo extracts 20 book titles and prices 🎯

🕷️ Scrapling tip: the adaptive feature can match an old element to new HTML without a database. Pass the old Selector straight to new.relocate(). This demo finds the new price after .price becomes .cost. No save/retrieve setup 🎯

Scrapling 🕷️ retweeted
Last night, someone did 12 PRs within 10 minutes to Scrapling.
First, I blocked him, closed all PRs without reading them, and labeled them all as "AI-Slop". This is not the first time this has happened, and you can't convince me that PRs spanned this quickly were reviewed. From what I have seen so far, they don't.
Now don't get me wrong, I use Fable and Astra a lot to help me manage Scrapling stuff and the development process as a solo maintainer, even with all the help I get from our awesome contributors.
But the question is: how long will we have to deal with those low-quality AI-slop bombs that waste every project maintainer's time?
I see this in nearly every open-source project, and most of it comes from accounts that look like that dude's: hundreds of PRs a month across many known projects and languages, and they call themselves "AI-forward Engineer" or something similar!
Is that the future now, and do we just have to accept it? Low-quality PRs everywhere, as long as you ship fast?
Will @github ever provide an option to block this? I guess we will never know!

Two years ago today, Scrapling was published!
Since then, we have had 6.1M downloads and 87.2k GitHub stars; most of them happened this year since v0.4.
Can't wait to see how v0.5 will be received when we release it in the coming days.
Happy birthday to Scrapling! 🎉


🕷️ Scrapling tip: init_script runs before site JavaScript. Install a JSON.parse hook before the app loads to collect its parsed data. This demo captures 16 film records and reads them straight from Python. 🎯

🕷️ Scrapling tip: solve_cloudflare=True lets StealthyFetcher handle Cloudflare challenges before returning the page. No CAPTCHA service key or checkbox code. Give it timeout=60000 (60s), then parse the result as usual. ⚡

