

Biostatistician - @aberdeenuni - 76 69 65 77 73 20 65 78 70 72 65 73 73 65 64 20 61 72 65 20 6d 79 20 6f 77 6e
Scotland
Joined March 2010
- Tweets3.2K
- Following343
- Followers644
- Likes848


Alex Douglas retweeted
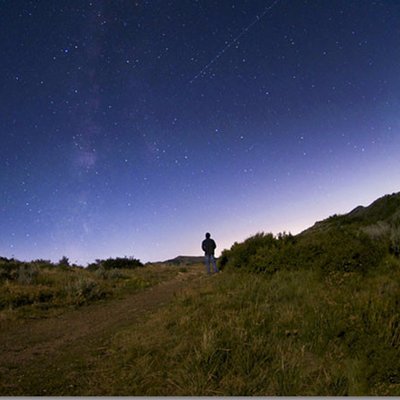
Polish mountaineer scaled his country's highest peak, Rysy, which is 2,499 metres (8,199 feet) high and found a cat.
[📹 Wojtek Jabczyński]
xitter.cf/i/status/1812168760758…
Alex Douglas retweeted

📢PhD position on microbial ecology currently open for applications: " Ecological and evolutionary dynamics of sponge-associated microbial communities" on FindAPhD.com. Please check our website for more info as well: gubry-rangin.com

Alex Douglas retweeted

One of my favorite recent papers is Kane (2024).
While pitched (effectively and usefully) as a paper about compelling null results, many of the action items are ways to boost power.
IMO, it provides a great checklist to make sure you're maximizing power.
CC: @UptonOrwell


Alex Douglas retweeted

"Don’t be steamrollered by clinicians"
Working life for some medical statisticians can feel like playing second fiddle, according to our latest free-to-read article: ow.ly/1ql250S6Mgz
#statistics #freetoread

Alex Douglas retweeted
In @quarto_pub, use these options to fold long code blocks with a custom message:
#| code-fold: true
#| code-summary: "Your message here"
This is particularly useful for code-based blog posts.
See an example here: walker-data.com/posts/shiny-…
#rstats
Alex Douglas retweeted

Statisticians chuckle, but I've seen doctors gleefully log(1+y) and then fit lines through that log-swamp garbage and then get published in The Lancet so who's laughing now
Seriously log(1+y) bad - model the data generating process. An area where ecologists do well actually!

log(0) = {Drop it, Scale it, Reform it, Invert it, Group it, press it, snap it, work it, quick erase it} or maybe what these authors do instead? @dggoldst
academic.oup.com/qje/article…


Alex Douglas retweeted

#rstats PSA: Reminder to all R users on Ubuntu that you can quickly and easily install CRAN binaries with the amazing #r2u from @eddelbuettel. I just had to setup a new Ubuntu 22.04 machine, and it was as easy as
sudo bash add_cranapt_jammy.sh
github.com/eddelbuettel/r2u

Alex Douglas retweeted

(thread)
Old joke about a new VC shared on our committee list: On his first day in office, he finds a letter on his desk from his predecessor and three numbered envelopes. The letter says, 'You will encounter crises in this job. When they arrive, open these letters in turn'
Alex Douglas retweeted

Delighted to announce that in a recent visit to China we have developed a postgraduate training partnership with the Xianghu Lab in Hangzhou where we will share approaches in science to address food security and environmental change @UoABioSci

Alex Douglas retweeted

.
How the Big Five Academic Publishers Profit from Article Processing Charges
Spoiler alert : Their revenue was over US$ 1 billion between 2015-2018
A recent paper looks at the "big 5" publishers (@ElsevierConnect, @Sage_Publishing, @SpringerNature, @tandfonline and @WileyGlobal) and estimates their revenue from Article Processing Charges (APCs).
Here are the messages we took from the paper:
1⃣ Between 2015-2018 it is estimated that authors paid $1.06 in publication fees to these five publishers.
2⃣ Springer-Nature made the most revenue ($588.7 million) followed by Elsevier ($221.4 million), Wiley ($114.3 million), Taylor & Francis ($76.8 million) and Sage ($31.6 million)
3⃣ The data was collected from @Clarivate, @unpaywall, open datasets of APC list prices and historical prices retrieved from @waybackmachine.
4⃣ The APC's used in their calculations were based on those used in the year the paper was published. This is to be applauded. It would have been MUCH easier to take the current APC's but this would over estimate the revenue.
5⃣ To give an example of how the APC's could have been over estimated, a Wiley journal, in 2015 charged $3,000. In 2023, the fee is $4,020. If you used today's fee for a 2015 article the over estimate would be 34%.
6⃣ The number of #OpenAccess articles over the four year period of study (2015-2018) increased from 91,375 articles in 2015 to 153,746 articles in 2018.
7⃣ Over the four-year period studied, it is estimated that Scientific Reports obtained $105.1 million in APC's and Nature Communications obtained $71.1 million. These journals are both published by Springer-Nature.
8⃣ The high income of Scientific Reports can be partly explained by the fact that it published 73,206 articles.
9⃣ Three Springer-Nature journals had the highest average APC's; Diabetes Therapy ($5,478), Infectious Diseases and Therapy ($5,295) and Rheumatology and Therapy ($5,169)
🔟The three countries that paid the largest amounts of APC's were USA, $184.7 million; China, $148.0 million and the UK ($134.6 million)
You can access the article here: doi.org/10.1162/qss_a_00272
Tag: @mitpress | @LeighkButler | @l_matthia | @marcandresim | @philippemongeon | @stefhaustein

Alex Douglas retweeted

“You need 16 times the sample size to estimate an interaction than to estimate a main effect,” explained
statmodeling.stat.columbia.e…
Alex Douglas retweeted
Please RT - Funded #PhD opportunity in my group studying nanoplastic particles and their ecological and evolutionary significance in replicated whole ecosystems. With @Howbeer @TomOMcDonald and Steve Morris @DefraGovUK as case partner. Deadline Jan 8th findaphd.com/phds/project/ec…

Alex Douglas retweeted

I've been writing R code daily for >15 years and just today learned of strrep (base #Rstats)

Alex Douglas retweeted

Statistics 110: Probability by Harvard University.
Inarguably, one of the best probability courses on the web and it's Free!
youtube.com/playlist?list=PL…

Alex Douglas retweeted
IBM is offering 12 Online Coding Courses 🔥🔥
🐍 Python
🧑💻 Data Science
✨ SQL
💽 NoSQL and DBaaS
📈 Statistics
🧠 R Programming
🧙 Data Analytics
🚀 Artificial Intelligence
Open this to not miss your chance 🧵👇
Alex Douglas retweeted
Our paper debunking the 2020 cancer microbiome results is now published, in @mbiojournal. We'll see if @nature (or the authors) will retract these deeply flawed results. h/t @ProfBootyPhD @EricTopol journals.asm.org/doi/10.1128…
Alex Douglas retweeted

Those damn outliers
We talk about them a lot, but are they really that harmful?
Let's explore them visually 👇
By definition, outliers are data points that are very different from most of the data.
We sometimes call them extreme values.
But how do you define 'very different'?
There is no exact measure to tell which data is extreme.
Sometimes outliers are invalid data or errors, but they can also be the focus of analysis. (Anomaly detection)
Do you feel confused?
You should, because this is a territory of data science where no one can tell you the universal truth. Cause there is no such thing.
Outliers must be defined during the analysis with some domain knowledge. What is an outlier in Finance can be an important value in Medicine.
They have a big impact on analysis, especially when it comes to measures like the mean. Thus, it is important to identify them in every project.
But some good news
With visualizations, we can easily spot outliers!
Below you can find the scatterplot of the connection between X and Y. On this scatter, 3 data points got lost. They are probably outliers.
I also added two raincloud plots not just because they are fancy.
Look at the plot for X, if you only observe this chart you will never find those 3 points.
When you look at Y, they will show themselves. That's why we need to include different angles and points of view in our analysis!
Be careful, those damn outliers are all around us!
___
I hope you've found this Tweet helpful.
In this series, I share my notes from the book Practical Statistics for Data Scientists by Peter Bruce, Andrew Bruce, and Peter Gedeck.
Like/Retweet for support and follow @levikul09 for more Data Science content.
Thanks 😉

Alex Douglas retweeted

Comparison of 6 DNA extraction methods for isolation of high yield of high molecular weight DNA suitable for shotgun metagenomics Nanopore sequencing to detect bacteria. #DNAextraction #HMW_DNA #Metagenomics @nanopore #Sequencing #BMCgenomics
bmcgenomics.biomedcentral.co…