

I build to understand. Messy company data → software people own. Solo builder · agent orchestration · MLcon speaker. Building SKatalyst AI in public.
Germany | Building globally
Joined June 2026
- Tweets8.5K
- Following1.3K
- Followers2.4K
- Likes8.5K




Pinned Tweet
28 Claude Code agents running in parallel for 2 hours.
Opus 5.5, High effort, Max plan.
Usage? 7%!
Everyone's been saying the limits got nerfed. I felt the opposite these last two days!
Anyone else seeing this?
I challenged Claude Code, Cursor and Codex to create "The Last Streetlight", a Pixar-inspired short about a robot, a cat and a rainy city.
No external assets. No libraries. Just code.
Here are the results, side by side:
> Claude Code + Opus 5.5
85 KB HTML | 77 sec | 4.5–6/10
> Cursor + Muse Wonder
32 KB HTML | 60 sec | 6.2/10
> Codex + Astra
25 KB HTML | 60 sec | 6.8/10
Each system built its own film, ran 3 rounds of director-style criticism and tried to fix its mistakes.
The scores are their own self-critiques, not an independent benchmark
Muse Wonder gave Claude's short film 4.5/10.
So I made it direct its own!
Same story. 32 KB vs Claude's 85 KB.
Its own first round: 2/10 "Eight of ten frames were empty staircase towers"
Final score after 3 rounds: 6.2/10.
Turns out critiquing is easier than directing Who did it better?
Claude's critic agents rated its own short film 4.5–6/10.
I didn't trust it, so I asked two other AIs.
Astra: 5/10 and Muse Wonder: 4.5/10!
Three models, same verdict: "polished motion graphics, not Pixar."
My favorite note: "You've given prime screen space to a ventilation grille when I want wonder" 😭
Turns out Claude didn't go easy on itself. Would you score it higher?


Claude rated its own short film 6/10!
"Polished motion graphics, not Pixar"
The whole film is an 85 KB HTML file. No assets, no libraries, sound included.
Built with Claude Code + Opus 5.5 in 47 minutes, with a critic agent roasting every scene 3 times!
Would you give it more?
This entire rainy neon city is a 52 KB HTML file!
where no game engine no libraries, Just WebGPU
Built with Claude Code + Opus 5.5 in 40 minutes.
The trick: Claude screenshotted its own work and a fresh critic agent roasted it 3 times, taking it from 2/10 to a moody rainy night.
This was one prompt and 3 rounds of AI self-critique. Should I try building a full animated scene next?

The prompt I used:
"Build a single self-contained HTML file under 100 KB, no libraries: [a WebGPU night city in the rain / an aurora over mountains / a lava lamp]. After each version, render a screenshot in headless Chrome, have a separate subagent critique it, and fix the issues. Repeat 3 times."
🚨 OpenCode has confirmed a security breach affecting 1.4% of its Console users.
The concern? API keys linked to Anthropic, OpenAI, and Google may have been exposed.
Some users are reporting unexpected API charges, including one reported $400 incident.
If you've connected your own API keys to OpenCode Console:
>Revoke and rotate potentially exposed keys
>Check your provider usage and billing
>Review spending limits and alerts
>Remove old keys you're no longer using
This is also a reminder for anyone building with AI coding agents:
Your API key isn't just a password, It's access to your account's paid compute.
One forgotten credential can become an expensive security incident.
When was the last time you audited your AI provider keys apparently, we need to do it more often than we think!

We had a security breach last night related to a large scale distillation attack that impacted 1.4% of OpenCode Console users
We have notified them all this morning via email. If you did not get an email you were not impacted, it was a subset of users who had external providers linked
The incident is ongoing so we cannot share more details at this point but we are working with Anthropic, OpenAI, and Google to remediate
X announces $5,000 for videos and suddenly my timeline turns into TikTok 😭That was FAST😂
Three frontier AI companies announced speed or efficiency improvements. So I timed one practical research task across Grok Bot, Codex and Claude Code.
Same prompt: find 5 startup credit programmes for a bootstrapped German AI startup. Official sources, eligibility, realistic amounts not just headline offers.
My timings:
>Grok Bot: 1m 01s
>Codex · Astra Medium: 2m 00s
>Claude Code · Opus 5.5 Medium: 5m 16s
Grok finished first with a useful shortlist.
Codex took another 59 seconds and explicitly flagged conflicting Microsoft credit documentation! that detail matters when you’re deciding what to apply for.
Claude spent longer screening additional programmes and explaining exclusions. Useful detail, but I didn’t see a clear enough quality gain to justify the extra wait on this task.
My takeaway:
Speed winner → Grok
Best balance in this run → Codex
Well, that was an unexpected comeback! 🔥
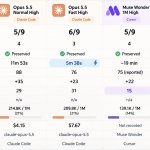
After testing Claude Opus 5.5 Normal and Fast Mode, I decided to give Muse Wonder 1M High a shot in Cursor.
Same repository. Same prompt. Same 9 hidden defects. No hints and 3 runs.
Muse Wonder High:
>~19 minutes
>5/9 defect signatures changed
>75 tests reported passing
>GT-10 restraint preserved
Honestly, I expected more.
So I thought, why not give Fable 5.1 another chance?
And it did NOT disappoint!
Fable 5.1:
>9/9 defect signatures changed!
>GT-10 restraint preserved
>0/9 original defect signatures remaining
For comparison, today's results:
• Opus 5.5 Normal High: 5/9
• Opus 5.5 Fast High: 6/9
• Muse Wonder High: 5/9
• Fable 5.1: 9/9 🏆
Same benchmark, very different outcomes! are we underestimating Fable?

For those questioning the AI coding benchmarks I've been sharing, let me clarify something!
I know a single prompt or a single run isn't enough to judge a model's performance.
AI agents are nondeterministic and results vary between runs, and prompts, configurations, and environments can influence outcomes.
That's exactly why I built an independent evaluation pipeline instead of trusting what an agent claims it fixed.
Here's how it works:
1-Controlled baseline: A repository with 9 deliberately planted defects and GT-10, a restraint check for functionality that must remain untouched.
2-Blind challenge: Every agent receives a fresh copy of the same repository and the same open-ended prompt. No hints about the hidden defects.
3-Independent ground truth: An external script checks which defect signatures changed, which remain, and whether GT-10 was preserved.
4-Behavioral testing: The benchmark includes executable tests covering billing integrity, tenant isolation, and other application behavior. I'm also strengthening the evaluator with dedicated concurrency, transaction rollback, and failure-scenario checks.
5-Quantitative measurements: I record passing tests, files changed, execution time, context consumption, and cost.
6-Repeated experiments: I compare multiple models and runs to study consistency, not just individual outcomes.
7-Harness and environment considerations: I also account for the coding harness (Claude Code, Cursor, Gemini CLI), available tools, MCP integrations, loaded skills, context-window size, reasoning effort, and initial context. These factors can influence how an agent behaves, even when the underlying model is the same. I document differences and aim to control them when making direct comparisons.
An important distinction: A changed defect signature is not automatically proof of a correct fix. That's why I report signature-based findings separately from behavioral test results and yes, more repetitions are needed before drawing statistically meaningful conclusions.
My goal isn't to crown a winner based on one run.
It's to measure how reliably coding agents identify defects, implement correct fixes, preserve existing behavior, and recognize when software is genuinely ready to ship because "I fixed everything" is an agent's claim, not an evaluation result!
I hope is clear for everyone!
🚨Muse Wonder just showed up in Cursor!
And it's not just one configuration:
>Multiple reasoning effort levels available
>Choose between 300K or 1M context windows
You can select the effort and context size yourself.
Let's see whether Muse Wonder can outperform the others!
Anyone already tested it? First impressions?

Claude Opus 5.5 Fast Mode vs Normal Mode!
same repo, same challenge, High effort.
I ran both through Claude Code to see whether Fast Mode actually improves long autonomous coding sessions.
>Fast Mode finished 2.1× faster and changed one more defect signature, at 1.85× the cost.
>Interestingly, Normal Mode added 12 more tests, while Fast Mode touched more existing files.
Both still declared the repository ready to ship despite unresolved hidden checks.
My biggest takeaway: faster inference can change the agent's execution path, not just its completion time.
My question is whether the time saved justifies the extra cost, and whether the results hold across repeated runs.
Full side-by-side comparison in the video!


Clarification on Claude Code Fast Mode!
If you want to use Fast Mode, there are two different paths:
1-Through your Claude subscription (Pro/Max/Team)
You need to enable Usage Credits / Extra Usage and add funds. Fast Mode consumes those credits at a higher rate. It is NOT deducted from your regular subscription allowance or separate API credits.
2-Through your Anthropic API key
Fast Mode must be enabled in your organization's Claude Code settings but that's not enough! Console/API organizations also need separate research-preview access from Anthropic.
If you don't have an account manager, join the official waitlist: claude.com/fast-mode