

scientific computing, data science, Python enthusiast, instructor @dutc_training
Sacramento, CA
Joined December 2021
- Tweets424
- Following374
- Followers724
- Likes774





Pinned Tweet
Been working on some visualizations in @matplotlib to highlight statistical concepts. This one intends to demonstrate (via simulation) the Central Limit Theorem: the sampling distribution of the mean is gaussian if given a large enough sample size regardless* of the population.

Cameron Riddell retweeted

Check out "What we learned applying Diataxis to HoloViz libraries" by @MaximeLiquet meetup.doepy.org/past.html.
Thanks to @RiddleMeCam for the invitation.
#Python #Diataxis

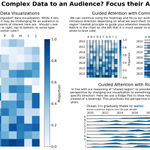
Recently held a dataviz session for @theAGU, part of their annual data viz competition for students agu.org/honors/freilich. The viz were great, but they often lacked focus for an audience to quickly understand what was going on.
(link below for the code & discussion)

When presenting data, it’s key to guide your audience through a chart as you would with text! In this viz, I enhance a basic heatmap and add features that guide attention towards specific perspectives to support a narrative!
Code + more: dontusethiscode.com/blog/202…
Of course everything you saw here was made entirely in @matplotlib - thanks for the SubFigures to help layout this "poster"!


My favorite, funniest looking import I use since I keep replacing things I used to do in @pandas_dev with @DataPolars for data processing.
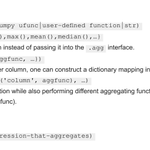
That said, @pandas_dev is still an incredibly flexible tool with many diverse/useful functions making it a true data swiss-army knife.

Cameron Riddell retweeted

@RiddleMeCam gave a great talk on Data Visualization in @matplotlib from the #CognitiveScience perspective.
youtu.be/MYzOum-7VGo
Why do I always say you need good Python skills to make the most of your @pandas_dev and @DataPolars data tools?
Let's take a convenient SQL feature as an example: groupby sets, rollup, and cube. These aren't implemented these Python DataFrame libraries...

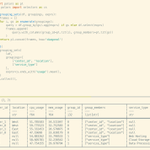
Convenience: Finally let’s insert these into a more ergonomic API, we can use its registration mechanism to implement something that builds upon the existing style of Polars and is relatively self-contained.

If you liked this thread, then take a more in-depth look at my blog post on this topic: dontusethiscode.com/blog/202… where show these patterns in DuckDB and recreate them in both Polars and pandas.
I love using both @pandas_dev and @DataPolars, but I will say that in terms of a consistent API, @DataPolars `group_by` context + expressions really takes the cake.
See the rest of this comparison for group & window functions on my most recent blog post: dontusethiscode.com/blog/202…

Cameron Riddell retweeted

Hey folks, can you do us a favor? If you're doing (or know about) NASA funded work using us, can you let us know? Thanks!
Exploratory data visualization is much more than just "putting data on the screen." When you visualize data you facilitate the obvious comparisons, and it is important to be intentional with what is obvious. 🧵
dontusethiscode.com/blog/202…


By removing some (colorful) noise from our visualization, we can supplement information through that same channel, such as highlighting the maximum value within each month without re-introducing visual competition.
There are many ways one can provide intentionality in data visualization, the important thing is to begin thinking critically about what you want to visualize and how you can support that goal.
Check out recent blog post for more on this topic
dontusethiscode.com/blog/202…