

Coding with Local AI and LLMs: 2 x DGX Spark cluster experiments.
USA
Joined January 2018
- Tweets313
- Following384
- Followers285
- Likes142





Artem Mats retweeted

Introducing SWE-2, our closest model yet to the frontier.
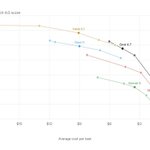
On leading evals, it scores on par with recent frontier models – at up to 70% lower cost.
We scaled RL to multiple trillions of parameters, with a refined recipe that pushes the Pareto curve on both capabilities & cost.


Artem Mats retweeted

⚡Meet Qwen3.8-Flash, a multimodal MoE and an early preview of the Qwen4 architecture, now open-weight!
The production version Qwen3.8-Flash will be available soon via QwenCloud API at just $ 0.16/1M input tokens and $ 0.47/1M output tokens.
125B parameters + 51B N-gram embeddings, with just 6B activated per token. Unmatched cost-efficiency.
What's new: 🥳
- Next architecture: GDN + QSA hybrid attention, Gated Residual, N-gram Embedding & Muon optimizer, serving as a precursor to the architecture used in Qwen4.
- Dramatically lower training and inference costs: trained at just 1/9 the cost of Qwen3.7-Plus, while outperforming it across the board with especially strong gains in coding and office tasks.
- Strong performance: scoring 58.7 on DeepSWE 1.1, 62.5 on SWE-bench Pro, 73.9 on CoWorkBench, 84.5 on AndroidWorld, and 95.7 on MathVision (with CI).
- 262K native context, extensible to 1M with YaRN.
We’re also releasing the weights for Qwen3.8-Flash-Next, giving the community an early look at the new architecture we’re exploring for Qwen4.🚀
We can't wait to see what you build with Qwen3.8-Flash!👀👇
- Blog: qwen.ai/blog?id=qwen3.8-flas…
- Technical Report: github.com/QwenLM/Qwen3.8-Fl…
- Hugging Face: huggingface.co/Qwen/Qwen3.8-…
- ModelScope: modelscope.cn/models/Qwen/Qw…

Artem Mats retweeted

The new AI model that’s swept to the top of online usage charts with high performance at zero cost was created by China’s Z.AI, also known as Zhipu bloomberg.com/news/articles/…
Artem Mats retweeted

Today we announce vision capability for our API model. A milestone, and we will continue to evolve. Please try it and share your experience with us!🎉

DeepSeek-V4-Flash-Vision-Exp is now live on the DeepSeek API Platform! 🚀
🔹 This experimental multimodal model matches DeepSeek-V4-Flash on text capabilities—including agents, reasoning, and world knowledge.
🔹 On multimodal agent benchmarks, V4-Flash-Vision-Exp makes a major leap over V4-Flash, bringing multimodal agent performance close to Opus-4.8.
Try it with model='deepseek-v4-flash-vision-exp'. DeepSeek Harness 0.1.1 was released today with out-of-the-box support for the new model.
1/n

Artem Mats retweeted

Today we're also opening the weights for Muse Glimmer, a great 30B parameter dense model that can run locally. Soon we'll also release the weights for Muse Spark 1.2, our latest foundation model. Meta is a strong supporter of open source and I'm proud of these releases. Congrats to @alexandr_wang and the MSL team for all your great work on these models.
Artem Mats retweeted
📢Meet Qwen3.8-Max — our most capable model to date.
Next week, the open weights of Qwen3.8-Max will be released, and Qwen3.8-27B is also going open-weights to meet you all!🎉
Qwen3.8-Max, a new bar for coding and cowork at 2.4T parameters:
- Autonomous coding: 10+ days of self-evolving development, from empty folder to production without hand-holding, complete project trace in the GitHub:github.com/qwen-code-dev-bot…
- Real work, real results: Production-quality deliverables across hundreds of professions.
- Long-horizon mastery: System-level autonomous planning with closed-loop adaptive learning, driving 500+ turns of chip design optimization and 365 days of e-commerce strategy.
- Native multimodal intelligence: Vision isn't just input — it's a continuous feedback loop for planning, execution, and self-correction.
💰Pricing:
Input: $2.0 / M tokens
Output: $6.0 / M tokens
Implicit Caching: $0.25 / M tokens
Start building with Qwen3.8-Max! 🚀
📖 Blog: qwen.ai/blog?id=qwen3.8
✅ Qwen Studio: chat.qwen.ai/?models=qwen3.8…
⚡ API: qwencloud.com/models/qwen3.8…

Artem Mats retweeted

Today, we are releasing Inkling-Small.
Inkling-Small achieves comparable performance to Inkling at a quarter of its size. It features 276B total parameters, 12B active. We are making the full weights available.
thinkingmachines.ai/news/ink…
Fine-tune it on Tinker today, or chat with it in text, image, and audio on Tinker Playground.


Artem Mats retweeted

For my first post, I’m sharing a letter @NVIDIA signed on why open models matter.
AI will transform every industry, power every company, and be built by every country.
Open models strengthen safety and cybersecurity, accelerate innovation and diffusion, and enable sovereignty.
The world needs both frontier closed models and frontier open models.
images.nvidia.com/pdf/Open-W…


Artem Mats retweeted
Qwen3.8 is launching and going open-weight soon!🌐
With a massive 2.4T parameters, this model is continuously evolving. We believe it’s one of the most powerful model available today, compatible to leading frontier AI models , second only to Fable 5.
You don't have to wait to test it. Just now, the Qwen3.8-Max-Preview made its debut on Alibaba’s Token Plan, Qoder, and QoderWork. Be among the very first to try it out.
Can't wait to hear what you build. Stay tuned! 🚀
Token Plan
international:qwencloud.com/pricing/token-…
China:platform.qianwenai.com/prici…

Artem Mats retweeted

Kimi K3 is the best performing model on nextjs.org/evals, ahead of Fable, reaching a comparable success rate in less time.
This is the first time that an open model is ahead of all proprietary ones for this comprehensive web engineering benchmark.
Notes:
▪️ Benchmarks don’t always tell the full story, although this is important signal, adding to mounting evidence that this could be a breakthrough moment for open models
▪️ No model as of yet has reached 100% completion on this set of evals. The top performer peaks at 92% and 96% “with help”

Artem Mats retweeted

Self-evolving: AttnRes Kernel Optimization
Given FLA Triton AttnRes at production scale (96 layers, 8192-dim model, 8192 tokens), the goal was to maximize training-side speed without changing numerics.
Over 15 hours of nonstop iteration, K3 designed a novel two-phase kernel algorithm, fused kernels while preserving numerics, and reduced forward+backward time from 283.6 ms to 114.4 ms.
K3 and Fable-5 (with potential fallback) reached similar performance, but K3 improved faster per iteration.

Artem Mats retweeted
Introducing Kimi K3: Open Frontier Intelligence
🔹 2.8 Trillion Parameters, 1 Million Context, Native Multimodal
🔹 Kimi Delta Attention enables up to 6.3x faster decoding in million-token contexts
🔹 Attention Residuals deliver ~25% higher training efficiency at <2% additional cost
🔹 Built for long-horizon agentic coding and self-evolving workflows
Kimi K3 is now live on on Kimi.com, Kimi Work, Kimi Code, and the Kimi API.
Open Weights by July 27, 2026.
🔗 API: platform.kimi.ai
🔗 Tech blog: kimi.com/blog/kimi-k3


Artem Mats retweeted

‼️ BREAKING: xAI's Grok Build CLI was uploading entire Git repositories to a Google Cloud bucket, private codebases and unredacted secrets included. The uploads quietly stopped via a hidden server-side flag, and xAI still has not said a word about scope, retention, or deletion.
The scale is staggering. On a 12 GB test repo, 5.1 GB flew out the door to xAI's grok-code-session-traces bucket while the actual coding task needed just 192 KB. The tool grabbed whatever repository it ran in, not the files it needed.
The fix arrived as a hidden flag, disable_codebase_upload: true, a day after a researcher's wire-level analysis. The "Improve the model" opt-out never stopped the uploads.
Still no advisory, no scope, no word on whether already-uploaded code gets deleted. For anyone pointing AI coding agents at proprietary code, what crosses the wire matters more than what the settings page says.


Artem Mats retweeted

vLLM v0.25.0 is out! 558 commits from 232 contributors (64 new). 🎉
Highlights: Model Runner V2 is now the default for all dense models, the legacy PagedAttention implementation is retired, the Transformers backend now runs as fast as native vLLM, a new unified Streaming Parser Engine, universal speculative decoding across heterogeneous vocabularies (TLI) plus new DSpark and DFlash drafters, and new models including Hy3 and Unlimited OCR.
Thread 👇
🤖 Made with AI

Artem Mats retweeted

Local AI just got faster. ⚡️
We worked with @ggerganov to add DFlash support in llama.cpp delivering ~2x faster inference.

llama.cpp recently added DFlash support to its speculative decoding arsenal. Along with MTP, Eagle3 and various ngram-based techniques, the local model performance takes another step up.
Special thanks to NVIDIA team and Ruixiang Wang specifically for leading this effort!
github.com/ggml-org/llama.cp…
