

Senior research scientist at @LosAlamosNatLab. Former prof at @ucl and @UTAustin. CogSci, AI, Comp Neuro, AI for scientific discovery Also @profdata on Bluesky
London, UK
Joined September 2014
- Tweets1.4K
- Following1.6K
- Followers5.9K
- Likes1.8K




Pinned Tweet
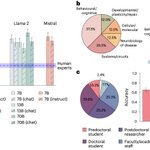
"Large language models surpass human experts in predicting neuroscience results" w @ken_lxl and BrainGPT.org. LLMs integrate a noisy yet interrelated scientific literature to forecast outcomes. nature.com/articles/s41562-0… 1/8

Last month Dawkins declared Claude conscious and was mocked. @GaryMarcus cleverly called it The Claude Delusion. My (and Nagel's?) take: Both are wrong for the same reason. Here's an essay on why machine consciousness will never be settled scientifically. arxiv.org/abs/2606.00226

Bradley Love retweeted

Every time you experience something new, your brain faces a decision: Should it update an existing memory or create a new one?
In our new paper in @JNeurosci, we isolate that exact decision, moment-by-moment during learning. 🧵

Are you a graduate student interested in working at Los Alamos National Laboratory (LANL) this summer? LANL has student internships, apply here: lanl.jobs/search/jobdetails/… 1/2


"The inevitability and superfluousness of cell types in spatial cognition". Intuitive cell types are found in random artificial networks using the same selection criteria neuroscientists use with actual data. elifesciences.org/reviewed-p…... 1/2
Intuitive cell types don't necessarily play the ascribed functional role in the overall computation. This is not a message the field wants to hear as it suggests better baselines, controls, and some reflection. elifesciences.org/reviewed-p…... w @ken_lxl , @robmok.bsky.social @ 2/2
Exciting "new" work illustrating our broken publishing system. @seb_bobadilla presented this work online at neuromatch 2.0 at the height of the pandemic. Then, @xinyazhang_ worked years on addressing reviewer comments, which added some rigor but didn't change the message. 1/2
Working with monkey data, we found neural representations stretched across brain regions to emphasize task relevant features on a trial-by-trial basis. Spike timing mattered over spike rate. Deep nets did the same. nature.com/articles/s41467-0… 2/2

When AI surpasses human performance, what's left for humans? We find that human judgment boosts performance of human-AI teams because humans and machines make different errors. cell.com/patterns/fulltext/S… 1/2

We developed a straightforward method of combining confidence-weighted judgments for any number of humans and AIs. w @yanezlang, Omar Minero, @ken_lxl 2/2

Bradley Love retweeted

Researchers are using LLMs to analyze the literature, brainstorm hypotheses, build models and interact with complex datasets. Hear from Martin Schrimpf @martin_schrimpf, Kim Stachenfeld @neuro_kim, Jeremy Magland, Bradley Love and others.
thetransmitter.org/machine-l…

Bradley Love retweeted

🧵🎉 Our mega-paper is finally published in TMLR! We're "Getting Aligned on Representational Alignment" - the degree to which internal representations of different (biological & artificial) information processing systems agree. 🧠🤖🔬🔍 #CognitiveScience #Neuroscience #AI

Bradley Love retweeted

What futures could, and should, we create with advanced AI? Today we are announcing two possible paths – Tool AI and d/acc – with contributors like @VitalikButerin @owocki @AdamMarblestone and @AnthonyNAguirre
New blog w @ken_lxl, “Giving LLMs too much RoPE: A limit on Sutton’s Bitter Lesson”. The field has shifted from flexible data-driven position representations to fixed approaches following human intuitions. Here’s why and what it means for model performance bradlove.org/blog/position-e…

New blog, "Backwards Compatible: The Strange Math Behind Word Order in AI" w @ken_lxl. It turns out the language learning problem is the same for any word order, but is that true in practice for large language models? paper: arxiv.org/abs/2505.08739 BLOG: bradlove.org/blog/prob-llm-c…

ALT https://bradlove.org/blog/prob-llm-consistency
"Probability Consistency in Large Language Models: Theoretical Foundations Meet Empirical Discrepancies"
Oddly, we prove LLMs should be equivalent for any word ordering: forward, backward, scrambled. In practice, LLMs diverge from one another. Why? 1/2 arxiv.org/abs/2505.08739
When LLMs diverge from one another because of word order (data factorization), it indicates their probability distributions are inconsistent, which is a red flag (not trustworthy). We trace deviations to self-attention positional and locality biases. 2/2 arxiv.org/abs/2505.08739
Bradley Love retweeted

🧠 We speak with Prof. Bradley Love about BrainGPT—an AI model helping researchers process neuroscientific data faster than ever.
🔍 How does BrainGPT work?
🚀 Where is AI taking brain research next?
🎧touchneurology.com/podcast/b…
@ProfData
