
https://xitter.cf/t.co/Bd2gisj8hY
Princeton, NJ
Joined March 2023
- Tweets59
- Following2
- Followers1.8K
- Likes2




Princeton Vision & Learning Lab retweeted

Researchers are actively improving memory for LLMs/VLMs. But are we measuring it right?
A system can score 100% by rereading the input for each question. If a human did that, we’d call it terrible memory!
We test beyond accuracy with ECC: Efficiency, Compression, Calibration. 🧵

We’ve released InFlux++, our unified data suite for training and evaluating dynamic intrinsics prediction models. See below for more info, or visit us in person at #ECCV2026!

Princeton Vision & Learning Lab retweeted

We have released an initial Infinigen2-Flying-Indoors dataset! It provides 2000 stereo videos, 24 frames each, with ground truth for depth, flow, normals, segmentation, albedo and more. Each group of 4 trajectories provides random synchronized views of the same procedural dynamic 3D scene.
Code to replicate it will be released soon as infinigen2.0.0a2. See full youtube preview & huggingface link below ↓
We've released a preview of Infinigen 2.0 - new high quality procedural materials and scenes with an efficient and controllable Python API. See below for info!

Princeton Vision & Learning Lab retweeted

Thrilled to share that I'll be joining the University of Michigan as an Assistant Professor in Fall 2027!
My lab will work on Robot Learning, Dexterous Manipulation, Robot Foundation Models & 3D Perception. I'm looking for students to join me. Please apply and reach out.
(1/2)


Princeton Vision & Learning Lab retweeted

Stereo depth is important in robotics, and relies heavily on synthetic data. But what actually makes for good synthetic data?
In WMGStereo, we study dataset design and discover a powerful data recipe - just 500 samples of our data can match 40k Sceneflow samples! 🧵[1/7]
Stereo depth is highly useful for robots. Meet WAFT-Stereo: #1 on ETH3D (BP-0.5), Middlebury (RMSE), and KITTI (all metrics); 61% less zero-shot ETH3D BP-0.5 error; 1.8-6.7x faster than prior SOTA. Key idea: classify disparity into bins, then iterative high-res warping.🧵1/2
Code: github.com/princeton-vl/WAFT…
Paper: arxiv.org/abs/2603.24836
🧵2/2

Meet WAFT (Warping-Alone Field Transforms), our new optical-flow estimator. #1 on public benchmarks (Sintel & Spring), 1.3-4.1x faster than leading methods, and 2x lower memory. Key idea: replace cost volumes with high-res feature-space warping. Code and paper:👇
Estimating camera intrinsics from video is key to 3D reconstruction, but most methods assume they’re fixed per video. What if the camera keeps zooming and refocusing?
Meet InFlux, the first benchmark with per-frame ground truth for videos with dynamic intrinsics. 🧵1/5
To construct this mapping, we use Hollywood-grade lenses that provide reliable lens metadata. We calibrate the lenses at many settings using multi-scale board and drone targets, and extract intrinsics via Kalibr, a toolkit we modified for improved robustness and accuracy. 🧵4/5
We tested 6 intrinsics prediction methods on InFlux. When projecting 3D points, even the best methods produced projections hundreds of pixels off.
Have a better method? Try our benchmark👇
🌐 Website: influx.cs.princeton.edu
📄 Paper: arxiv.org/abs/2510.23589
💻 Github: github.com/princeton-vl/InFl…
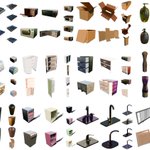
Major update to Infinigen Articulated (formerly Infinigen-Sim)! You can now generate articulated 3D objects in 18 categories, simulation ready with physics parameters and improved efficiency. Also available: 20k pre-generated objects. Download links below👇
Dataset: huggingface.co/datasets/prin…
Code: github.com/princeton-vl/infi…
Paper: arxiv.org/abs/2505.10755

Dataset: huggingface.co/datasets/prin…
Code: github.com/princeton-vl/infi…
Paper: arxiv.org/abs/2505.10755

🧵 Working on SLAM or Novel View Synthesis but need a new challenge? Try Princeton365, our new video benchmark built to push your model to the limit. It features reflective and transparent scenes, wild camera motion, night-time shots, flashing lights, video within video, and more, all with millimeter-accurate ground truth camera pose! (1/4)
Princeton365 opens new frontiers for Novel View Synthesis, providing 360 scans of reflective and transparent scenes with precise camera poses—data that were previously unavailable, as conventional tools like COLMAP fail to recover accurate poses in such conditions. (3/4)
Visit our website to try your SLAM/NVS method on Princeton365 and submit your results. See our paper for technical details ⬇️. Also, come visit our poster at ICCV 2025. (4/4)
Project Webpage: princeton365.cs.princeton.ed…
Paper: arxiv.org/abs/2506.09035
Code: github.com/princeton-vl/Prin…