

Tweeting papers & OSS projects advancing ML & data. Weekly newsletter with summaries: Curator @amplifypartners @sarahcat21.
San Francisco Bay Area
Joined January 2020
- Tweets663
- Following0
- Followers2.7K
- Likes430




📙 Agent Laboratory: Using LLM Agents as Research Assistants
Authors: @SRSchmidgall @thu_yushengsu @JoelLiu0501 @ZeWang1995 @xiaodi95 @Xiaodong_Yu_126 @XimengSun1 Zhicheng Liu, @EmadBarsoumPi
Paper: arxiv.org/abs/2501.04227

📙 Scaling Language-Free Visual Representation Learning
Authors:@DavidJFan @TongPetersb @JiachenAI @koustuvsinha @liuzhuang1234 @endernewton Michael Rabbat, Nicolas Ballas, @ylecun @_amirbar @sainingxie
Paper: arxiv.org/pdf/2504.01017
📙 Scaling LLM Test-Time Compute Optimally can be More Effective than Scaling Model Parameters
Authors: @sea_snell, @hoonkp, @imkelvinxu, @aviral_kumar2
Featured in PTK #127 bit.ly/ptk0127
Paper: arxiv.org/abs/2408.03314

📙 The Unreasonable Effectiveness of Easy Training Data for Hard Tasks
Authors: @peterbhase, @mohitban47, Peter Clark,
@sarahwiegreffe
Paper: arxiv.org/abs/2401.06751
Why Chatbots Are Not the Future by: Amelia Wattenberger
Featured in PTK #124 bit.ly/ptk0124
Post: wattenberger.com/thoughts/bo…
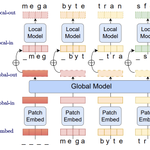
📙 MEGABYTE: Predicting Million-byte Sequences with Multiscale Transformers
Authors: Lili Yu, Dániel Simig, Colin Flaherty, Armen Aghajanyan, Luke Zettlemoyer, Mike Lewis
Featured in PTK #124 bit.ly/ptk0124
Paper: arxiv.org/abs/2305.07185

🖥️Guidance
Featured in PTK #124 bit.ly/ptk0124
Code: github.com/microsoft/guidanc…
Blog: towardsdatascience.com/the-a…
Large sequence models for software development activities by: Petros Maniatis, Daniel Tarlow
Featured in PTK #124 bit.ly/ptk0124
Blog: ai.googleblog.com/2023/05/la…

🖥️ Git-Theta by: @kandpal_nikhil, @blester125, @Muqeeth10, @anisham197, @montymevans, Vishal Baskaran, @TenghaoHuang45, @liu_haokun, @colinraffel
Featured in PTK #124 bit.ly/ptk0124
Code: github.com/r-three/git-theta
Paper: arxiv.org/abs/2306.04529
📙 Reflexion: Language Agents with Verbal Reinforcement Learning
Authors: @noahshinn024, @ellev3n11, Beck Labash, @ashwingop, @karthik_r_n, @ShunyuYao12
Featured in PTK #124 bit.ly/ptk0124
Paper: arxiv.org/pdf/2303.11366.pdf
Code: github.com/noahshinn024/refl…
Open Vector Data Lakes by: Ziheng Wang
Featured in PTK #124 bit.ly/ptk0124
Post: blog.lancedb.com/why-datafra…
🖥️ QLoRA by: Tim Dettmers, Artidoro Pagnoni, Ari Holtzman, Luke Zettlemoyer
Featured in PTK #124 bit.ly/ptk0124
Code: github.com/artidoro/qlora
📙 How Far Can Camels Go? Exploring the State of Instruction Tuning on Open Resources
Featured in PTK #124 bit.ly/ptk0124
Paper: arxiv.org/pdf/2306.04751.pdf
Enterprise Restaurant Compute by: Brian Chambers, Chick-fil-A
Featured in PTK #121 bit.ly/ptk121
Post: medium.com/chick-fil-atech/e…
🖥️ Zeno
Featured in PTK #121 bit.ly/ptk121
Code: github.com/zeno-ml/zeno
📙 Parsel : A (De-)compositional Framework for Algorithmic Reasoning with Language Models
Authors: Eric Zelikman, Qian Huang, Gabriel Poesia, Noah D. Goodman, Nick Haber
Featured in PTK #121 bit.ly/ptk121
Paper: arxiv.org/pdf/2212.10561.pdf

🖥️ 𝗗𝗦𝗣: The Demonstrate–Search–Predict Framework by: Omar Khattab, Keshav Santhanam, Xiang Lisa Li, David Hall, Percy Liang, Christopher Potts, Matei Zaharia
Featured in PTK #121 bit.ly/ptk121
Code: github.com/stanfordnlp/dsp
Paper: arxiv.org/pdf/2212.14024.pdf
📙 Toolformer: Language Models Can Teach Themselves to Use Tools
Authors: @timo_schick @JaneDwivedi @robdessi @robertarail @MariaLomeli_, @LukeZettlemoyer Nicola Cancedda, @ThomasScialom
Featured in PTK #121 bit.ly/ptk121
Paper: arxiv.org/abs/2302.04761
A Twitter Thread from Neeva
Featured in PTK #121 bit.ly/ptk121
Thread: xitter.cf/neeva/status/162264044…

1/ NeevaAI serves abstractive summaries of web pages that are generated in real-time.
We achieved this by a ~10x reduction in latency of a fine-tuned t5-large encoder-decoder model.
TY @asimshankar, @rajhans_samdani, @AshwinDevaraj3 + @spacemanidol
See our lessons learned.. 🧵
🖥️ iWF by: Indeed
Featured in PTK #121 bit.ly/ptk121
Code: github.com/indeedeng/iwf
