






ᮕᮅᮞ᮪ retweeted

I really missed the hours before a DeepSeek release.
It's one of the last remaining joys I have in this space.
Other Open Weights models first tease, then ship a week or month later.
US Closed Source ship the best state of the model, collect the PR and slightly nerf the model weeks or month later.
ᮕᮅᮞ᮪ retweeted
A ‘RED RISING’ movie is in the works at Paramount
• Francis Lawrence (‘The Hunger Games: Catching Fire’) set to direct
• The story follows a young miner living on Mars who attempts to bring down the color-coded class system
(Source: hollywoodreporter.com/movies…)


That sequence when the howlers chasing after Adrius in the snow is giving goosebumps. I hope they executed this well. My favorite fiction book series

A ‘RED RISING’ movie is in the works at Paramount
• Francis Lawrence (‘The Hunger Games: Catching Fire’) set to direct
• The story follows a young miner living on Mars who attempts to bring down the color-coded class system
(Source: hollywoodreporter.com/movies…)
Also very impressive how many models and post training iteration they've done this year with the amount of compute they have. V4 preview, V4, V4 0731, V4.1, and now this for both Flash and pro model. Can't wait when the first phase of 1gw data centers coming online, 160k 950DT.
ᮕᮅᮞ᮪ retweeted

🚀 Today's DeepSeek Harness 0.2.1 release supports the new DeepSeek-V4.1-Flash-1017 model. The new model was specifically optimized for @DeepSeekHarness during training, improving task performance while shortening task runtime and reducing output usage and token costs. To take full advantage of the new model’s capabilities, please upgrade to DeepSeek Harness 0.2.1-rc.1 or later.

🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4


ᮕᮅᮞ᮪ retweeted

Oh wow. DeepSeek V4.1 Flash 1017 varies much more than usual. After three runs:
Muse Wonder Full 1.0 (max): 42
Opus 5.5 (max): 41.7
Gemini 4 Argon (high): 40.7
DeepSeek V4.1 Flash 1017 (max): 38.7 🟣
Grok 4.7 (xhigh): 29
Qwen3.8-Max (max): 25.7
DeepSeek V4.1 Flash (max): 21.7 🟣
GLM-5.3 (max): 19
Individual scores: 34, 37, 45
Next: high effort level, n=3
Later: low effort level, n=3
Last: n=5 for max, just in case

Models became so good that I don't even bother to compare or switch to SOTA model anymore. I can't tell the difference in my use case(except for three js twitter demo, maybe) hahah
🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4
ᮕᮅᮞ᮪ retweeted

Many people on this website don't understand that "totalitarian communism" is one of the relatively good scenarios even among the bunch where we don't get steamrolled by AI. The bigger risk is speciation. Dorks like Roon become Gods forging universes. Plebs stay as monkes.

ᮕᮅᮞ᮪ retweeted
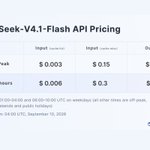
💾 Smaller KV cache. Bigger savings.
Compared with the previous generation, V4.1-Flash’s KV cache needs just:
🔹 1/4 the HBM
🔹 1/8 the SSD storage
Cache-hit charges often account for a large share of agent costs. Compressing the cache cuts those costs significantly.
3/6

ᮕᮅᮞ᮪ retweeted
🚀 Introducing DeepSeek-V4.1-Flash: smarter, faster, more efficient.
🔹 Introducing the smallest model in our new architecture family, with native visual understanding.
🔹 Designed for greater capability, faster inference, higher throughput, and scaling to larger models.
1/6


