

Purpose-built AI infrastructure for token factories. NR-NEXUS and NR2 AI-SuperNIC maximize GPU utilization, lower cost per token & scale inference efficiently.
AI Infrastructure
Joined September 2025
- Tweets76
- Following392
- Followers47
- Likes16.1K
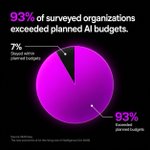


93% of organizations in a McKinsey survey are already over budget.
Spend can nearly quadruple as companies move to enterprise deployment.
Anthropic's IPO filing discloses that Broadcom will lend it up to $42B to finance leased compute capacity.
The more capital tied up in AI infrastructure, the more every idle GPU and inefficiently served token matters.

More compute doesn't mean more token output.
Our VP of BD Gaurav Shah explains why in @RTInsights:
"Communication is no longer adjacent to compute but has become part of the compute path itself."
In scale-out AI clusters, the real question is how much of your compute is actually working.
Faster GPUs make the problem worse. The more compute you add, the more time it spends waiting on data.
Unless your NIC is built for AI.
Read more👇
AI clusters are filling up with chips that don't share a protocol.
On the SemiWiki Semiconductor Insiders Podcast with @DanielNenni, our CEO @MosheTanach laid out what this costs.
Google runs Falcon.
Microsoft's Maia uses its own RoCE-like protocol.
Nvidia spans NVLink, InfiniBand, and RoCE, and has now absorbed Groq's inference silicon.
Meta has their own RoCE (MetaRoCE).
Mix them in one cluster and something has to translate between them. Every hop through a separate bridge costs latency.
Our NR2 AI-SuperNIC runs one programmable transport engine.
Protocols load in software. RoCE and Ultra Ethernet today, and the engine is programmable enough to take others.
Conversion happens in the NIC instead of a separate hop.
Full conversation linked 👇

Orr Mazor, one of our ML engineers, got NVIDIA and AMD to serve the same inference request.
Prefill ran on an NVIDIA H100.
Decode ran on an AMD MI300X.
Prefill is compute-bound.
Decode is bound by memory bandwidth.
Splitting across vendors also means capacity can come from more than one supply channel, which matters when specific GPUs are scarce.
Read the full blogpost 👇

This week NeuReality hit the beach 🏖️
We take our mission seriously, but also know when to step outside and spend quality time together.
Good food and games, ice baths, professional massages, and plenty of laughs.
A great day with the team, and a great way to head into the new year.
Wishing everyone a Shana Tova U’Metuka, and a happy, healthy and sweet new year with family and friends! 🍎🍯


Ronli Vignanski from our ML team reproduced and beat InferenceX's DeepSeek V4 Pro benchmark on 8xB200.
The story behind it:
Three Dynamo images.
Two weeks.
One bottleneck, and it wasn't the GPU.
Check out the full write-up here 👇


Talented NeuReality ML engineers Or Zipori and Ronli Vignanski spent 10 minutes with Adam Yap at @ipxchangetech explaining NR-NEXUS.
Teams running inference in production today must choose between a closed API, where cost, privacy, SLOs, and the data path are someone else's decisions, and building the stack themselves, which becomes a second full-time job for engineering.
A better option is NR-NEXUS, our inference operating system for production token factories.
Pre-deployment SLO validation is one piece: it confirms the target is achievable on the hardware you already own, before any traffic goes live.
Most teams find that out in production instead.
The gross margin pyramid is upside down.
SaaS normally runs 90%. Hardware runs 50-60%.
Right now NVIDIA takes 75% on AI chips while many Gen AI and SaaS companies sit at zero.
Neoclouds keep raising to build more hardware they can't fully utilize. Our CEO @MosheTanach's take: the ones still standing once the market settles will be the ones with margin.
Full conversation with @DanielNenni on the Semiconductor Insiders Podcast 👇

At Ai4, one thing came up in nearly every conversation:
GenAI, SaaS, and enterprises running production inference at scale are moving from closed models to a mix of closed and open models (Kimi, Qwen, DeepSeek, Mistral, etc.).
Why? Price and utility.
We presented NR-NEXUS, our inference operating system for production token factories.
NR-NEXUS helps you simplify inference serving and model deployment, and makes it easier to move from closed APIs to open models without building the serving layer yourself.
You set the SLO for each use case, and the NR-NEXUS Planner shows you the deployment plan and expected performance.
The result: more tokens from your existing hardware fleet. And you know before you deploy.

You can't GPU your way out of an inference problem.
In his latest @CIOonline article, our CEO @MosheTanach explains why AI infrastructure needs a new operating model.
One built around efficient inference, intelligent orchestration, and measurable business outcomes.
As AI moves into production, success depends on how effectively organizations manage the entire inference stack.
If you're a CIO or infrastructure leader planning for the next phase of enterprise AI, this is worth a read.
cio.com/article/4204565/why-…

One GPU fleet.
Every department running whichever models fit their workload, at the same time, fully governed.
No silos, no separate clusters per team.
Exponentially more concurrent AI sessions on the same GPU fleet.
NR-NEXUS is the inference operating system for production AI.
Deploy your token factory on your existing hardware, on-prem, in the cloud, or hosted by a third party, and be up and running the same day.
AI clusters shouldn't be limited by general-purpose networking.
In this conversation with @thinkonpaperpod, our CEO @MosheTanach explains why NeuReality took a different approach.
Most NICs are built to handle storage, virtualization, and a wide range of network functions.
In an AI cluster, most of that hardware goes unused.
NeuReality's NR2 AI-SuperNIC is built for GPU scale-out and scale-across.
Less than half the latency and less than half the power draw of today's best-in-class NICs.
GPUs spend more time computing and less time waiting on the network.
Full conversation with Thinking On Paper in the thread below 👇
🎧 Full episode: pod.link/1713227258/episode/…
Hosted by @markfielding99 and Jeremy Gilbertson of Thinking On Paper

One AI prompt. A trillion parameters. Thousands of GPUs talking to each other in under a second.
Our CEO @MosheTanach breaks down what actually happens the moment you hit send on this episode of @thinkonpaperpod.
A single request doesn't hit the model once. It queries the model, pulls the relevant slice of data from inside it, then goes back in with that extracted context to ask again, sometimes several times, before it has enough to generate your answer.
That's because the model itself is enormous: a trillion or more parameters split into "mixture of experts," smaller groups of specialized knowledge.
No single GPU can hold it. So the model gets spread across many GPUs at once, each one handling a different piece, all coordinated over the network in real time so nothing sits idle waiting to reload.
Storage, network, GPUs, and CPUs all fire in sequence for every single prompt you send.
It's a clear explanation of a process most people never think about.
An excellent, wide-ranging interview about the infrastructure and economics of AI with our CEO @MosheTanach 🔥

AI agents don’t just need GPUs. They need CPUs to run the software and NICs to move data between processors.
Fast NIC, busy GPU.
Slow NIC, and your AI moves like an old duck in a heatwave.
Moshe Tanach explains it on Thinking on Paper.
thinkingonpaper.xyz/episodes…
