

Tinkering. Culture Maxi. ❤️ Artists
nameet@muzify.com
Joined April 2009
- Tweets22K
- Following6.1K
- Followers15K
- Likes23.6K




Pinned Tweet
I really wanted to find 1 new song that I could vibe with, every day.
Couldn't find a product that did this, so we BUILT one.
3 new songs. 10 AM. Daily.
Available only for Apple Music users. DM me and I'll share the app link.
The more music you listen to on @AppleMusic, the better the recommendations get!
Spotify coming soon.


DeepSeek just priced AI like an electricity grid. Peak hours cost 2x.
The next valuable skill isn't asking faster. It's being able to wait. Urgency just became a luxury good.


Full breakdown vs the field:
pdfmux: 0.905 (free, CPU)
docling: 0.877
marker: 0.861
mineru: 0.831
We now beat Docling on tables too (0.911 vs 0.887) and Docling is a dedicated ML table extractor.
github.com/NameetP/pdfmux

We also trained a tiny ML heading classifier (sklearn, 212KB) as a fallback.
When font-size heuristics find zero headings on a page, the model gets a shot. It runs on 12 features — size ratio, bold, text length, y-position. No text content features to avoid overfitting.
Fixed docs that had no font-size variation at all.
The big unlock: image table OCR.
Some PDFs embed tables as images; literally, a screenshot of a table baked into the PDF.
Every extractor just... skips them. We don't anymore.
RapidOCR renders the image at 300 DPI, extracts text with bounding boxes, and then clusters by x/y coordinates to reconstruct rows and columns.
pdfmux v1.5.0 — now 99.5% of the #1 paid AI extractor. At zero cost per page.
0.905 overall on the 200-doc opendataloader benchmark.
Tables: 0.887 → 0.911
Headings: 0.844 → 0.852
Reading order: 0.918 → 0.920
98 docs improved. 3 regressed. Here's how 👇

new project — pdfmux
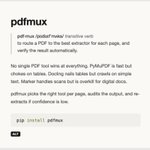
pdf·mux / transitive verb
to route a PDF to the best extractor for each page, and verify the result automatically.
No single PDF tool wins at everything. PyMuPDF is fast but chokes on tables. Docling nails tables but crawls on simple text. Marker handles scans, but is overkill for digital docs.
pdfmux selects the right tool for each page, audits the output, and re-extracts if confidence is low. It doesn't compete with these libraries; it orchestrates them.
Tinkerin. Still early but you can try it: pip install pdfmux

Nameet retweeted
The largest uncaptured lending market on earth has been mispriced for decades. Not because the risk was real because the infrastructure to read it didn't exist.
Wrote about what that looks like on the ground, through one woman in a town that doesn't appear in any fintech pitch deck.
open.substack.com/pub/sairee…

ALT A woman in a town you've never heard of built three businesses with no collateral, no credit history, and near-perfect repayment. What Tehseen reveals about the largest mispriced lending market on earth.
Nameet retweeted

For years, I’ve listened to @AcquiredFM and wondered: what capture’s the essence of emotion of Indian companies?
It’s the word धंधा. 'Business' is too cold. 'Trade' is too small. Dhanda is a life’s work.
It’s the soul of the Indian hustle, built on unique constraints, family legacies, and an audacity that borders on madness.
Today, I’m launching India’s first AI-led long-form podcast to tell those stories from the inside out.
From India, for the world. This is the origin story of our legends.
Here’s the trailer:
So @nathancgy4 the lead author of this paper is 16 🤓

Introducing 𝑨𝒕𝒕𝒆𝒏𝒕𝒊𝒐𝒏 𝑹𝒆𝒔𝒊𝒅𝒖𝒂𝒍𝒔: Rethinking depth-wise aggregation.
Residual connections have long relied on fixed, uniform accumulation. Inspired by the duality of time and depth, we introduce Attention Residuals, replacing standard depth-wise recurrence with learned, input-dependent attention over preceding layers.
🔹 Enables networks to selectively retrieve past representations, naturally mitigating dilution and hidden-state growth.
🔹 Introduces Block AttnRes, partitioning layers into compressed blocks to make cross-layer attention practical at scale.
🔹 Serves as an efficient drop-in replacement, demonstrating a 1.25x compute advantage with negligible (<2%) inference latency overhead.
🔹 Validated on the Kimi Linear architecture (48B total, 3B activated parameters), delivering consistent downstream performance gains.
🔗Full report:
github.com/MoonshotAI/Attent…

New: pdfmux now exports to JSON; because AI agents don't read PDFs, they parse them.
Real use case: extract every table from a 200-page SEC filing as structured JSON → pipe it straight into Claude for financial analysis.
No regex. No pandas. No prompt engineering to "find the revenue table."
Just: pdfmux 10-K.pdf -f json
new project — pdfmux
pdf·mux / transitive verb
to route a PDF to the best extractor for each page, and verify the result automatically.
No single PDF tool wins at everything. PyMuPDF is fast but chokes on tables. Docling nails tables but crawls on simple text. Marker handles scans, but is overkill for digital docs.
pdfmux selects the right tool for each page, audits the output, and re-extracts if confidence is low. It doesn't compete with these libraries; it orchestrates them.
Tinkerin. Still early but you can try it: pip install pdfmux
source + docs
github.com/NameetP/pdfmux
read more here
pdfmux.com/blog/real-world-p…