

Entrepreneur building safer AI | DevSecOps x LLMs
Tanzania
Joined November 2020
- Tweets4.4K
- Following1.9K
- Followers861
- Likes7.6K




"And he informed me, and talked with me, and said, ‘O Daniel, I have now come forth to give you skill to understand.’" Daniel 9:22
May God give us the skill to understand, and the grace to fulfill our purposes.
20
#swahilijs retweeted

We entered the era of custom inference engine vibe coding.
None of this would be possible without projects like SGLang, vLLM, and llamacpp.
We are so lucky they are open source.
#swahilijs retweeted

NVIDIA released a new looped transformer:
Instead of stacking more layers, it runs the same layers multiple times so a 4B model can think like a 9B one.
Here's how it works:
In a standard transformer, every token passes through a stack of decoder blocks once, and each block has its own weights.
So if you want a deeper model, you add more blocks, and the parameter count grows with the depth.
NVIDIA's Dory1.0-4B decouples the two by reusing a chunk of its layers.
The model is split into three parts:
> An input block of 8 blocks runs once and turns the tokens into a hidden state x.
> A recurrent block of 20 shared blocks runs k times, where k can be anywhere from 1 to 4.
> An output block of 8 blocks runs once on the final state, followed by the LM head.
Before every pass through the recurrent block, x is added back to the current state and the sum is L2-normalized.
This keeps the original token representation in view on every pass, instead of each pass only seeing what the previous one produced.
Both models in the diagram below store 36 blocks of weights.
The standard transformer applies each block once, while Dory applies 36 blocks at k=1, 56 at k=2, and 96 at k=4, i.e., 72, 112, and 192 physical layers from the same checkpoint.
The extra depth is actually helpful on reasoning and agentic tasks:
> SWE-bench Verified:
- at 1 loop → 50.3
- at 2 loops → 59.5
- at 4 loops → 61.8
> 12-benchmark average:
- at 1 loop → 35.17
- at 2 loops → 39.67
- at 4 loops → 40.60
- and with 2 or more loops, it beats Qwen3.5-9B, Gemma 4 12B, and Gemma 4 26B-A4B.
More loops implies more compute per token, but the 4-loop model also writes 1.3x to 2.5x fewer output tokens on agentic tasks.
So 2 loops end up costing only 1.03x to 1.25x the compute of 1 loop end to end, which is why NVIDIA recommends 2 as the default.
By default, Dory keeps a separate KV cache for every loop, so at 4 loops the recurrent layers store 4x the cache.
To avoid this, it can keep only the cache from the last loop, which uses the same KV memory as a normal model with only a small change in accuracy.
One thing to note here is that looping helps the model reason over what it already knows, but it does not add knowledge.
For instance, on tasks like AA-Omniscience, accuracy stays at 10.0 whether you run 1 loop or 4, and on knowledge-heavy tasks like GPQA, Dory still trails Qwen3.5-4B.
Here's the paper: arxiv.org/abs/2611.03998
That said, how much memory looping costs comes down to how the KV cache is handled, so I wrote a full breakdown of how KV caching works.
It covers what gets cached during prefill, how the cache grows during decoding, and why it becomes the main memory bottleneck at long context.
Read it below.


#swahilijs retweeted

Nothing exposes a fool faster than a conversation with someone who actually knows what they're talking about.


#swahilijs retweeted

Former Scale AI founder and newly appointed @Meta Chief AI Officer @alexandr_wang dropped a bombshell during his YC conversation with @garrytan, and you could almost hear the tech leadership world go quiet.
He said Meta has already seen this internally:
Build the right agentic loop, give it an evaluation system and metrics that let it optimize itself, and a group of AI agents can complete more work than a team of 100 senior engineers.
And they do it “very easily.”
But the most interesting part wasn’t the 100-engineer comparison.
It was how simple the system underneath it actually is.
You’d expect some insanely complex, almost alien architecture powering a swarm like this.
Instead, Wang described it with a few almost comically basic words:
“Markdown files, cron jobs, goal, metrics, data.”
Once you strip away the hype, the implications for traditional software engineering become pretty clear:
1️⃣ It’s not that the models are magically smarter. The eval loop is doing the heavy lifting.
Traditional approach: humans write prompts, run the code, inspect the output, and hope nothing broke.
Meta’s approach: turn the business goal into something a machine can score automatically.
The agent submits its work. The system runs tests, calculates metrics, finds what’s wrong, and sends it back for another pass. Repeat until it passes.
Nobody has to babysit every step. The metric becomes the supervisor.
2️⃣ The real alpha is burning 1,000x more tokens inside the feedback loop.
A lot of people are still optimizing for the cost of a single AI call.
The frontier labs are playing a different game: spend 1,000x or even 1,000,000x more tokens in the background so agents can constantly review, rerun, challenge, and verify each other’s work until they reach a reliable business outcome.
Token cost is fixed. The payoff is a pipeline that keeps running.
3️⃣ Memory doesn’t need some fancy database.
Persistent memory can live in Markdown files.
Scheduling can be handled by the server’s built-in cron jobs, running overnight.
The simpler the scaffolding, the more robust the system can be. Less infrastructure also means fewer ways for context to fall apart.
This is a pretty brutal change in how technical organizations work.
The ceiling for a tech lead used to be partly about how many people they could manage, how many meetings they could sit through, and how many teams they could coordinate.
The leverage for the next generation of technical leaders may look very different:
Can you turn a messy business objective into a rigorous set of metrics that an AI can evaluate automatically?
If 100 people’s output can be replaced by a few cron jobs, Markdown files, and a well-designed eval loop, the era of “just take the ticket and write the code” is coming to an end.
The people who can design the evals and orchestrate the swarm aren’t just holding a new tool.
They’re effectively running a virtual company.
#swahilijs retweeted

Google Brain founder Andrew Ng:
"Prompting will be dead in 6 months"
"Loops and graphs are replacing it"
In just 2 hours, he shows how to build agents that work, learn, and improve on their own
LLMs → Agents → Loops → Graphs → Self-Improving Systems
The first 15 minutes alone are more valuable than most $500 AI courses
Most people are still learning prompts while AI engineering is already moving beyond them
Watch the lecture first
Then read the full guide to loops and graphs below ↓
#swahilijs retweeted
Use PyTorch-native libraries within the NVIDIA NeMo Framework to customize models to hit your exacting requirements for latency, speed, memory, and compute.
@NVIDIA's blog demonstrates how quantization-aware distillation (QAD) improves the Nemotron 3.5 Lightning model using NVIDIA Model Optimizer. We walk through the entire training pipeline, and show how QAD consistently outperforms post-training quantization (PTQ) compression on agentic benchmarks, ensuring high quality while reducing memory usage.
Read it here: developer.nvidia.com/blog/de…

#swahilijs retweeted

NVIDIA CEO, Jensen Huang:
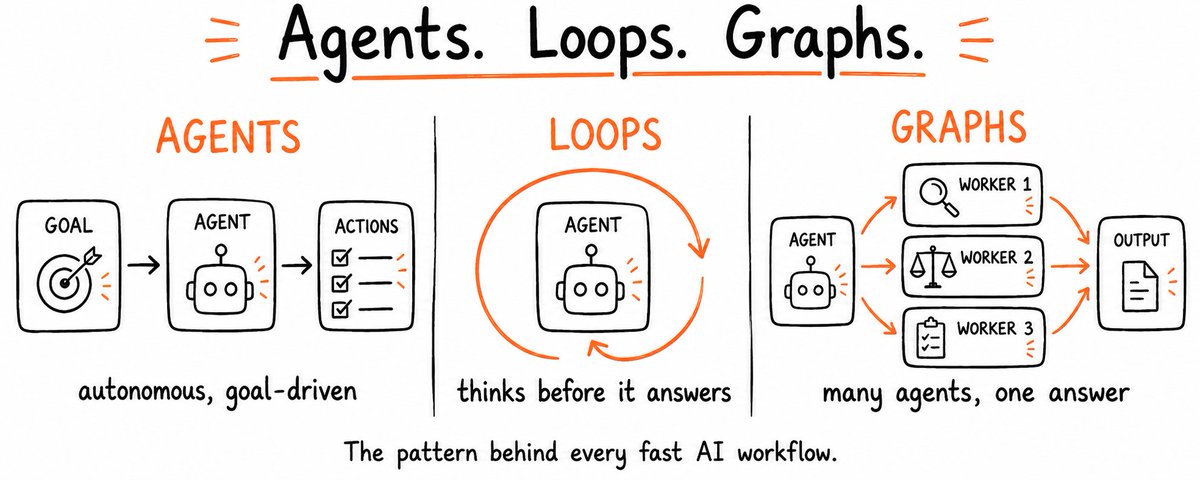
"Nobody writes prompts anymore. The new job is building Loops and Graphs."
In 50 minutes he explains why the engineers who stopped prompting are already years ahead, and what they're building instead.
The missing piece most people skip: loops handle the work, graphs handle the loops.
Watch it, then read the full guide on loops and graphs below.

#swahilijs retweeted

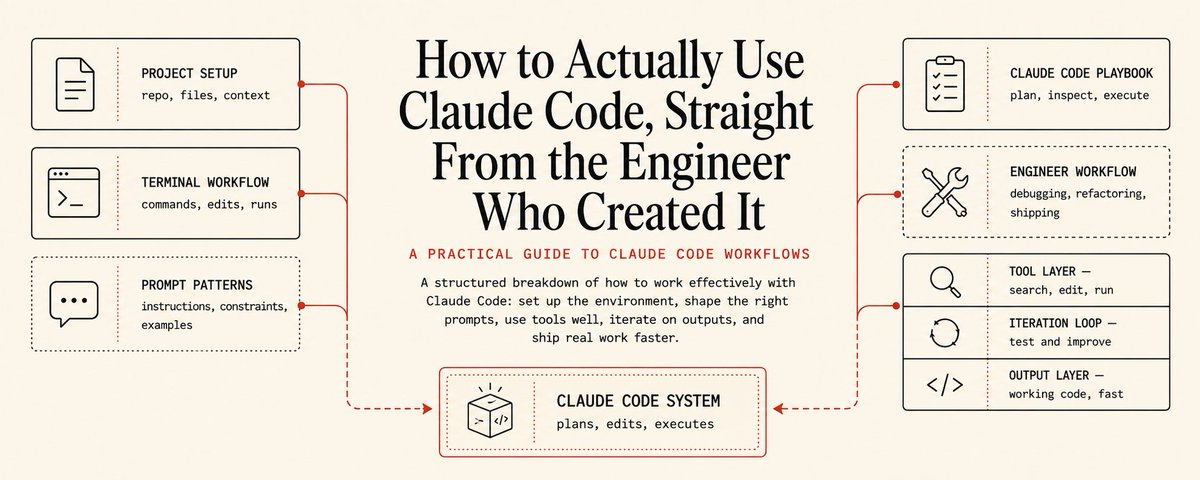
almost no ai engineers are talking about claude skills yet.
andrew ng just released a 2 hour collab with anthropic that walks you through building agentic skills from zero.
• 00:00 - getting started with agentic skills in claude
• 22:29 - using claude’s ready-made skills
• 41:04 - skills vs mcp and subagents
• 1:06:03 - designing skills for long-running agents
• 1:51:59 - live build: creating agentic skills end to end
prompting isn’t the main game anymore. claude skills is what serious builders are using to ship real agents.
i watched it last night.
somewhere in the middle it hit me: i’ve been treating claude like a chatbot, not an agent platform, for years.
save this and check the article below.

#swahilijs retweeted

INSTEAD OF WATCHING AN HOUR OF NETFLIX TONIGHT.
This 1-hour Stanford lecture by Joel Peterson will teach you more about negotiation and getting what you want than most people learn in years.
Bookmark it and give it an hour, no matter what.
#swahilijs retweeted

Just saw that the LLMs-from-scratch repository passed 100,000 stars on GitHub!
This is super cool and motivating. I am really happy to see that this open-source repo has helped so many people.
Thanks also to everyone who shared ideas and opened PRs with improvements!
Of course, I plan to keep adding new material, including new attention variants and architectures (while bigger projects like RL and Reasoning From Scratch live in their separate repositories).
I am also currently working on a larger applied custom “small” LLM project. It has been keeping me super busy this month, but I will share more on that soon.
If you are new to it, some of the highlights include
1. Of course, the complete code path from tokenization and attention to pretraining, classification, and instruction fine-tuning, etc. All of it FROM SCRATCH, of course! (RL lives in a companion repo.)
2. From-scratch implementations of Llama, Qwen, Gemma, and Olmo (smaller variants that run locally and can be plugged into the training scripts).
3. From-scratch implementations of attention alternatives and other architecture components, such as GQA, MLA, sliding-window attention, Gated DeltaNet, DeepSeek Sparse Attention, cross-layer KV sharing, and mixture-of-experts
4. Materials on KV caching, training performance, memory-efficient weight loading, DPO, evaluation, and LoRA
So, if you don’t have any weekend plans yet, happy tinkering!

#swahilijs retweeted

As a Machine Learning Engineer, you must build these projects.
Systems that prove you can ship models that scale.
1. End-to-End ML Pipeline
Build: Automated pipeline from data ingestion to model deployment using Airflow or Prefect.
Why: Shows you can operationalize ML not just train models in isolation.
2. RAG System with Evaluation Harness
Build: Retrieval-Augmented Generation with grounded citations and automated quality metrics.
Why: Proves you can build reliable LLM applications not just chat demos.
3. Real-Time Inference Service
Build: Low-latency API serving models with <100ms response time using vLLM or Triton.
Why: Demonstrates understanding of production performance constraints.
4. Feature Store Implementation
Build: Centralized store for feature engineering with point-in-time correctness and online serving.
Why: Shows you can handle data consistency between training and inference.
5. Model Monitoring and Drift Detection
Build: System to track data drift, concept drift and performance degradation in production.
Why: Proves you understand models decay and need continuous observation.
6. Distributed Training Setup
Build: Multi-GPU training pipeline using PyTorch DDP or DeepSpeed for large models.
Why: Shows you can scale training beyond single-machine constraints.
7. Model Registry and Versioning
Build: Centralized registry tracking model versions, metrics, artifacts and lineage using MLflow.
Why: Demonstrates reproducibility and governance capabilities.
8. A/B Testing Framework for Models
Build: System to route traffic between model versions and measure business impact statistically.
Why: Shows you can validate model improvements beyond accuracy metrics.
9. Vector Search Engine
Build: Similarity search over millions of embeddings with metadata filtering and hybrid search.
Why: Modern ML systems require semantic retrieval not just keyword matching.
10. Automated Retraining Pipeline
Build: Trigger-based retraining when data drift exceeds threshold or performance drops.
Why: Proves you can build self-healing systems that maintain quality over time.
11. Cost Optimization Dashboard
Build: Track inference spend per model, per endpoint, per user with anomaly detection.
Why: Engineering decisions impact profitability. FinOps is part of the job.
12. Security and Guardrails Middleware
Build: Input validation, prompt injection defense, PII redaction and output filtering layers.
Why: Security is non-negotiable. One breach destroys trust forever.
13. Multi-Model Router
Build: Dynamic routing system selecting models based on task complexity, cost and latency.
Why: Shows you can optimize tradeoffs not just default to the largest model.
14. Data Versioning System
Build: Implement DVC or LakeFS for tracking dataset versions alongside code versions.
Why: Reproducibility requires versioning data not just code.
15. Production Agent Orchestrator
Build: Multi-agent system with state management, tool use and human-in-the-loop approval.
Why: Agents are the future of ML applications. Orchestration is the moat.
Bookmark & Repost...
#swahilijs retweeted

Anthropic pays $750,000+ a year for engineers who can build LLM architectures from scratch. Stanford taught the entire thing in 1 hour lecture & released it for free.
Bookmark & watch this today before someone takes it down ...
#swahilijs retweeted
Anthropic has opened applications for its Fellows Program, a 4-month fully funded research opportunity offering approximately $15,400/month plus compute credits and direct mentorship from Anthropic researchers. Fellows can work in Berkeley, London or remotely, contributing to cutting-edge AI research.
The program covers AI safety, security, ML systems, reinforcement learning and AI policy & economics. No PhD or prior research experience is required but strong technical skills and full-time availability are expected. Applications are rolling for the September 2026 cohort.
Apply here : job-boards.greenhouse.io/ant…
