

Founder @fiberplane; autonomous software factories. Investor in teams solving hard problems @nphardvc.
distributed
Joined October 2006
- Tweets5.4K
- Following1.4K
- Followers2K
- Likes5.5K






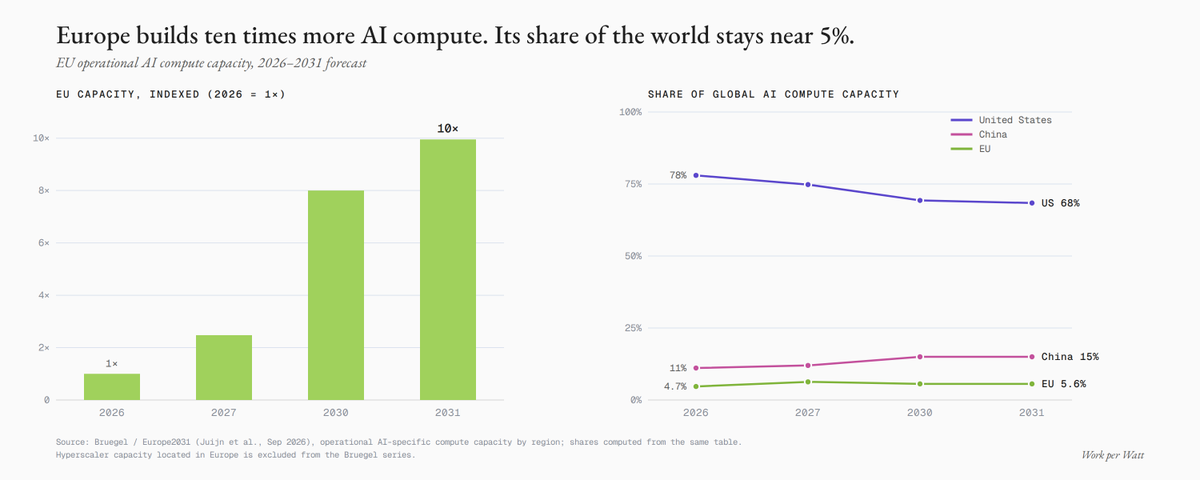
“Build or surrender: for now, the choice is still ours.” Good piece by @arthurmensch, and I'm with him on building (a lot!).
But the thing is that Europe isn’t going to out-spend the US on GPUs. The reality is that we have less capital, more expensive power, and fewer data centers. So building looks different in Europe. Every GPU and every watt we have needs to do more work than it does anywhere else.
If we get more work out of every watt, we don’t have to wait years for a grid connection to get there. We should still invest in power, obviously. But the reality is that new generation and grid capacity takes years, and we can’t afford to sit around and wait for them.
So this is where I’d put the effort now, and this is also where startups can shine.
Build different, do more with less 🇪🇺.

Coinbase made training a specialist model one command in their harness. My sense is that serving is where the work goes next.
If every company ends up with a handful of models like this, each one has its own latency target and its own scorer. A fraud model that has to answer in milliseconds and an overnight code-review model want different batching, and often different GPUs.
This means that a company's fleet ends up running many models on mixed hardware, with perhaps a frontier API kept for the cases nothing else passes. Serving all of that well is an interesting problem space.

We were able to fine tune an open weight model (Qwen3.5-9B) on proprietary internal data at @coinbase, and it out performed frontier models, at much lower cost and speed, for a specialized task (fraud prevention in this case).
I think we'll see more of this pattern inside companies. The frontier models are amazing generalists. But increasingly you'll see specialist models out perform on more narrow tasks, either working on teams, or by themselves.
We're making it easy to fine tune models internally for our employees. We even have a skill for it in our internal harness that makes it easy to spin these up and start training them:
"/fine-tune-and-serve-llm I want to fine-tune Qwen for payments risk review. help me get started"
I imagine we'll have some backend services that could be replaced entirely by this new architecture.


Look at those two lines together📈: the token index halved since May while B300 rent went up 38%. Whoever serves the model pays the GPU rent and gets paid per token. The only way through is more tokens out of every GPU-hour. In Europe, where adding GPUs takes years, that matters most...

Open-weight models that decrease margins at the model layer are positive for AI infra, exhibit 1001.2
Since the @silicondata “token index,” which captures both price and mix, peaked on May 31:
B300 prices are up 38%
B200 prices are up 10%
Other GPU indices are up *much* more.

$36B of neocloud backstops and $20B of DC leases to hand off to neoclouds. Nvidia now carries part of its customers’ demand risk. The question if that ever costs them anything depends on how busy those GPUs are.

Nvidia, in its most recent 10Q, disclosed $530B of gross off-balance sheet guarantees across six different line items – a jump from $184B of obligations disclosed in the prior quarter. The main drivers were increases in Supply Commitments - primarily commitments to buy memory, Datacenter backstops for SB Energy's PORTS-Pike campus in Ohio for OpenAI, as well as two new items - $36B of AI Cloud Agreements representing Neocloud Backstops and $20B of datacenter leases that Nvidia has taken out to later assign to Neocloud offtakers. (1/4)🧵

Agree on demand. The margin is the fun part though. Same weights, same GPUs, and the cost per finished task still swings a lot depending on the serving stack. Free weights turn it into an inference engineering problem imho.


In one quarter, open-weight models went from about 30% to a record 78% of the tokens on Vercel's AI Gateway.
That's just the one gateway, on a record day, and of course these tokens aren't 1:1 revenue. But the direction of travel is hard to miss. When you can just download the model, the margins move to the infra and inference layer.
A token starts to cost what it costs to serve, and the value moves to whoever runs the model best: fastest, cheapest, at the quality the job needs.
For Europe, this changes the equation. As long as the best AI was a closed API, "European AI" meant renting capability from a few US frontier labs, served from their infrastructure.
Open weights change that. The models doing most of the work (the "Work Horse") can now run on hardware Europe controls, under European rules. That doesn't directly make Europe competitive on its own. Where the models come from still matters, and unfortunately Europe has very little compute to run them on (more on that at a later time). But the question has moved from "who builds the model" to "who runs it best."


Looks like today may be a record day for token volume % of open models on Vercel AI Gateway:
🟦 Open 78.4% 🟨 Closed 21.6%
While spend 💲 usually tells a different story, #3 and #4 today are Moonshot AI & DeepSeek. Adding Z.ai, their combined spend surpasses OpenAI (#2).
(Do note that's the spend for inference of the model across providers (mostly in the US), not revenue going directly to the open weight labs.)

Micha "mies" Hernandez van Leuffen retweeted

Product release, specs, architecture, design choices for our 1MW synthetic natural gas system
rivan.com/rivan-deploys-full…

Extremely proud to have been backing this team from the very beginning with @nphardvc and this is a great time to join them on their mission! 🧱🤖🏘️

Today, we’re announcing an oversubscribed $32 million round at @BuildMonumental led by @khoslaventures, with participation from @pluralplatform and @HummingbirdVC.
Micha "mies" Hernandez van Leuffen retweeted

Super excited to join this round with @nphardvc !

Announcing our $320M Series A at a $2.3B valuation, led by @khoslaventures, with @generalcatalyst, @ericschmidt and @JeffBezos.
General Intuition is the frontier lab for acting in space and time.
We build large action foundation models trained on billions of ground truth action-labeled gameplay clips from 17M monthly active users on Medal, and push the frontier of world models to generate infinite training environments.
Shoutout to @daytonaio for organizing and @WorkOS for hosting a great night where builders gathered and of course giving us the opportunity to talk about how we're thinking about Autonomous Software Factories @fiberplane. Excellent conversations and new friends were made!


Check out our reference implementation called Otter, an opinionated monorepo template for autonomous agent workflows.
Ships with:
- @EffectTS_ conventions + ast-grep enforcement
- fp issue tracking with lifecycle hooks
- Drift documentation anchoring
- Agent skills pre-configured
Open Source repo here: github.com/fiberplane/otter

Micha "mies" Hernandez van Leuffen retweeted

This Tuesday we hosted our monthly @daytonaio AI Builders Meetup in San Francisco in partnership with @WorkOS & @coderhq.
We had an incredible lineup of speakers covering topics from forkable sandboxes for long-running AI agents and self-driving codebases to scaling AI workflows in production, building reliable code review agents, generative UI patterns, and the infrastructure powering agentic software systems.
Thanks to our speakers 🎤
@muhashmii × @daytonaio
@matt_md5 × @WorkOS
Jullian Pepito × @coderhq
@HKrackDev × @coderabbitai
@tyler_cpk × @CopilotKit
@mies × @fiberplane
Thank you to everyone who joined us. See you tonight at UC Berkeley for the AI Researchers Meetup!


Micha "mies" Hernandez van Leuffen retweeted

Otter: an opinionated monorepo template for autonomous agent workflows.
Ships with:
- @EffectTS_ conventions + ast-grep enforcement
- fp issue tracking with lifecycle hooks
- Drift documentation anchoring
- Agent skills pre-configured
Everything we learned building with agents in production, packaged as a starter template:
🔗github.com/fiberplane/otter