
Research Scientist @FacebookAI
San Francisco, CA
Joined October 2020
- Tweets87
- Following154
- Followers2.8K
- Likes190






Great progress by the team at Ello! Child speech is a very challenging but rewarding problem to work on! Looking forward to see the impact of Ello 2.0 and beyond!

Michael Auli retweeted

David AI has raised a $50M Series B from Meritech and NVIDIA to establish the data layer for audio AI.
Audio is the front-end interface for real-world AI. At David AI, we’re creating the data that powers the models bringing these use cases to life.
withdavid.ai/news/announcing…

We are releasing MMS Zero-shot: a model to transcribe the speech of almost any language using only a small amount of unlabeled text in the new language.
Paper: arxiv.org/abs/2407.17852
Demo: huggingface.co/spaces/mms-me…
Code/model: github.com/facebookresearch/…


Here is an exciting new brain computer interface challenge taking ASR to the next level! Consider participating!

We are publicly releasing all data and code, and are hosting a machine learning competition! Can you do better than us at translating neural activity into text? 2/3 eval.ai/web/challenges/chall…

The MMS TTS systems are now on HuggingFace! This is TTS for 1,107 languages.

🤗 Transformers just got 1100+ new TTS checkpoints 🚀
You can now run any of @MetaAI's MMS TTS checkpoints using the Transformers library in 3 lines of code⚡️
MMS is a the largest democratizer of TTS globally to date 🌎
Try it in your language now: colab.research.google.com/gi…

Excited to be at ICML 2023 where we will present our work on data2vec 2.0 on Wednesday (talk) and Thursday (poster): icml.cc/virtual/2023/oral/25…
@alexei_baevski @arunbabu1234 @mhnt1580

The MMS models are now available on HuggingFace!

Meta AI's recently released "Massively Multilingual Speech" (MMS) model is a huge step forward towards democratizing
Speech to every corner of the globe. In addition, it might also play a significant role in preserving global linguistic diversity.
huggingface.co/papers/2305.1…
👇

New work! The Massively Multilingual Speech (MMS) project scales speech technology to 1,100-4,000 languages using self-supervised learning with wav2vec 2.0.
Paper: research.facebook.com/public…
Blog: ai.facebook.com/blog/multili…
Code/models: github.com/facebookresearch/…
Compared to OpenAI Whisper, the multilingual ASR model supports 11x more languages but has less than half the average error rate on 54 languages of FLEURS. The model is also trained on a fraction of the labeled data (45K vs. 680K hours).


Michael Auli retweeted

We (@melbayad @MichaelAuli @EXGRV) have also worked on a very similar approach to adaptively change the depth of decoding for MT date back to ICLR2020 openreview.net/forum?id=SJg7…

Current LLMs expend the same amount of computation on each token they generate.
But some predictions are much harder than others!
With CALM, the authors redirect computational resources to "hard" inferences for better perf (~50% speedup)
ai.googleblog.com/2022/12/ac…
Here's how 👇
New work on efficient self-supervised learning: data2vec 2.0 pre-trains vision models 16.4x faster than the most popular existing algorithm.
Blog: ai.facebook.com/blog/ai-self…
Paper: ai.facebook.com/research/pub…
Code/models: github.com/facebookresearch/…
with
@ZloiAlexei @mhnt1580 @arunbabu1234

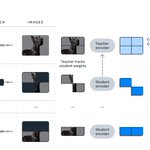
data2vec 2.0 pre-trains vision models to the same accuracy as MAE in 3 hours on a distributed training setup, or under 100 hours on a single A100 (not accounting for network overhead).
For speech it trains 10.6x as fast as wav2vec 2.0 and for NLP 2x as fast as RoBERTa.


Michael Auli retweeted

Join us for the Computer Perception virtual workshop at ECCV this Sunday (computerperception.github.io…). We will have keynotes from a wonderful set of speakers @orussakovsky, @AudeOliva, Matt Botvinick, @MichaelAuli, @dyamins, @JitendraMalikCV + talk about how to test perception.